Same prompts, same harness (opencode 1.18.33), same sampling enforced by my proxy, one run per task, seed 1. Seven tasks run 45 minutes, tasks 2, 4 and 8 run 150. Every counted app below is clickable. Not a duel: cells differ in engine, checkpoint, context window and hardware.
9 / 9cells released
4memory classes
0cloud
How to read this page
What Tier 1, 2 and 3 mean
Every app is checked by a script that opens it and clicks through it. The checks come in three groups: must-pass (does it start and do the basics), quality (does it work properly) and top (the extra polish). The tier says how far the app got:
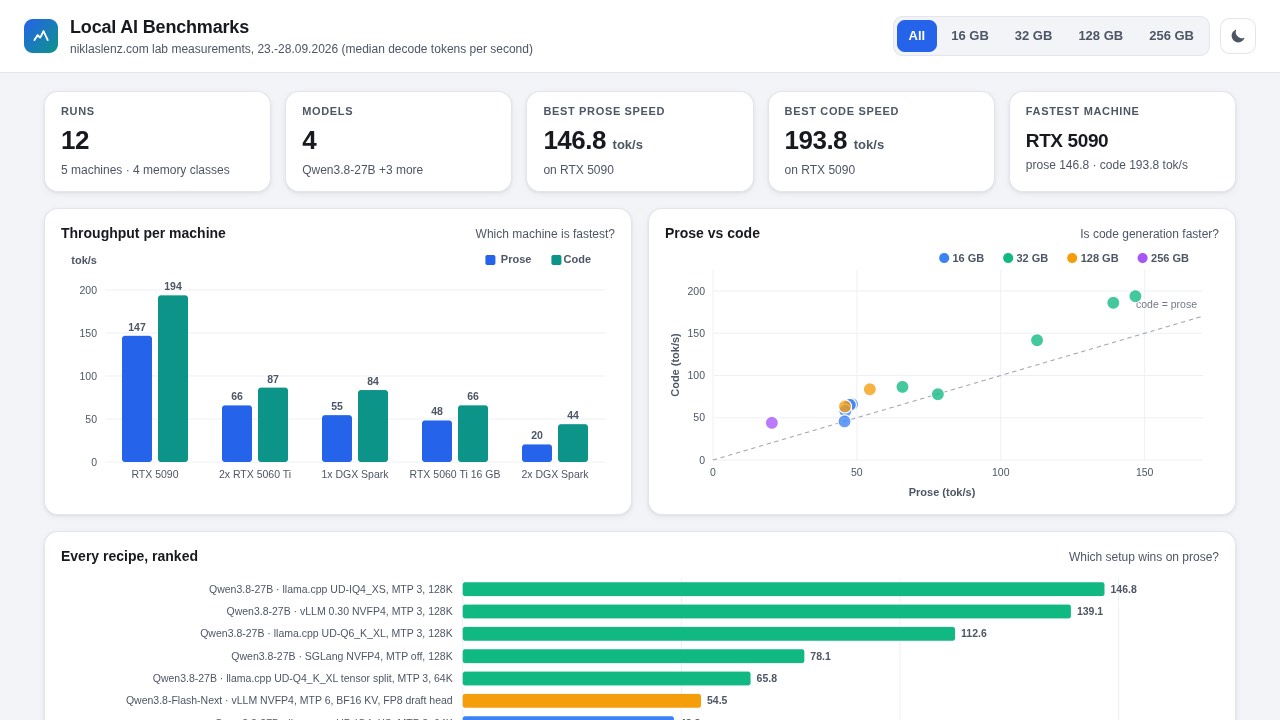
Tier 3 = all three groups passed. Tier 2 = must-pass and quality passed, not all top checks passed. Tier 1 = only must-pass passed: the app runs, but some quality checks failed. No counted commit = the app never passed the must-pass checks.
The text under each badge, for example "quality 8 of 9", shows how many quality checks passed. The tier belongs to the last commit before the time limit that passes must-pass. It is not a speed rating and not a ranking between setups. One run per task: a Tier 1 next to a Tier 3 can be one unlucky run.
Round 2 · 16 GB class
16 GB · One RTX 5060 Ti box, both cells
Round 2, 16 GB. Same RTX 5060 Ti, same 10 app tasks, same prompts, time limits, agent (opencode 1.18.33) and sampling. Same base model on both sides, Qwen3.8-27B in different quants. @MiaAI_lab's kit first, then my own llama.cpp setup from round 1.
Tier 3quality 9 of 9 · counted commit at 37.5 min · first working 32 min
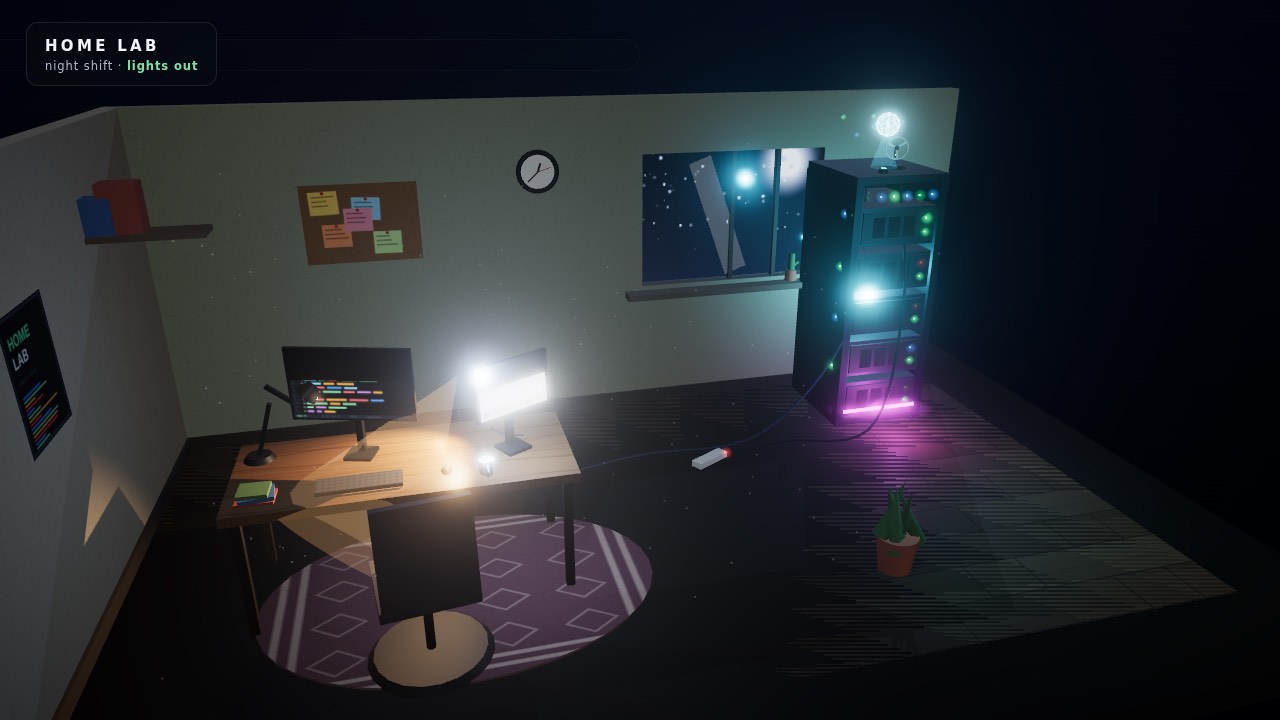
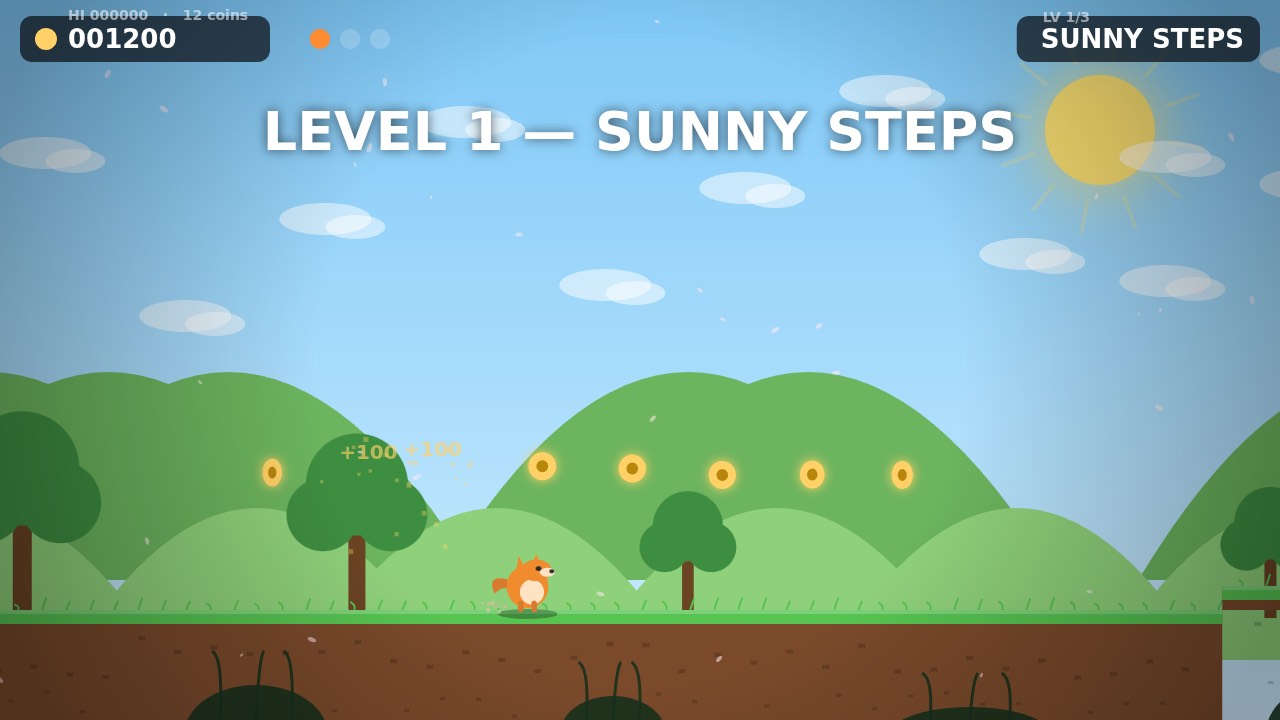
Footnote. s09 produced no passing commit on either side. At the 45-minute mark both sides were level on tier 3; the 6|8 gap comes from s02 swinging opposite ways. On her kit, s02 had a top-tier version at 16.9 min (9/9). My harness makes every model keep polishing until the end, and only the last passing commit counts. Its last change at 139.5 min, 'realistic' dark monitor screens, killed the night glow. Its own check showed the miss, and it committed anyway. Final: still runs, 8/9, tier 1. On her kit, s08 lost one more quality check after the 45-minute mark (separation, final 6 of 8), again the model's own edits, no sign of outside interference. On her kit, s10 ended at 8 of 9 (keyboard undo), tier 1, from my runner's hard-stop commit. On her kit, s07 is a rescore of the same commit; the first scoring was killed by another agent's pkill on my shared test box. llama.cpp went the other way on s02 (tier 1 at the 45-minute mark, counted tier 3) and missed tier 3 on s08 by a hair: separation 1.29 against the 1.3 bar, first working version only at 88.5 min. One run per task, seed 1.
Fine print.
temperature 0.6 enforced by my proxy for both. Mia's one-click kit is at 622c796: EXL3 2.5 bpw on exllamav3 1.4.4 (1.5.3 is out), 176,128-token window, KV 4 bit, MTP draft, images on. 2.5 bpw is the kit's default for 16 GB (176K with images); the kit also lists 2.0 bpw, 3.0 bpw and 3.5 bpw profiles at other context sizes. It ran with --no-harness, its own harness off. My llama.cpp b11151 (b11349 is out): UD-Q3_K_XL, a 13.1 GB file, about 3.8 bpw, 98,304-token window, KV q4_0, MTP draft, no vision. Engines ran on the 16 GB box's GPU 1, the harness on System A. Both cells shared my test box with other agents; three runs on her kit got brief pkill hits in the agent phase (no counted result changed), and llama.cpp, which ran later, got none.
Mia's EXL3 kit | llama.cpp UD-Q3_K_XL
Tasks with a counted commit: 9 | 9 of 10
Tasks at tier 3 (top): 6 | 8
Quality checks passed: 78 of 82 | 81 of 82
Output tokens in total: 1,587,451 | 1,242,419
Definitions. Counted commit = the last commit at the hard stop that passes all must-pass checks (the runner also commits leftover work at the stop; only a commit that passes counts). Tier 3 = must-pass, quality and top checks all pass. Tasks s02, s04 and s08 ran up to 150 minutes, the other seven up to 45.
Round 2 · 32 GB class
32 GB · One RTX 5090, both cells
Round 2, 32 GB. Same RTX 5090, same 10 app tasks, same prompts, time limits, agent and sampling. Same base model on both sides, Qwen3.8-27B in different quants. @MiaAI_lab's recipe first, then @ashxhart's engine.
Mia's NVFP4 recipe
TensorFold 0.6.0
Tasks with a counted commit
9 of 10
10 of 10
Tasks at tier 3 (top)
9 of 9
10
Time to first token, median of 10 task medians
20.2 s
0.99 s
Output tokens in total
1,074,247
5,236,055
Mia's NVFP4 recipe · Qwen3.8-27B on RTX 5090, 32 GB
RadixArk NVFP4 · vLLM 0.27.1 + her backport of vLLM PR 40914 (vLLM 0.30.0 is out, PR not merged) · 262K · MTP 3 drafting · one sequence at a time · prefix caching off by design · recipe at a5f9bff
Tier 3quality 9 of 9 · counted commit at 33.3 min · first working 8 min
Footnote. NVFP4's s10 never produced a passing commit; at the hard stop 10 of the 14 must-pass checks had passed when my checker's 8-minute cap stopped it during the crop check (the rest never ran). Its s05 is a rerun after the engine was unreachable for two minutes (cause not found). TensorFold's s08 had two checks each retried once after two cleanup commands from one other run killed its test server; the retried checks count. My automatic re-check for test-box errors came in after the NVFP4 runs were scored; it would not have retried s10's timeout. Foreign cleanup commands from other runs on my shared test box hit NVFP4's s04, s07 and s10 during the agent phase (s04 and s10 more than once); s07 may have lost its 15-minute mark to one of them, and s10's scoring check may have been hit too, likely without effect. No TensorFold 0.6.0 run was hit during the agent phase. One run per task, seed 1.
Fine print.
temperature 0.6 enforced by my proxy for both. Mia's recipe is at a5f9bff: RadixArk NVFP4 on vLLM 0.27.1 with her backport of vLLM PR 40914 (vLLM 0.30.0 is out; PR 40914 is not merged yet), 262K window, MTP 3 drafting, one sequence at a time, prefix caching off by design so every request is cold. TensorFold 0.6.0 at c464617 (0.6.3 is out): Vontra MLX 4bit plus a DFlash2 drafter, 156K window picked by TensorFold, requests mostly warm; without a cache hit its first token still took a median of 30.0 s (median of the ten task medians). That cache difference is why the first-token line sits where it does. TensorFold wrote 4.9 times the output tokens under the same time limits. More speed is not more quality.
Mia's NVFP4 recipe | TensorFold 0.6.0
Tasks with a counted commit: 9 | 10 of 10
Tasks at tier 3 (top): 9 | 10 of 10
Time to first token, median of 10 task medians: 20.2 s | 0.99 s
Output tokens in total: 1074247 | 5236055
Definitions. Counted commit = the last commit at the hard stop that passes all must-pass checks (the runner also commits leftover work at the stop; only a commit that passes counts). Tier 3 = must-pass, quality and top checks all pass. Tasks s02, s04 and s08 ran up to 150 minutes, the other seven up to 45.
Round 2 · 128 GB class
128 GB · One GB10 box per cell
@MiaAI_lab ships two single-box recipes for Qwen3.8-Flash-Next. In my Round 2 each ran on its own GB10 box and got the same 10 app tasks, with the same prompts, time limits, coding agent and sampling.
Mia's TensorFold recipe
Mia's vLLM kit
Tasks with a counted commit
10 of 10
10 of 10
Tasks at tier 3 (top)
10
10
Quality checks passed
91 of 91
91 of 91
Mia's TensorFold recipe · Qwen3.8-Flash-Next on Gigabyte AI TOP ATOM (GB10), 128 GB
MLX 4bit · TensorFold 0.3.6.3 from her image (0.6.3 is out) · PARALLEL=4 (her default 5 did not fit my free memory) · 262K · recipe at a3aa898 (newer commits exist)
Tier 3quality 9 of 9 · counted commit at 35.8 min · first working 13.6 min
Footnote. my first scoring had TensorFold s03 and vLLM s03, s05, s07 at tier 0. On my shared test machine another run's cleanup command killed the test server or browser mid-check. Same commits, same checker, scored again: tier 3. The same flaw hit TensorFold s02 and vLLM s02, s05, s09 while the agents worked.
Fine print.
one run per task, seed 1, temperature 0.6 set by my proxy for both. TensorFold recipe at a3aa898 (newer commits exist) with PARALLEL=4 (her default 5 did not fit my free memory), MLX 4bit, TensorFold 0.3.6.3 from her image (0.6.3 is out). vLLM kit at 7d0712d on its default .env, NVFP4. Both with a 262K window.
Definitions. Counted commit = the last commit at the hard stop that passes all must-pass checks (the runner also commits leftover work at the stop; only a commit that passes counts). Tier 3 = must-pass, quality and top checks all pass. Tasks s02, s04 and s08 ran up to 150 minutes, the other seven up to 45.
Round 2 · 256 GB class
256 GB · Two GB10 pairs
Round 2, 256 GB. What GLM-5.3-Flash builds on two pairs of GB10 boxes (the ASUS Ascent GX10 pair, the Gigabyte AI TOP ATOM + Lenovo ThinkStation PGX pair): the same 10 app tasks, one counted run per task, seed 1. I show @MiaAI_lab's kits first (vLLM and TensorFold), then @ashxhart's TensorFold recipe. Not a duel: the three cells used different engines, checkpoints and context windows; two of them shared the same pair.
Mia's vLLM kit
Mia's TensorFold kit
Ash's TensorFold recipe
Tasks with a counted commit
10 of 10
10 of 10
8 of 10
Tasks at tier 3 (top)
9
9
6 of 8
Quality + top checks passed
90 of 91
90 of 91
71 of 73
Mia's vLLM kit · GLM-5.3-Flash on ASUS Ascent GX10 pair (GB10), 2×128 GB
TensorFold 0.6.0 (0.6.3 is out) · MLX 4bit · tp 2 · 64K window (my pick; the recipe default of 2051 was too small for the agent tasks) · recipe at c464617 (newer commits exist)
Tier 2quality 8 of 9 · counted commit at 44.3 min · first working 44.3 min
no counted commit
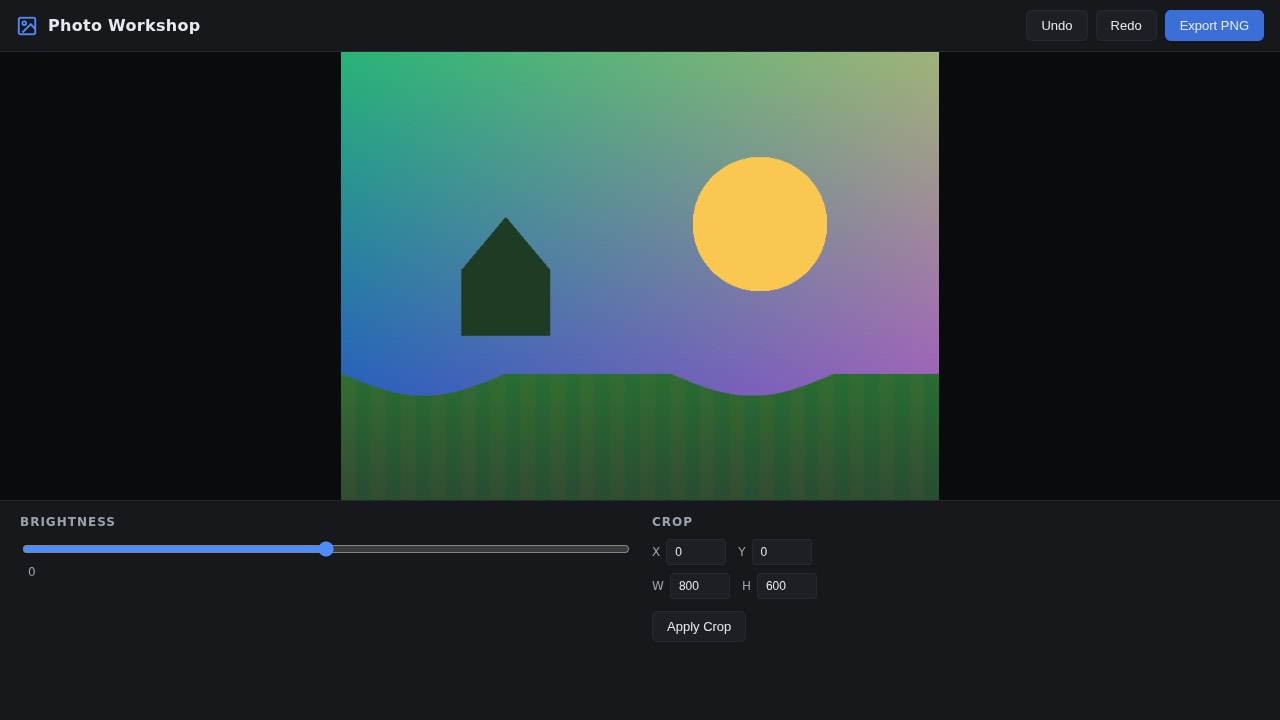
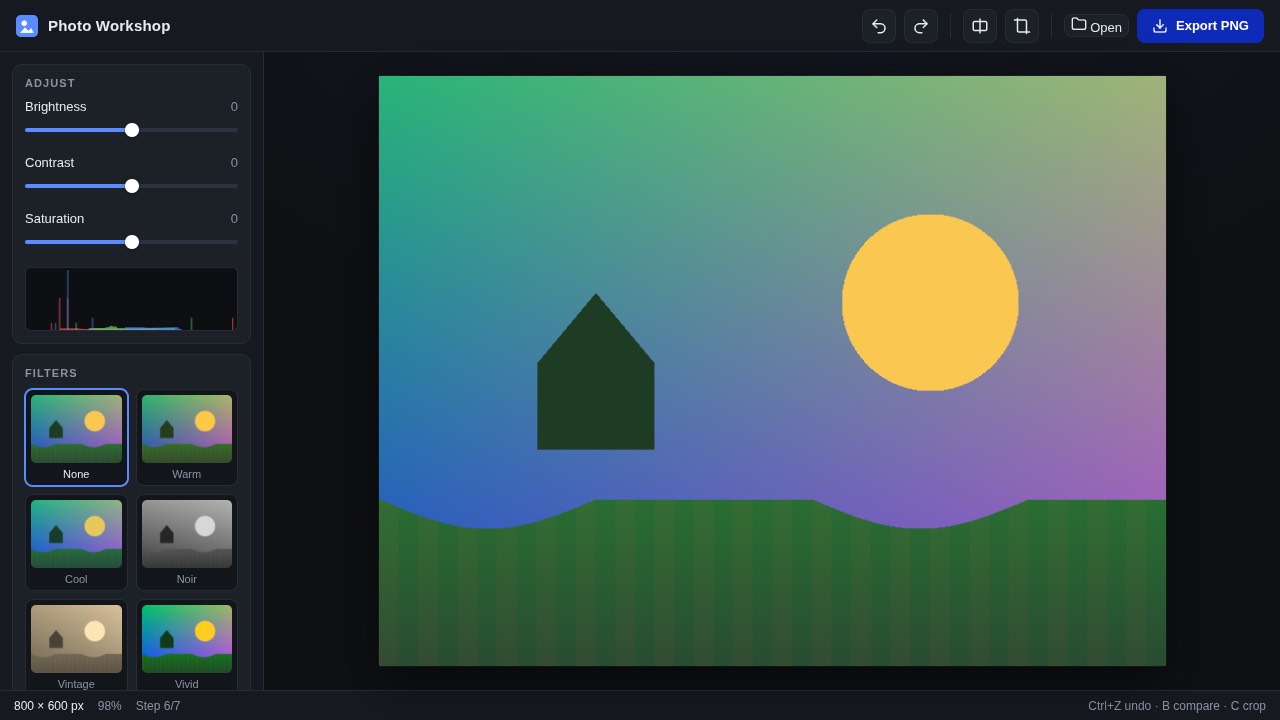
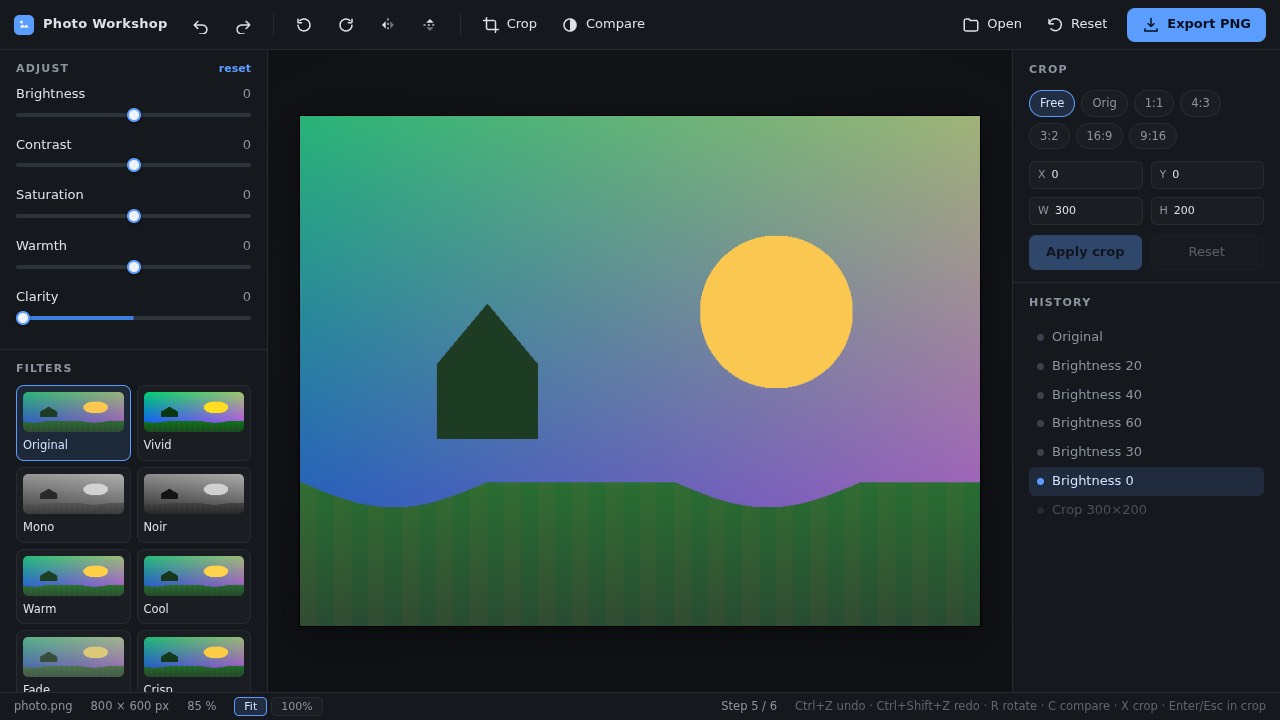
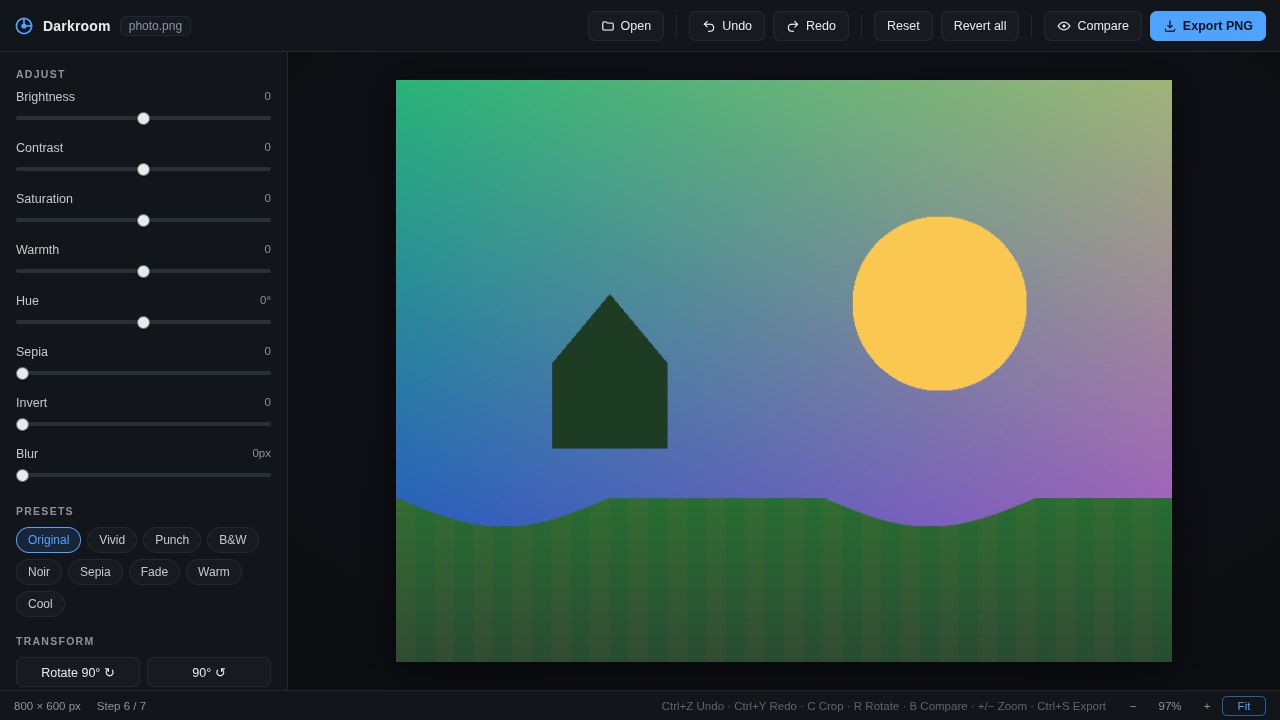
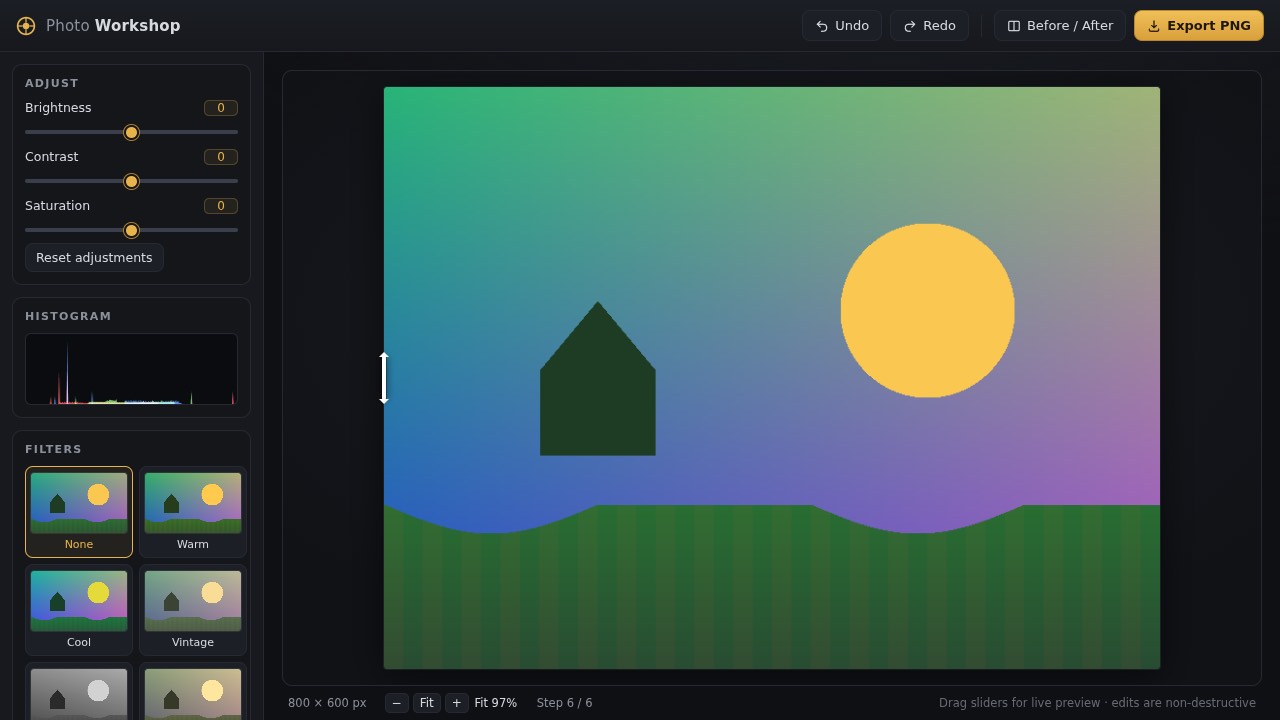
10 · Photo editor
A photo editor in the browser
No counted commit
No commit passed the must-pass checks
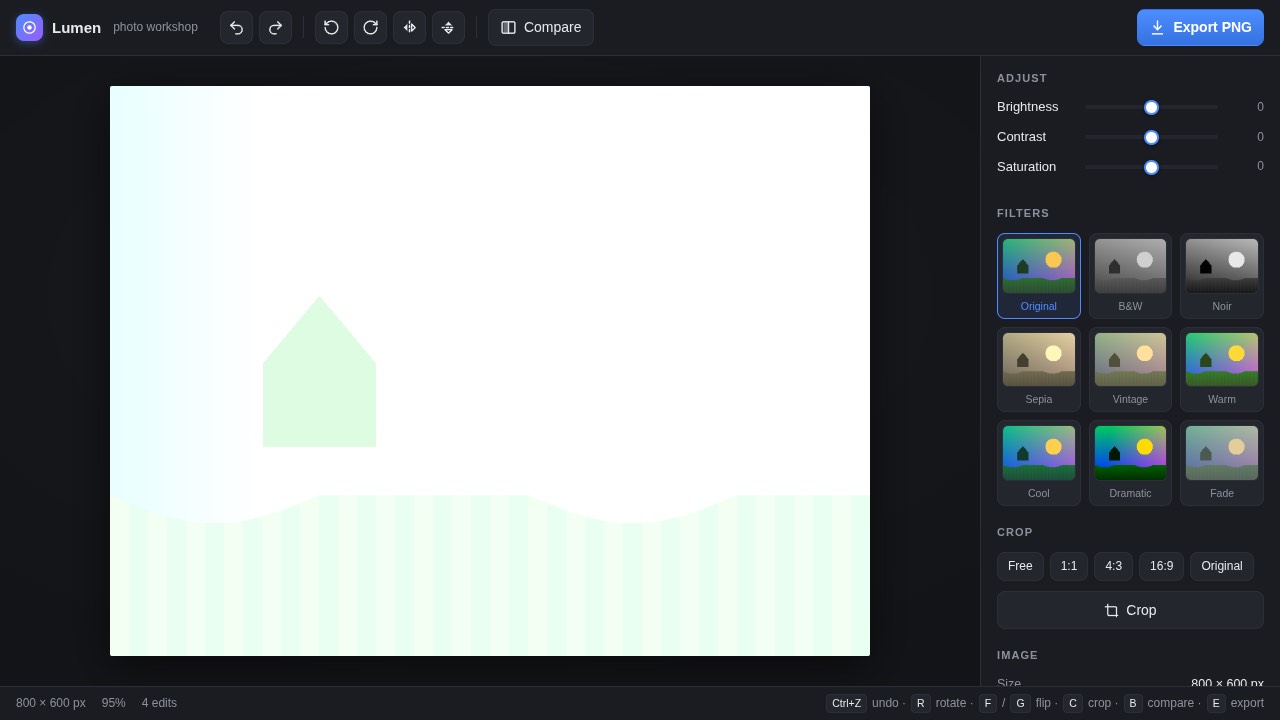
Footnote. Ash's s04 and s10 produced no passing commit (window.APP missing both times; whether my 64K window choice played a part is unchecked); s06 and s09 landed tier 2 (layout stable / 40 random invoices). For Mia's vLLM cell, the counted s04 and s02 runs are reruns: the earlier tries on 01.10. were cut off by my own setup, not model results (s04 three times, s02 once; one was my RAM guard, likely because of my own Jarvis jobs on that box, not proven); the reruns ran in the same engine session as the other eight tasks; s09 landed tier 2 (40 random invoices). Mia's TensorFold s08 is a real narrow regression: tier 3 at 44.2 min, counted tier 1 at 141.6 min, hawk 0.503 against the 0.50 bar. Ash's s02 had processes killed 8 times by my other test agents on the shared harness box (my setup: of the three cells only the Mia cell on the Gigabyte + Lenovo pair ran as its own user), the most of any run I checked (the ten vLLM runs of 02.10. are not part of that check), and still made tier 3.
Fine print.
temperature 0.6 enforced by my proxy for all three.
Mia's vLLM cell: her kit at 674155d (newer commits exist), vLLM, EXL3 4bpw, tp 2, 850K window, fp8 KV pool, DFlash2 drafts, vision on, 4 parallel, on the ASUS Ascent GX10 pair; the host side was mine: earlyoom off, oom_score_adj 800, the RAM guard armed under 2 GiB, my Jarvis timers on the first ASUS Ascent GX10 box paused from 02.10. 16:13 to cell end (3 of 10 runs started before), image rebuilt locally with one documented line change.
Mia's TF kit at 978b225 (v1.3; v1.5 is out, with a new default checkpoint): TensorFold 0.6.0 plus her 53 patches, EXL3 4bpw, tp 2, 1M window, fp8 KV, DFlash2 + copy drafts, vision on, 4 parallel, on the Gigabyte AI TOP ATOM + Lenovo ThinkStation PGX pair; my harness for this cell ran as its own user (r2iso34); the host side was mine here too: earlyoom off mid-cell, the RAM guard armed under 2 GiB. The Mia TF cell ran on the Gigabyte AI TOP ATOM + Lenovo ThinkStation PGX pair, the weaker pair: a prefill check at the time gave 72-74% of Mia's README prefill (the ASUS Ascent GX10 pair: 98-99%), under Mia's 2200 MHz cap. Cause: the Lenovo box's ConnectX-7 was stuck at ~13 Gb/s after a hot-plug on my side. I fixed it after all ten runs (re-test under the same cap: 100.4-101.7%); no run was repeated. The TF cell itself ran uncapped.
Ash's recipe at c464617 (newer commits exist) on TensorFold 0.6.0 (0.6.3 is out; Mia's TF cell runs 0.6.0 too): MLX 4bit, tp 2, 64K window (my pick; the recipe default of 2051 was too small for the agent tasks, its examples use larger ones), on the ASUS Ascent GX10 pair, run on 01.10. with the host as it was: earlyoom on, my Jarvis timers running.
GPU clock on the ASUS Ascent GX10 pair cells was not recorded.
Definitions. Counted commit = the last commit at the hard stop that passes all must-pass checks (the runner also commits leftover work at the stop; only a commit that passes counts). Tier 3 = must-pass, quality and top checks all pass. Tasks s02, s04 and s08 ran up to 150 minutes, the other seven up to 45.
Overview
Task × cell, Round 2
Cell: tier (0–3) and quality checks passed. One run per task, seed 1.
Mia TF 128 GB
Mia vLLM 128 GB
Mia EXL3 16 GB
llama.cpp 16 GB
Mia vLLM 256 GB
Mia TF 256 GB
Ash TF 256 GB
Mia NVFP4 32 GB
TF 0.6.0 32 GB
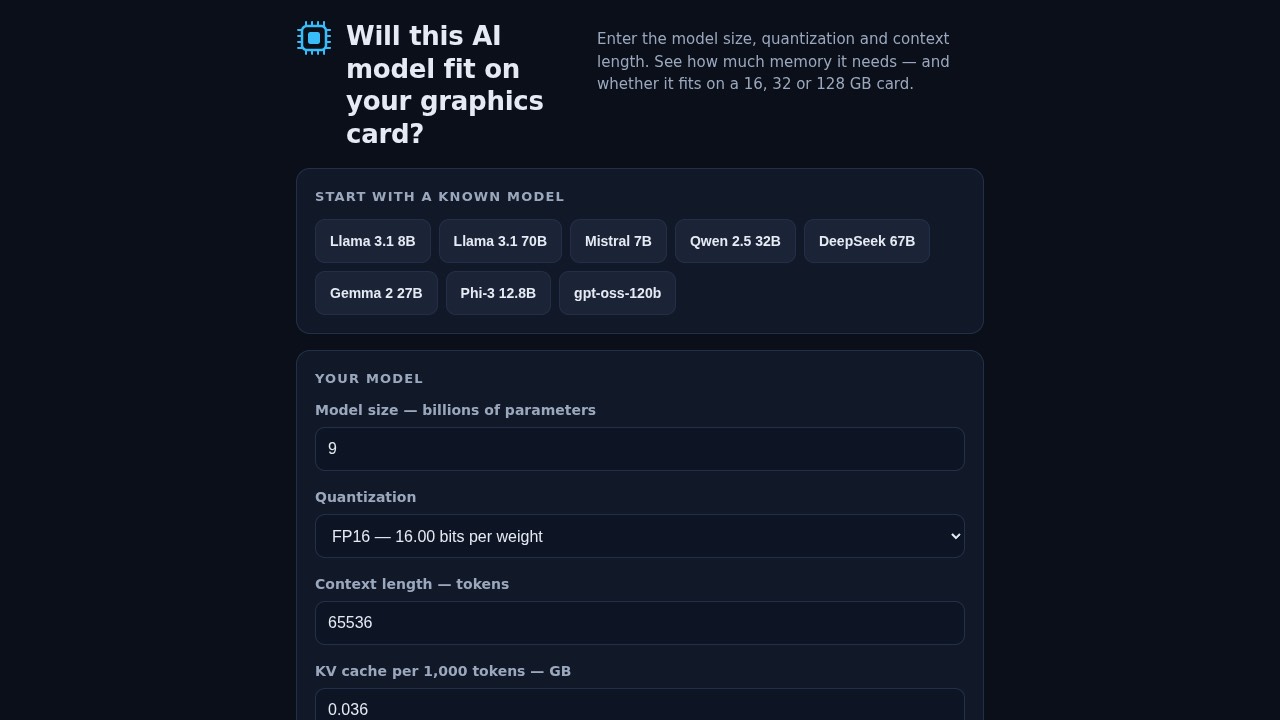
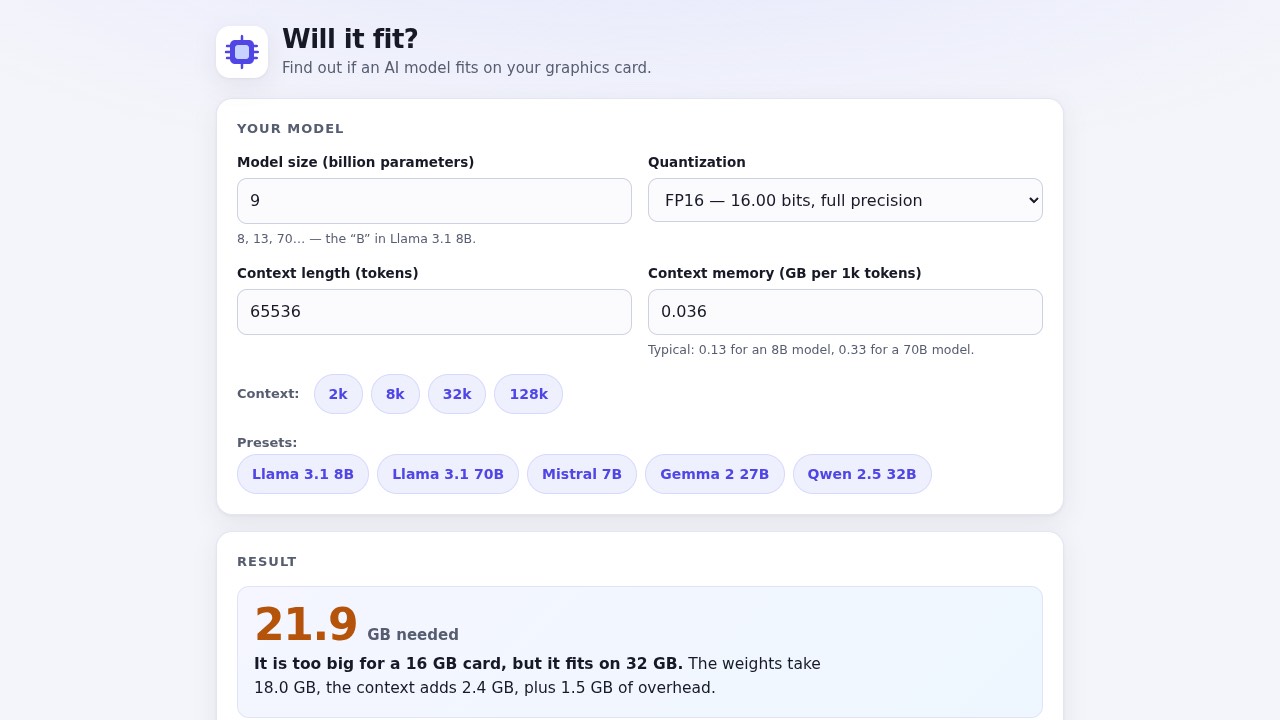
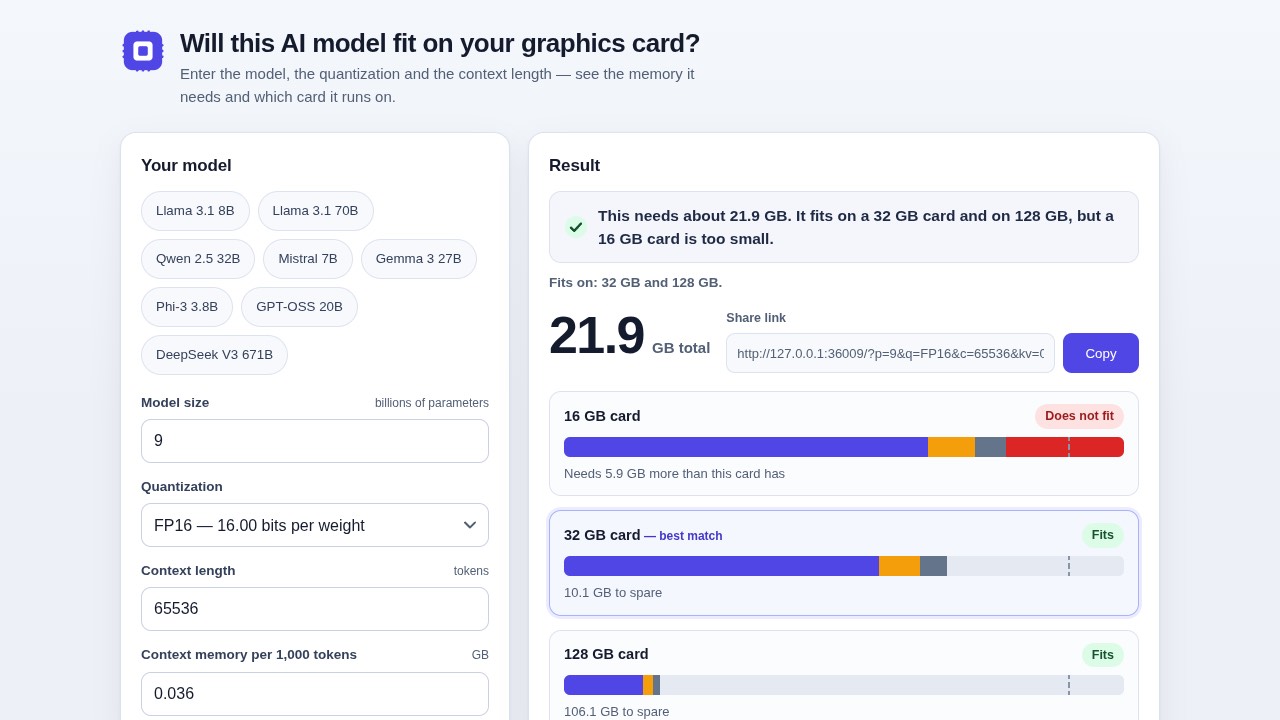
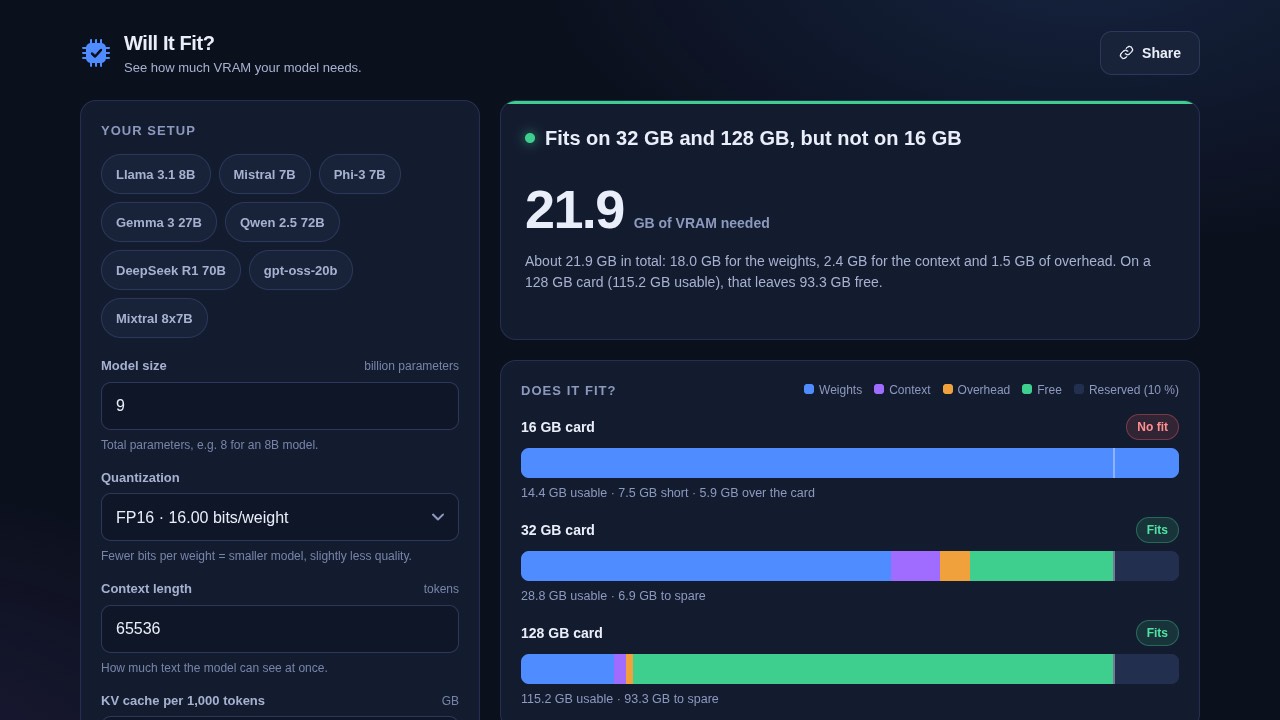
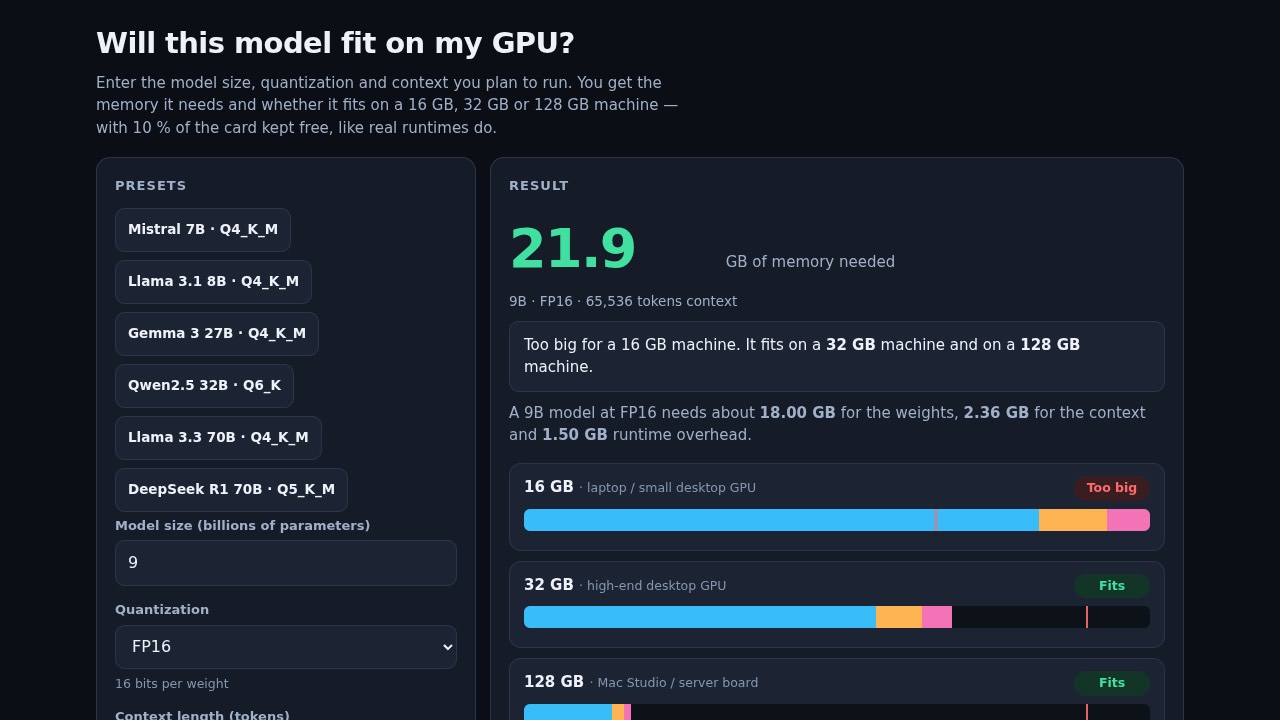
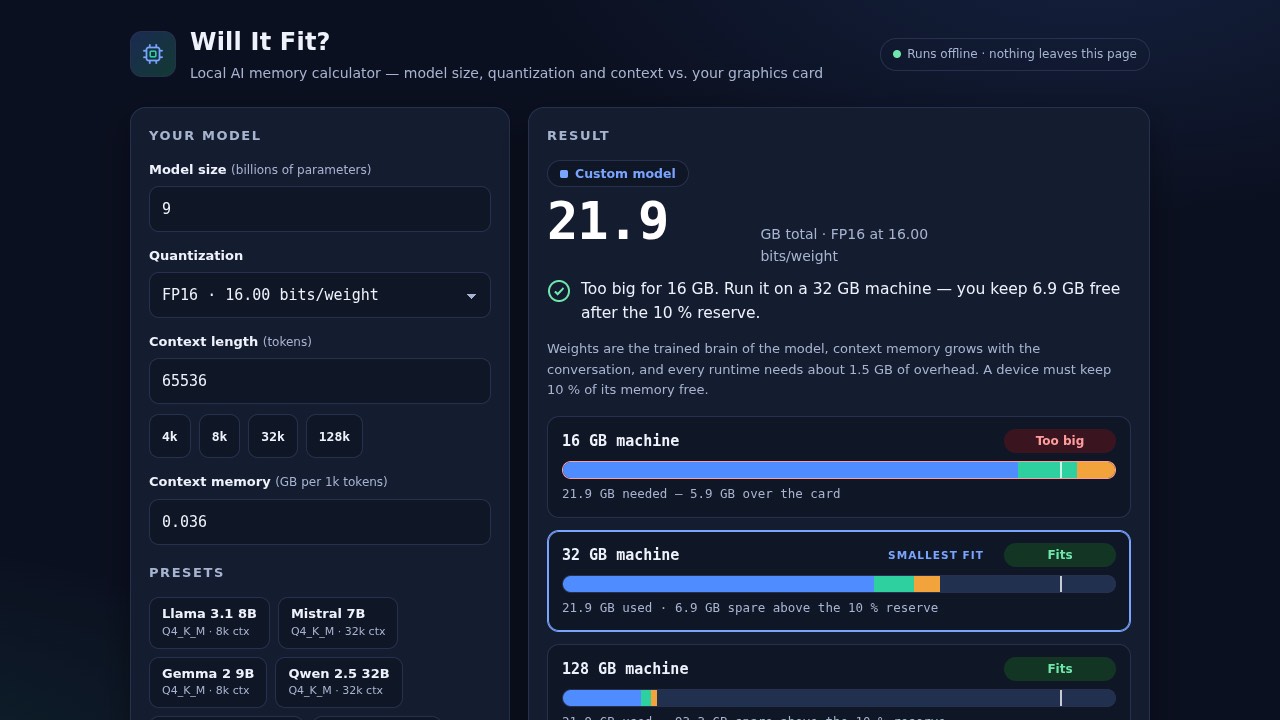
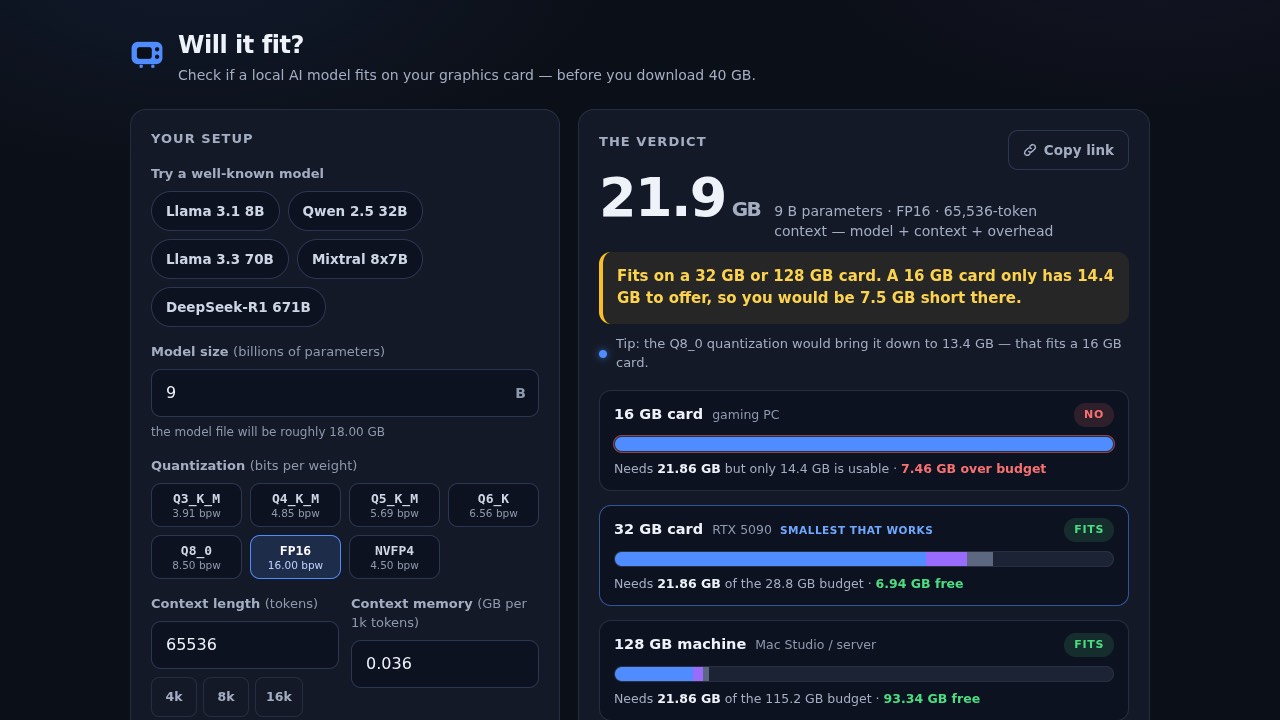
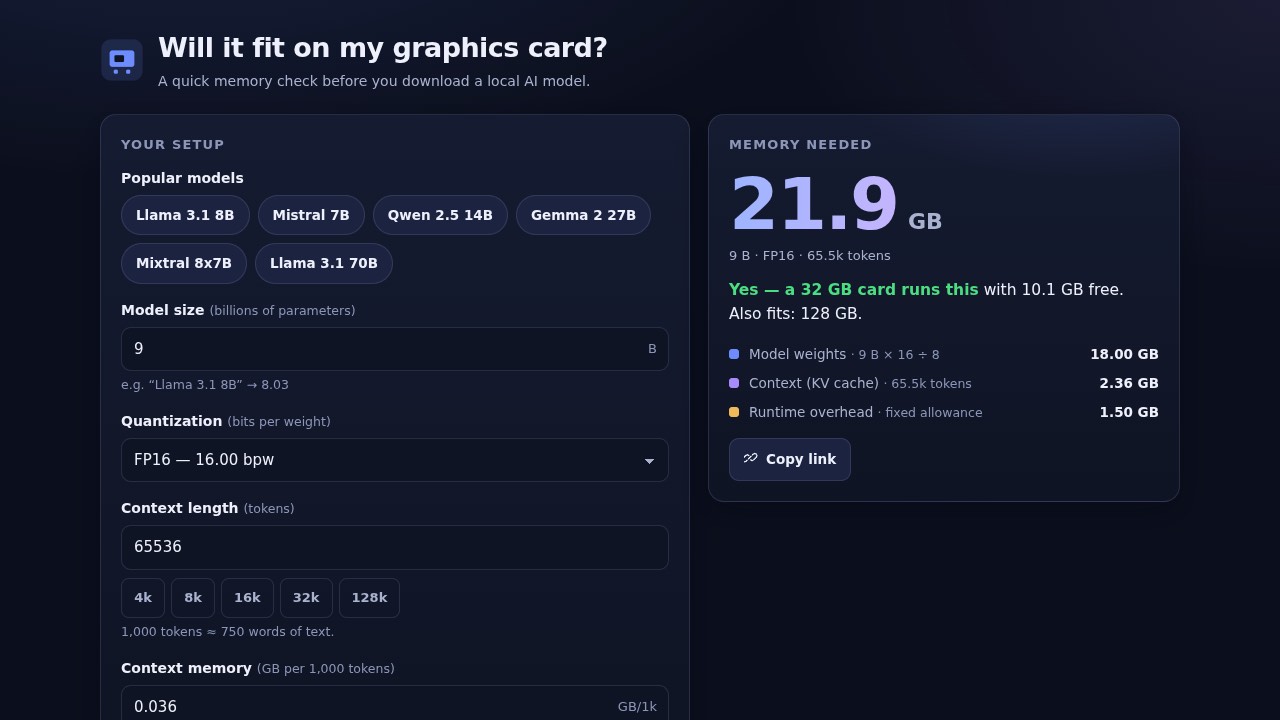
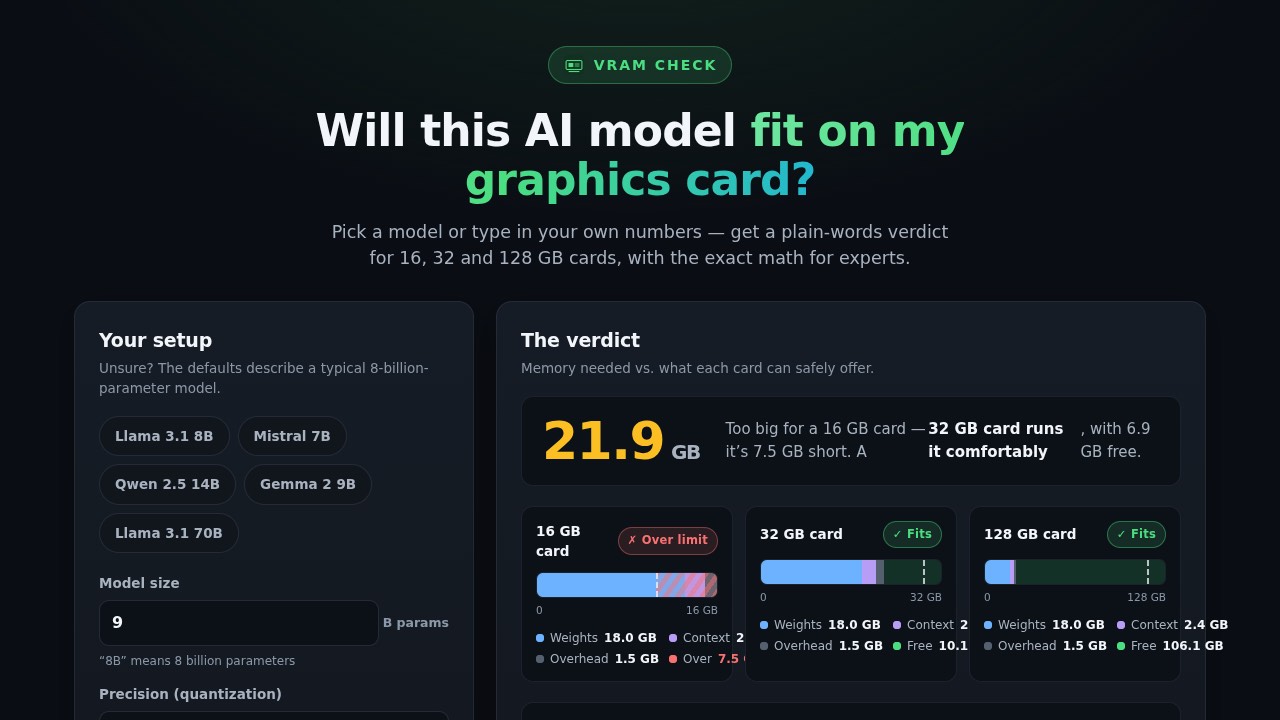
1 · Model fit calculator
39/9
39/9
39/9
39/9
39/9
39/9
39/9
39/9
39/9
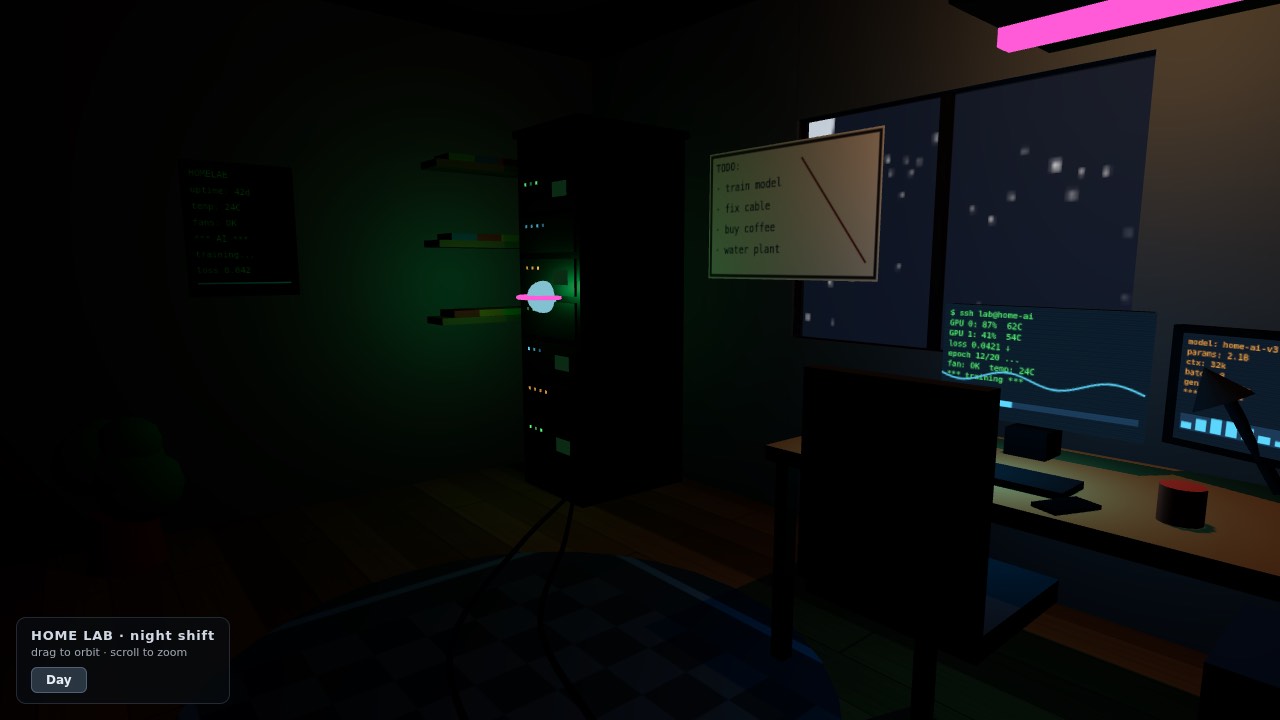
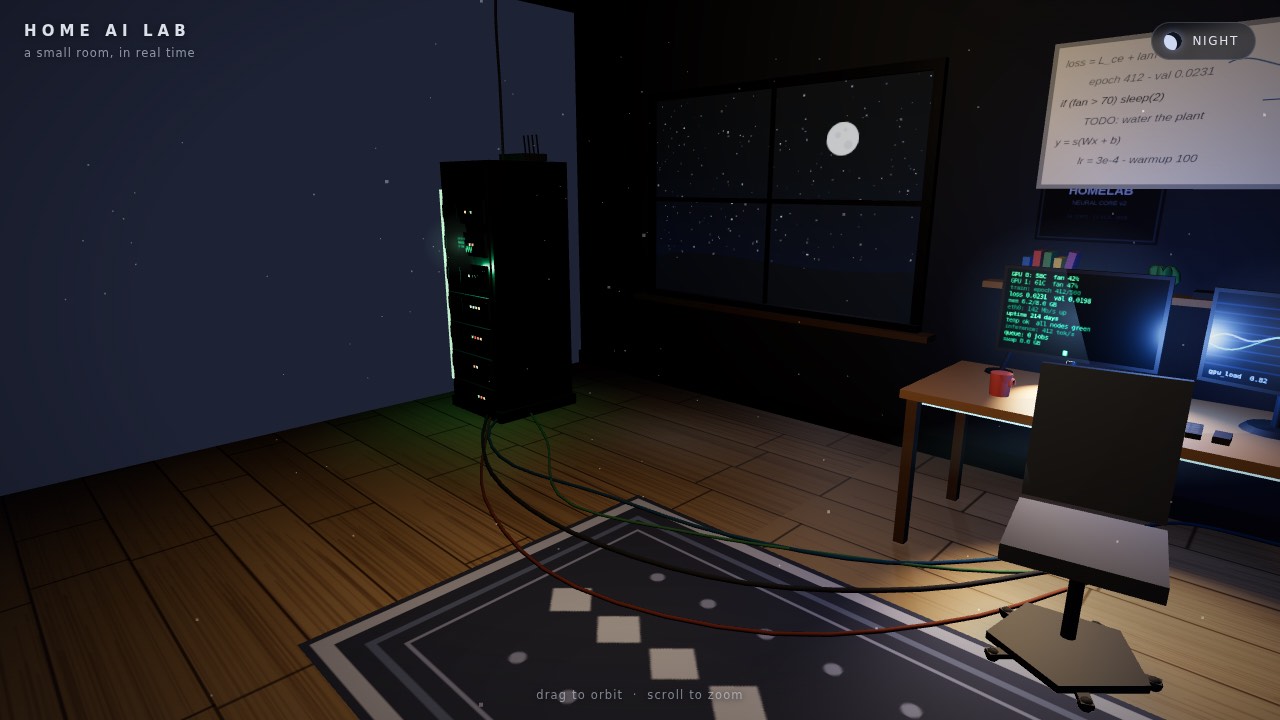
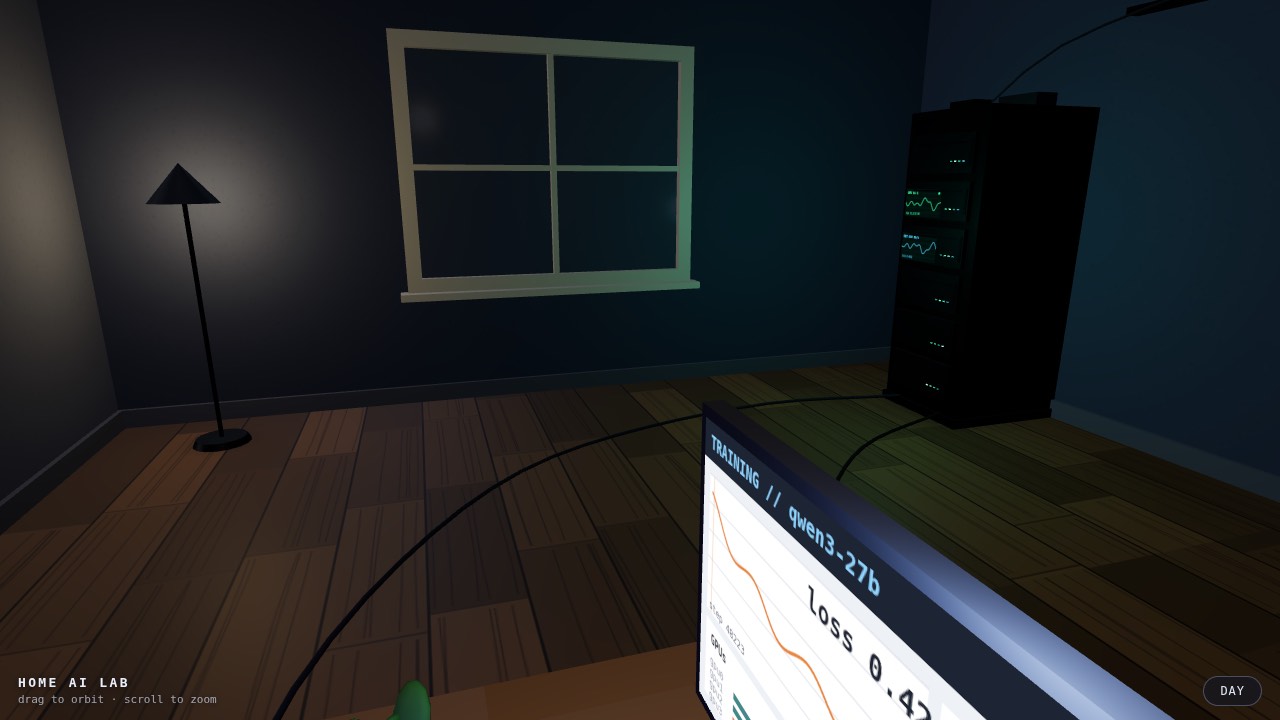
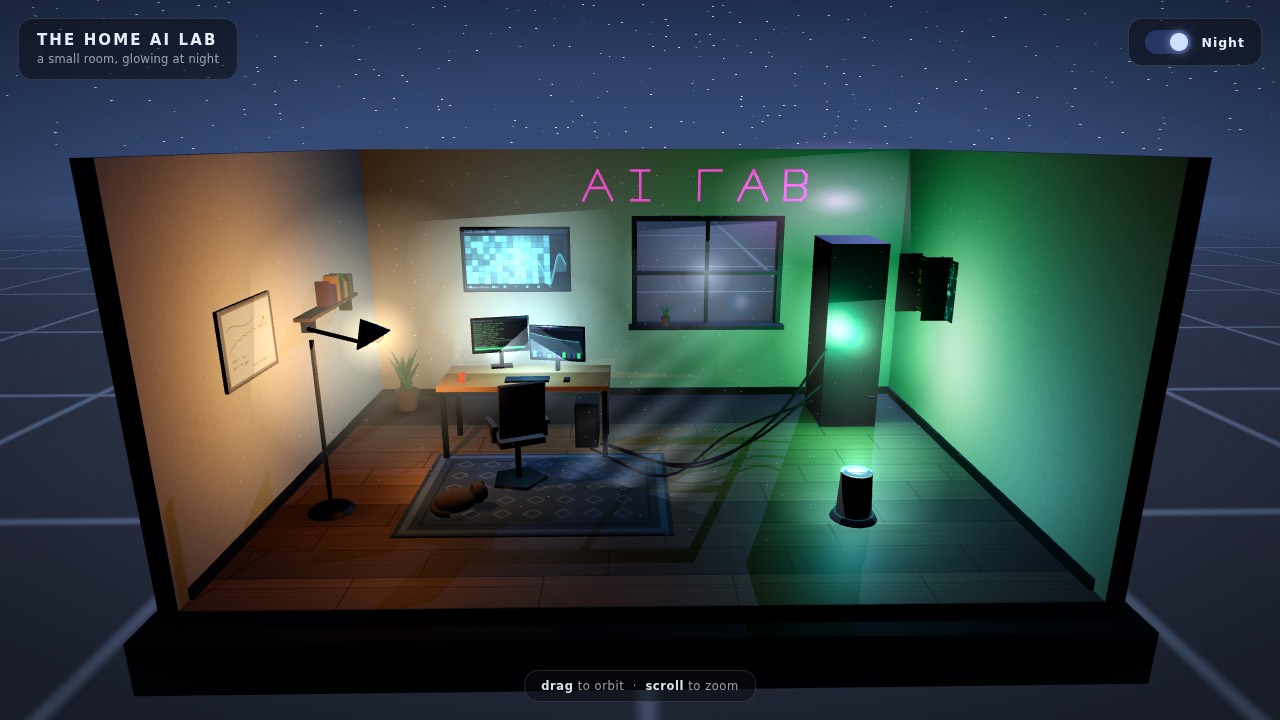
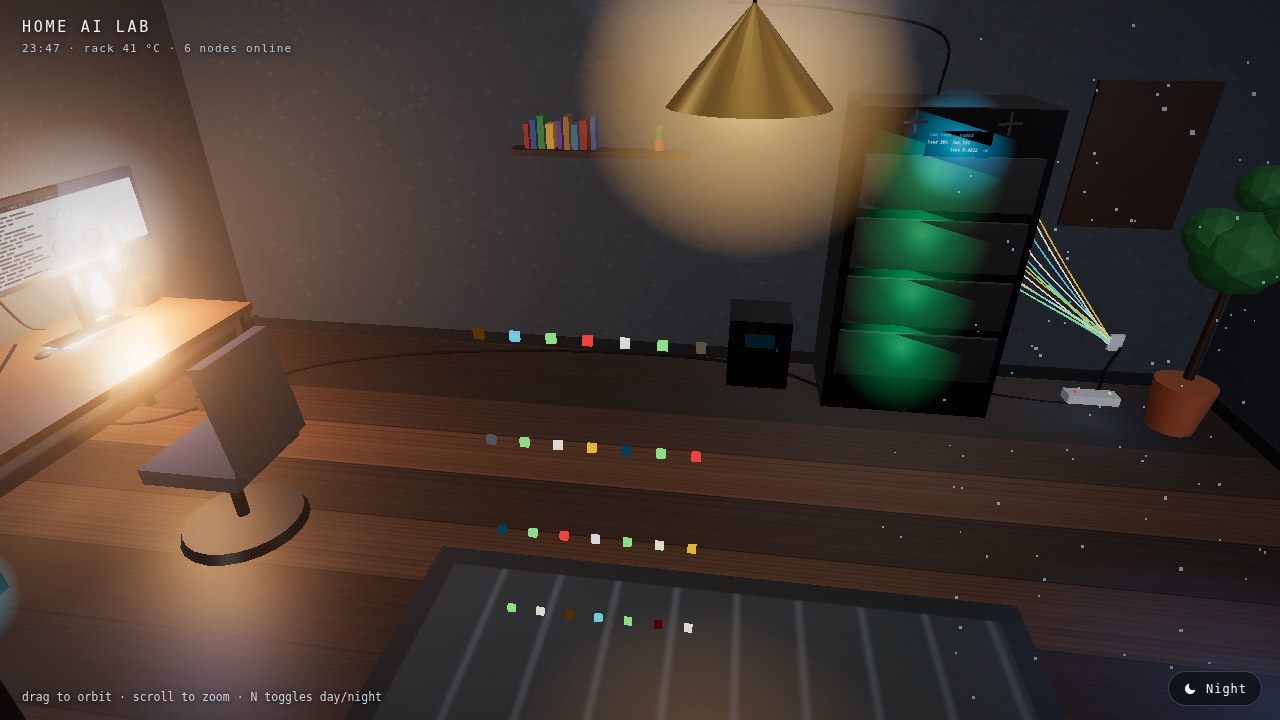
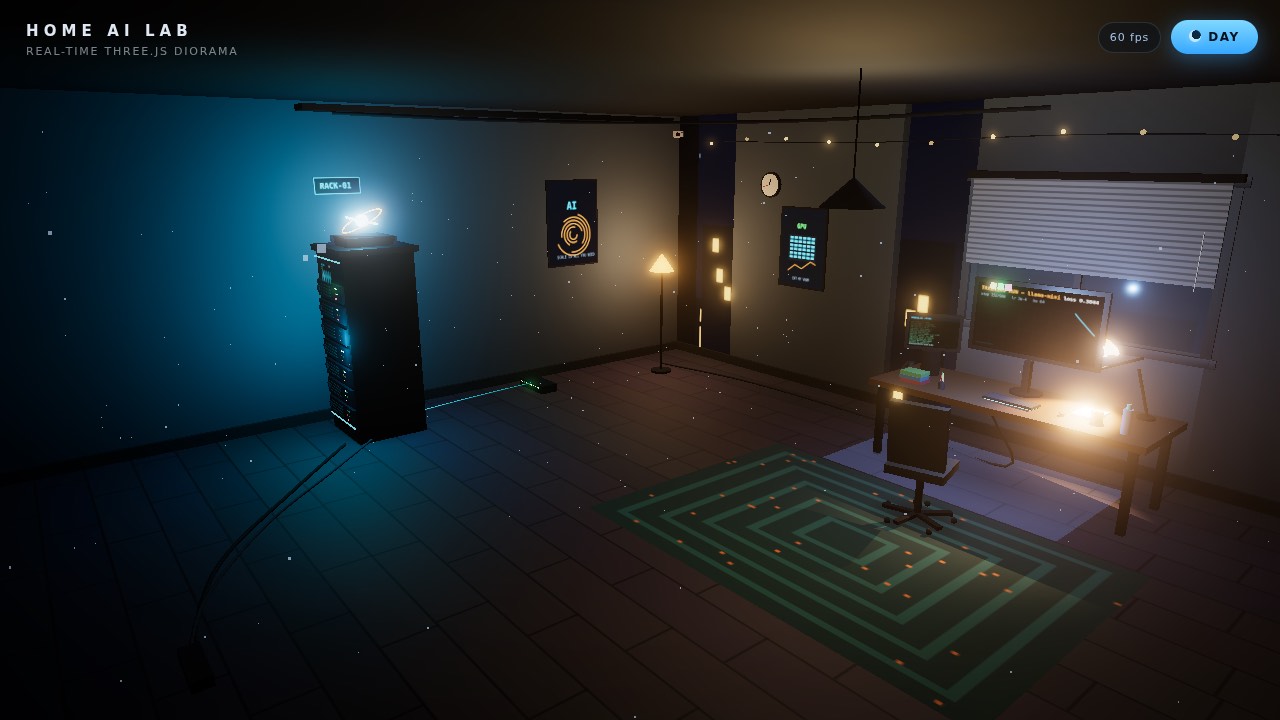
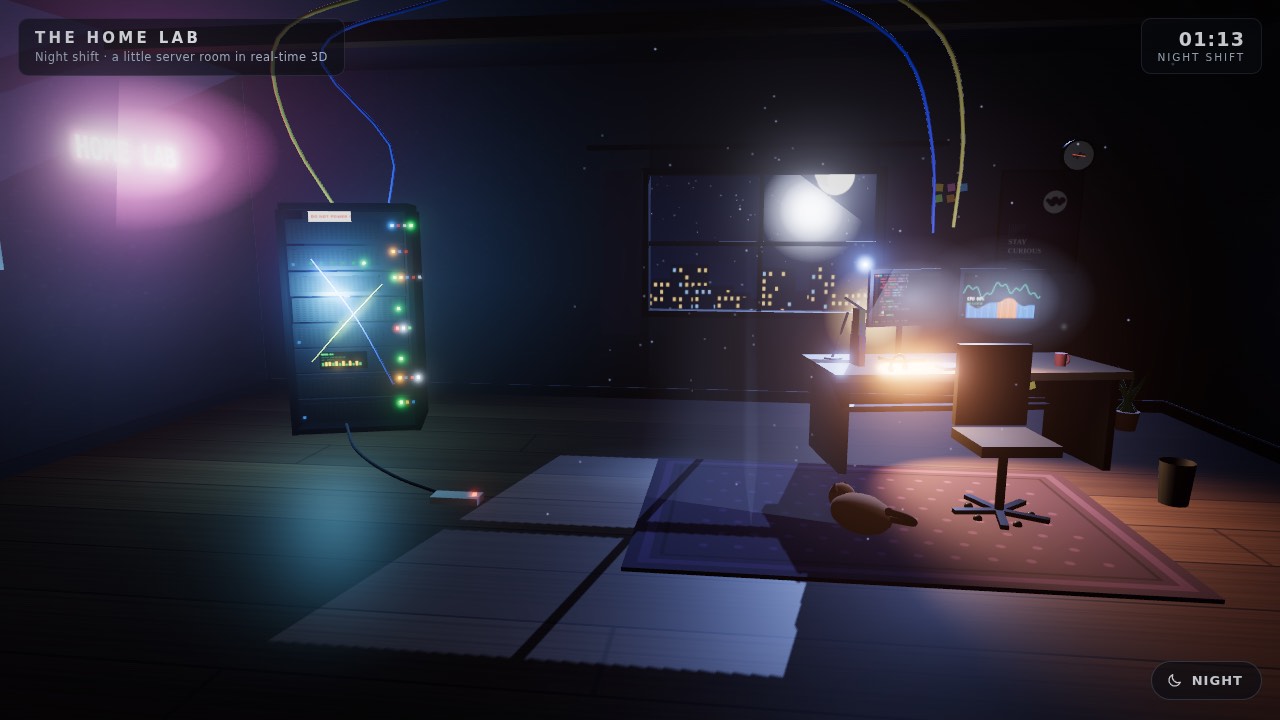
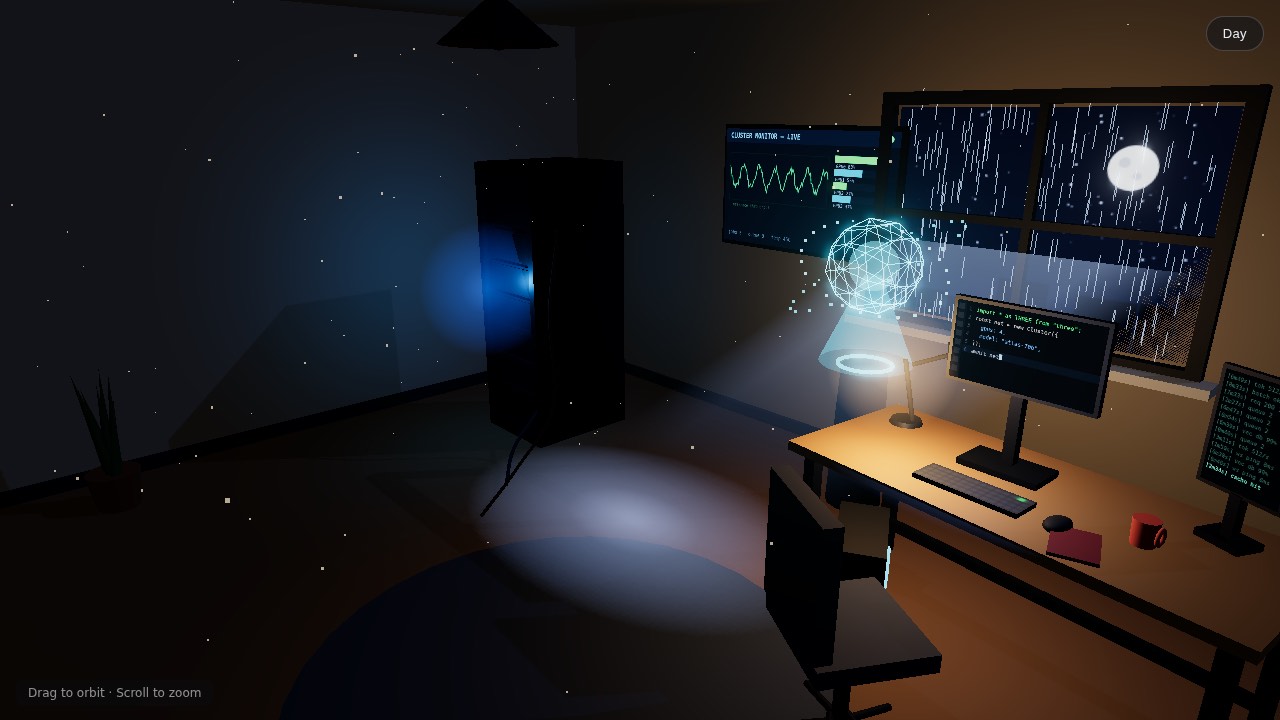
2 · 3D scene
39/9
39/9
18/9
39/9
39/9
39/9
39/9
39/9
39/9
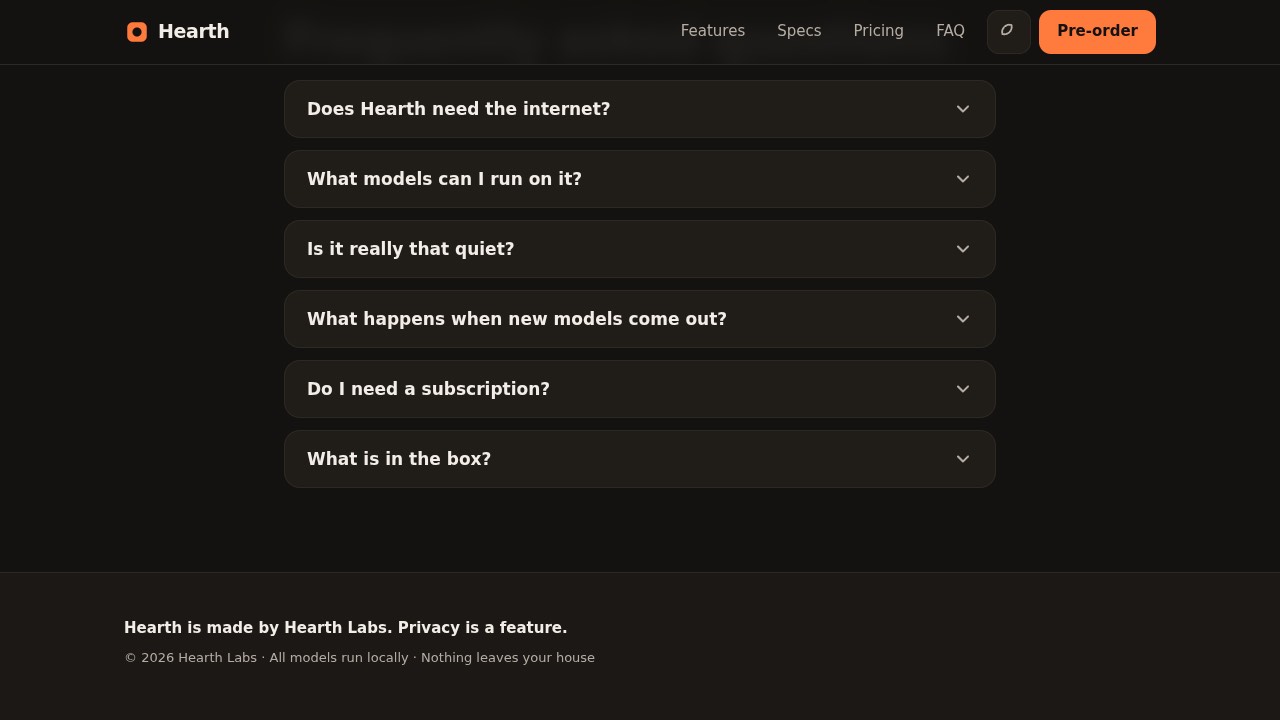
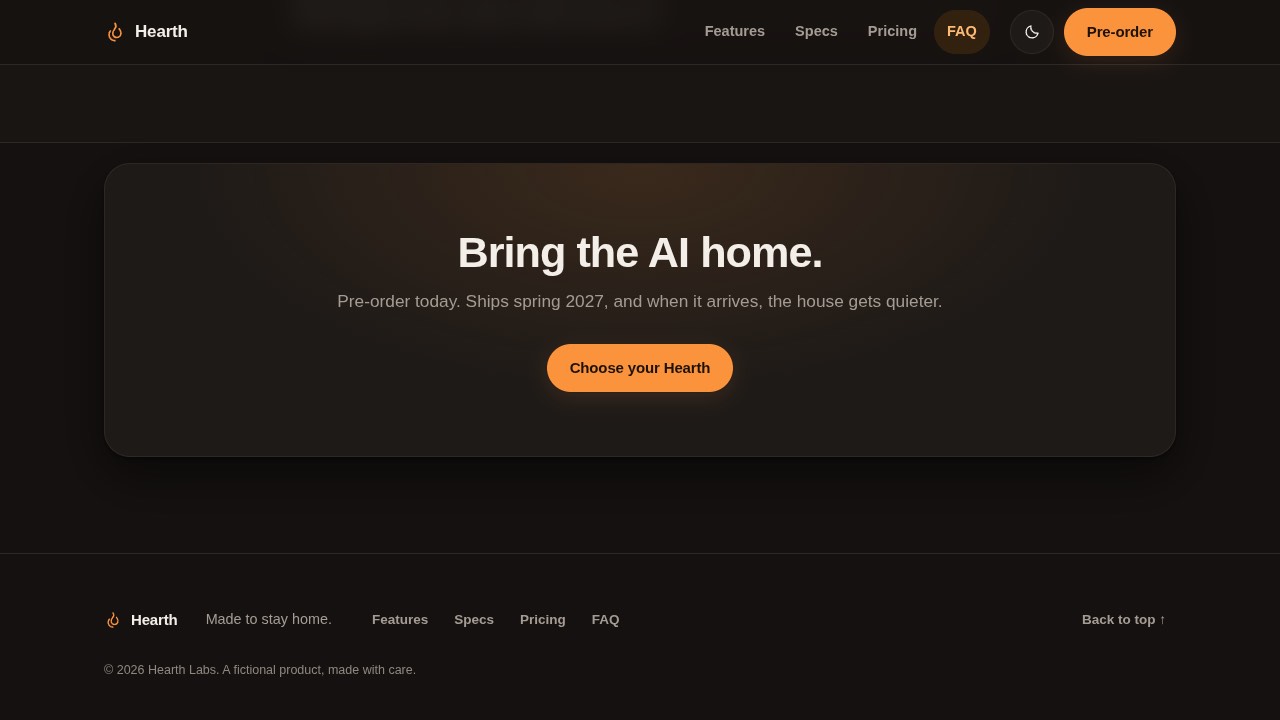
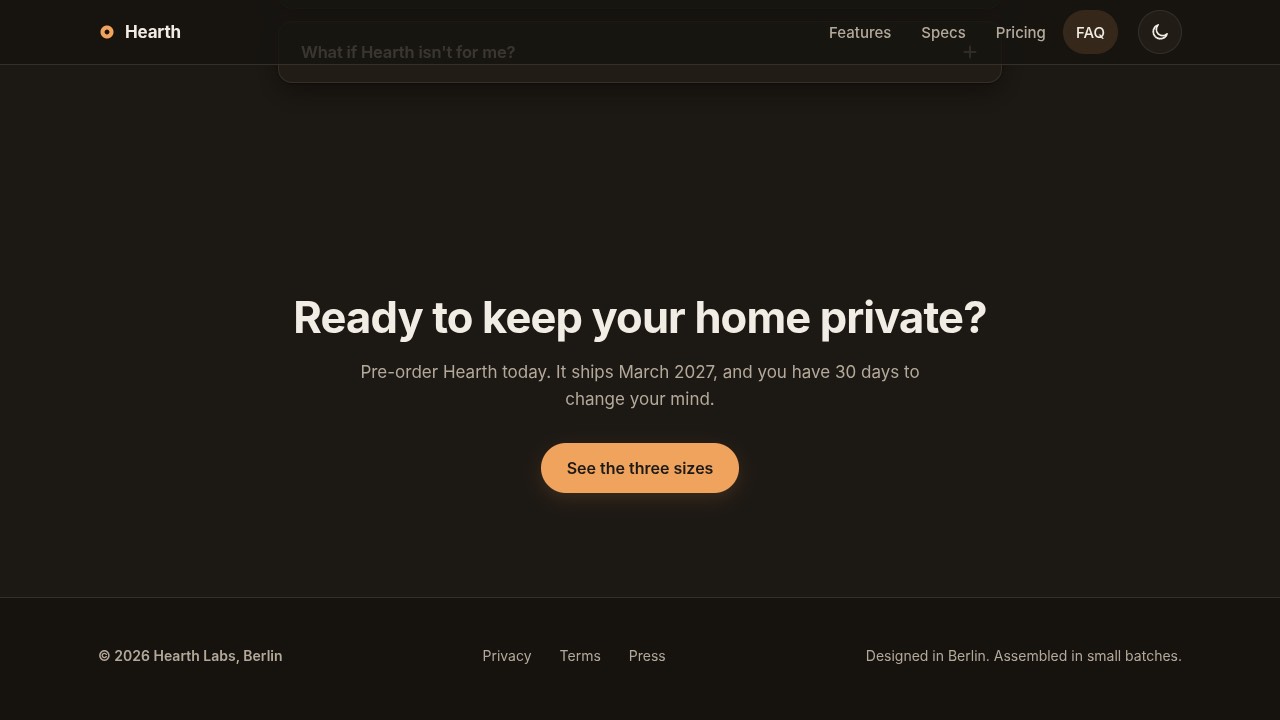
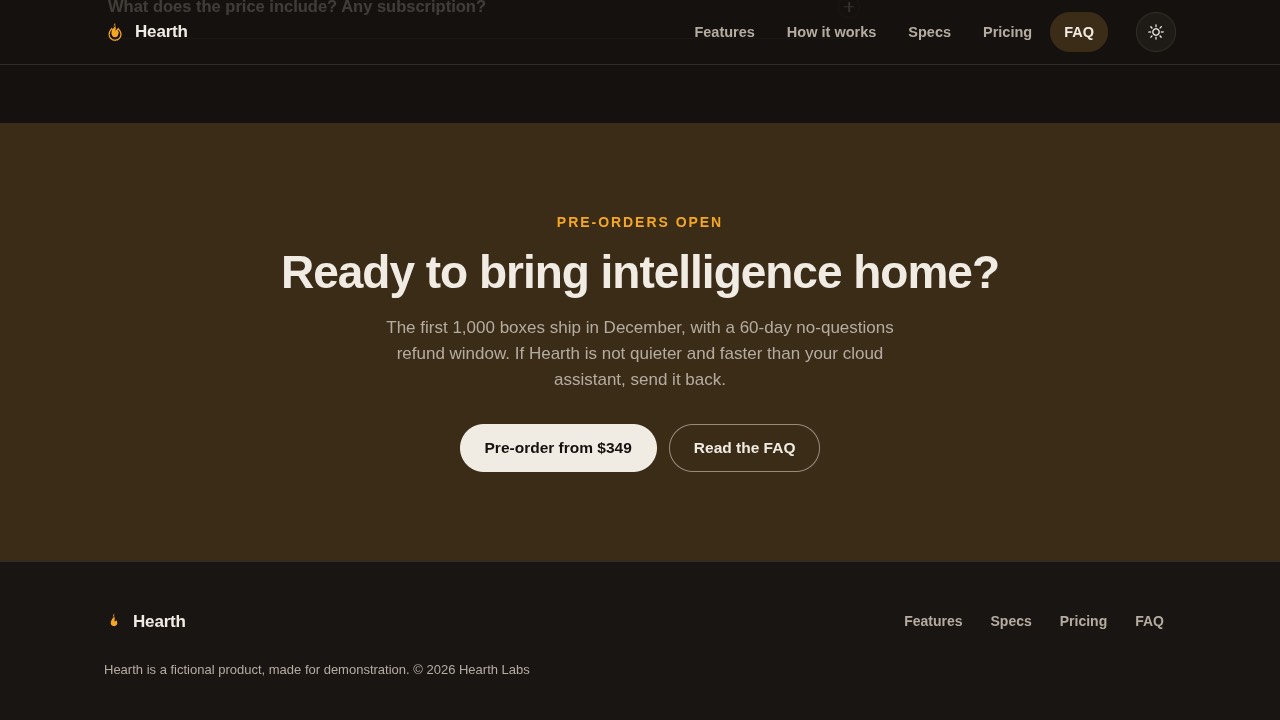
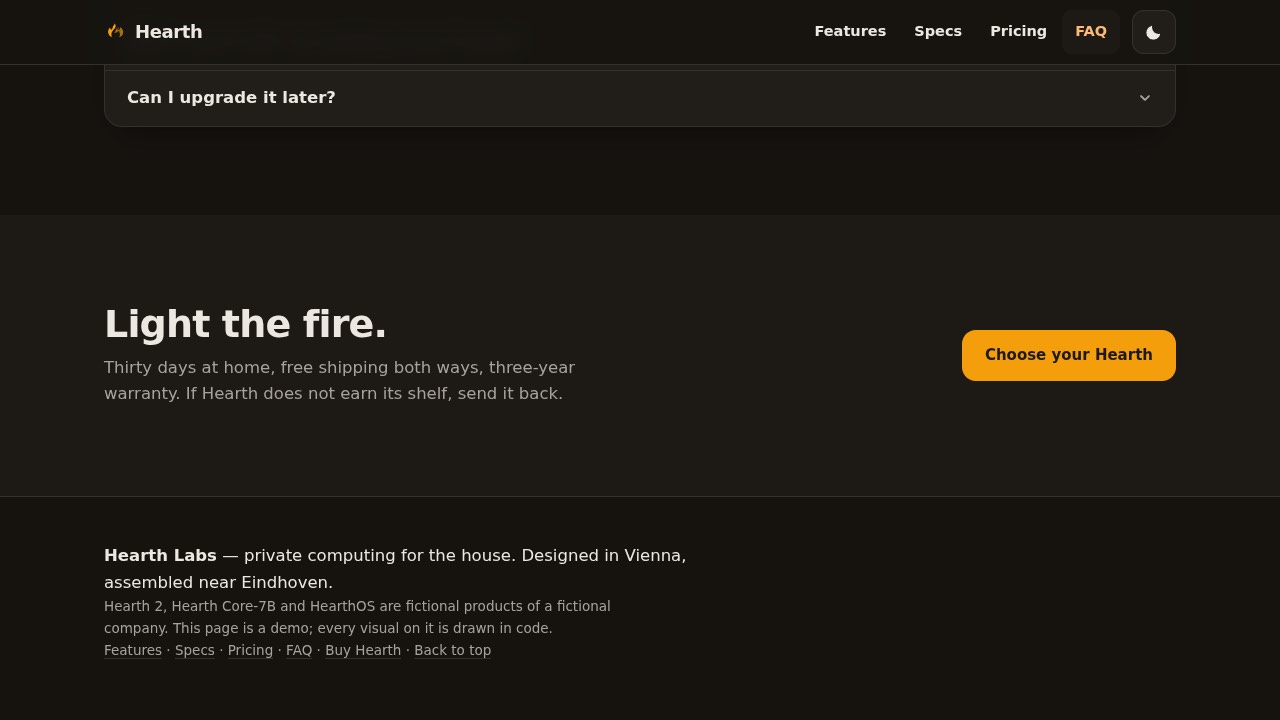
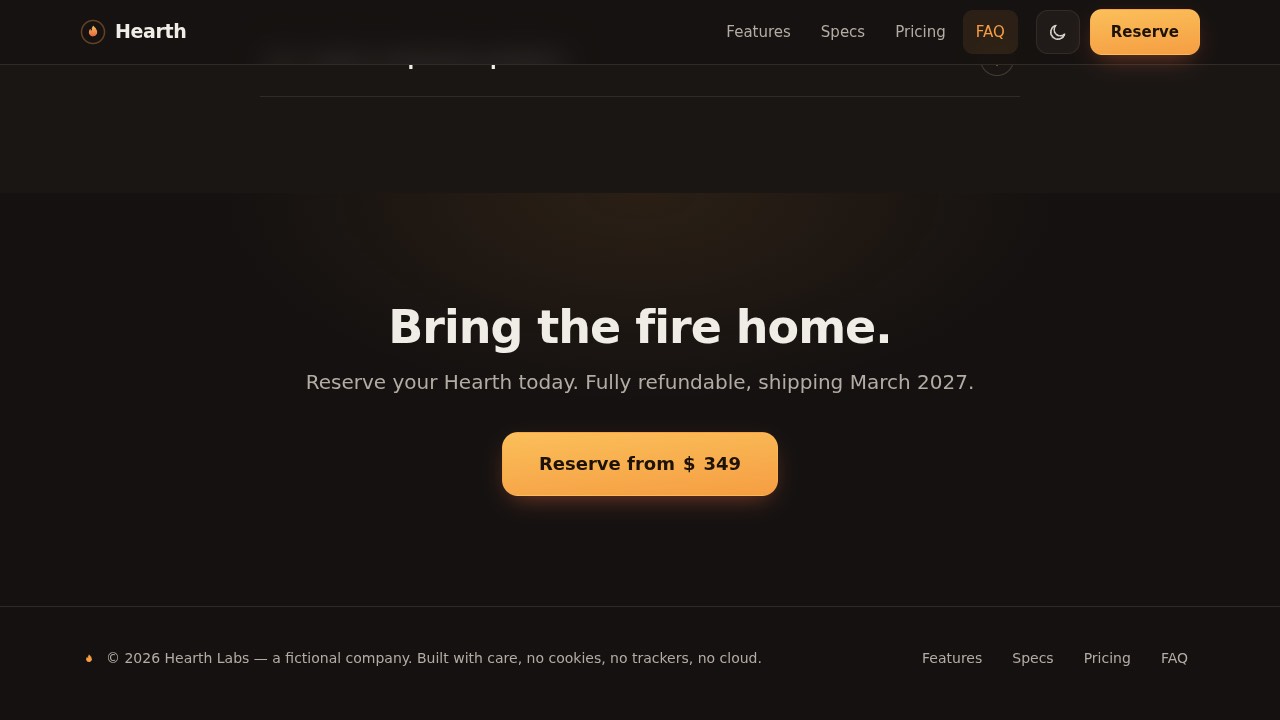
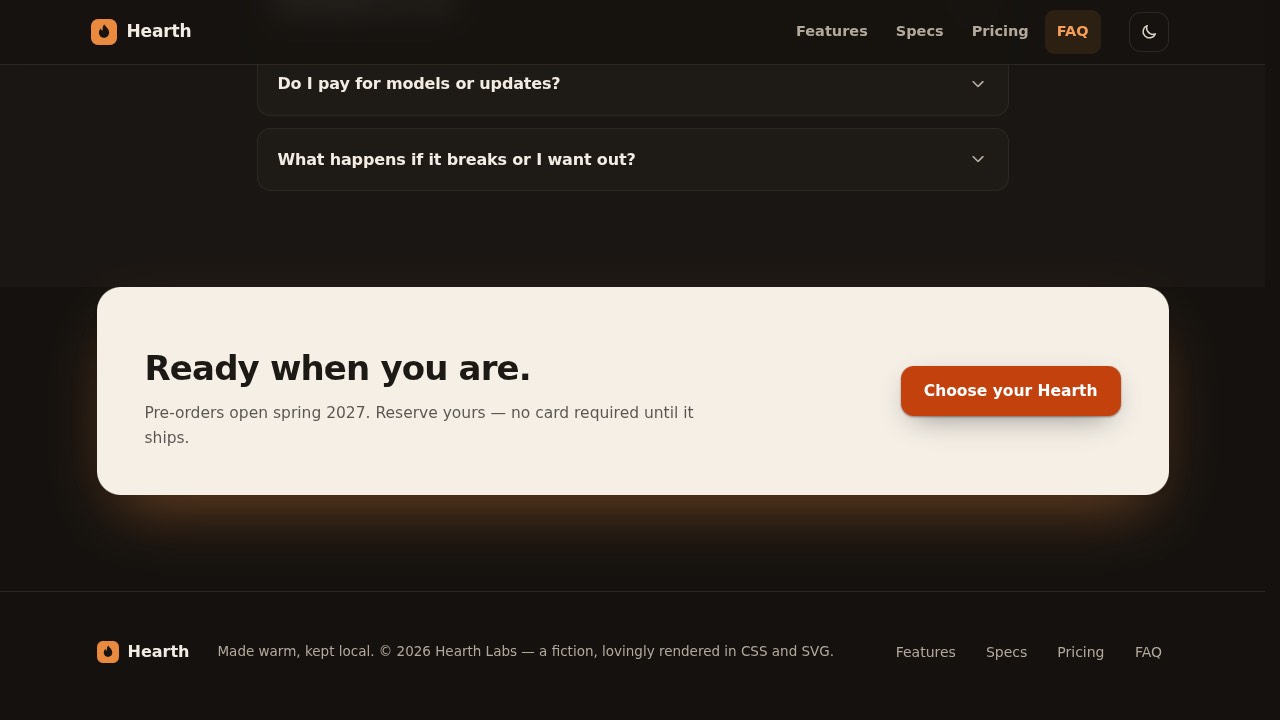
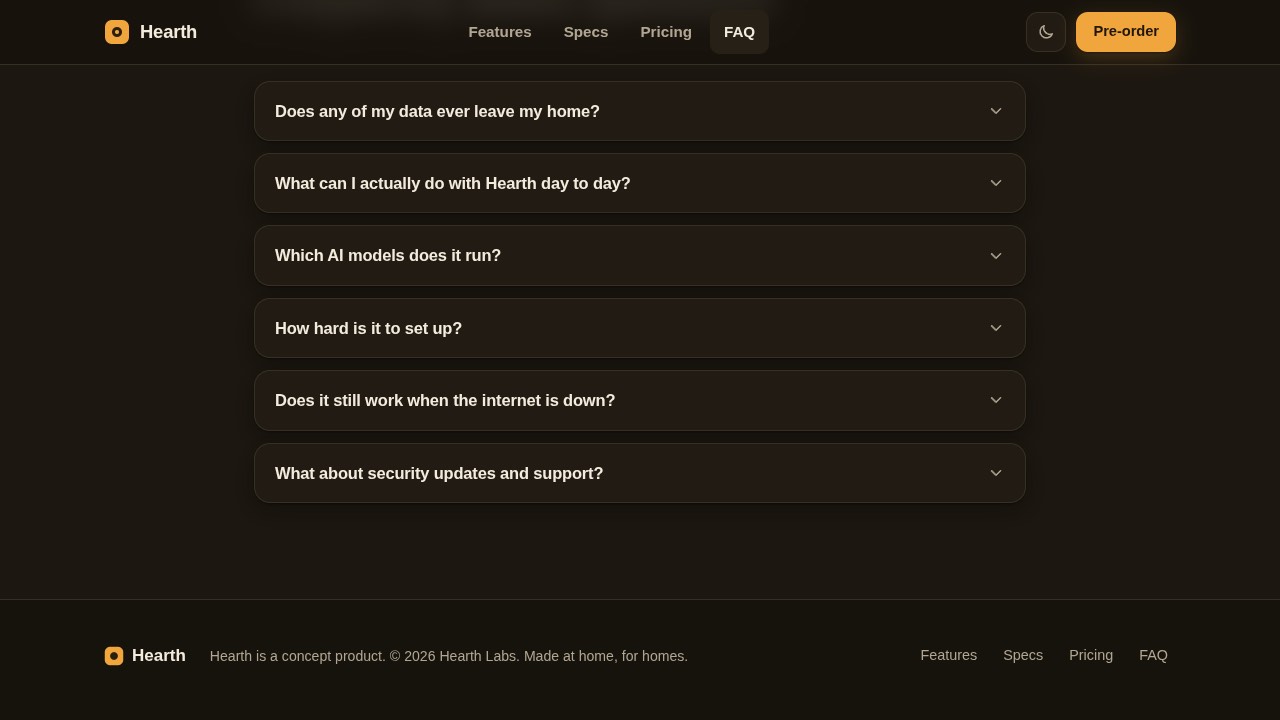
3 · Product page
310/10
310/10
310/10
310/10
310/10
310/10
310/10
310/10
310/10
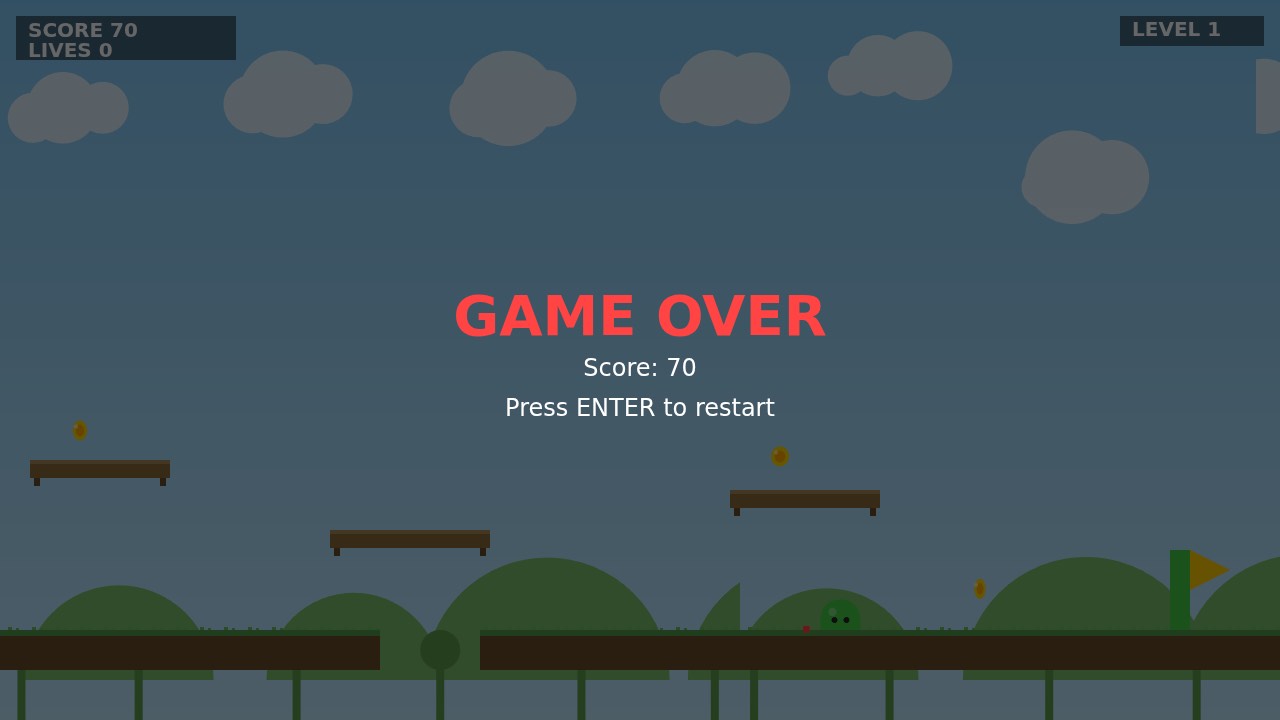
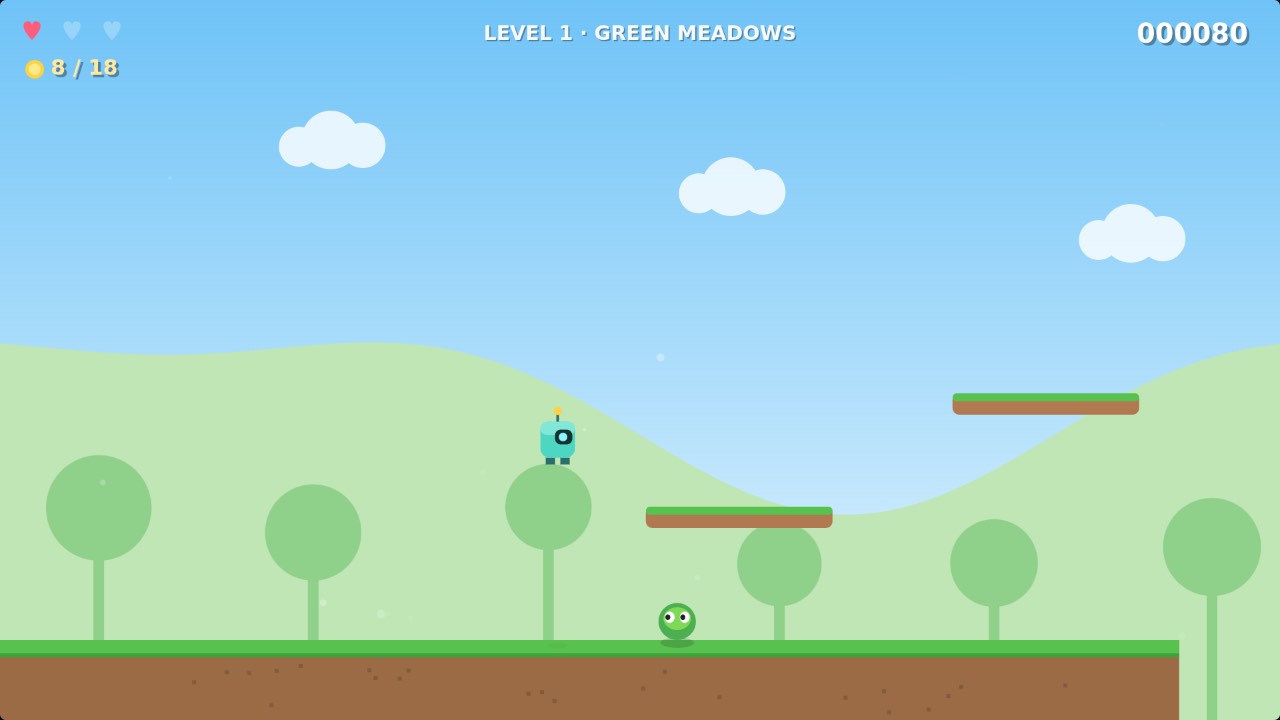
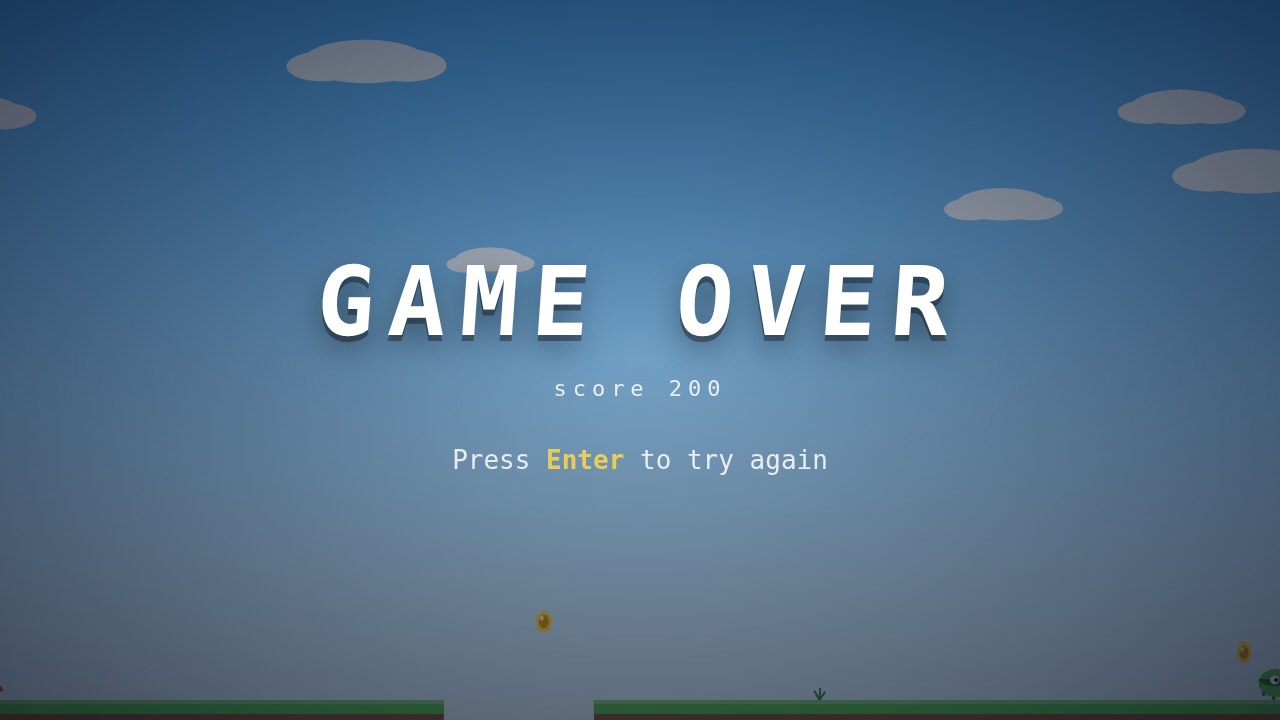
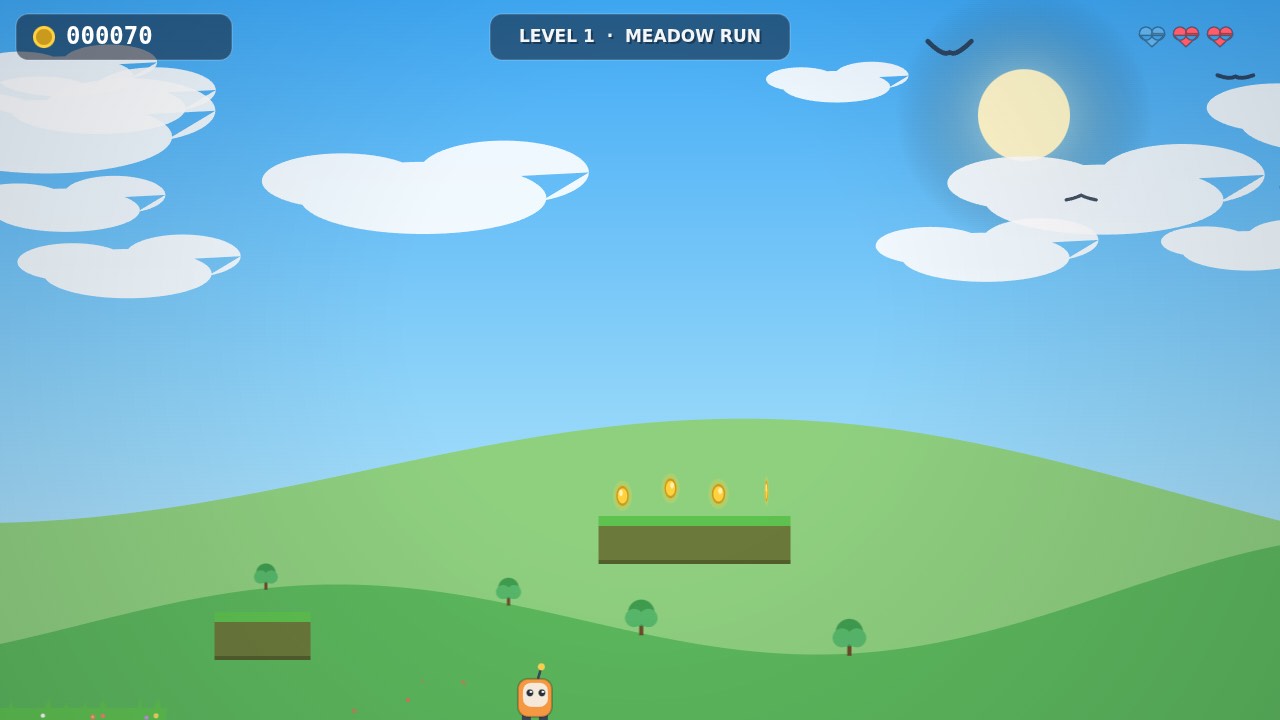
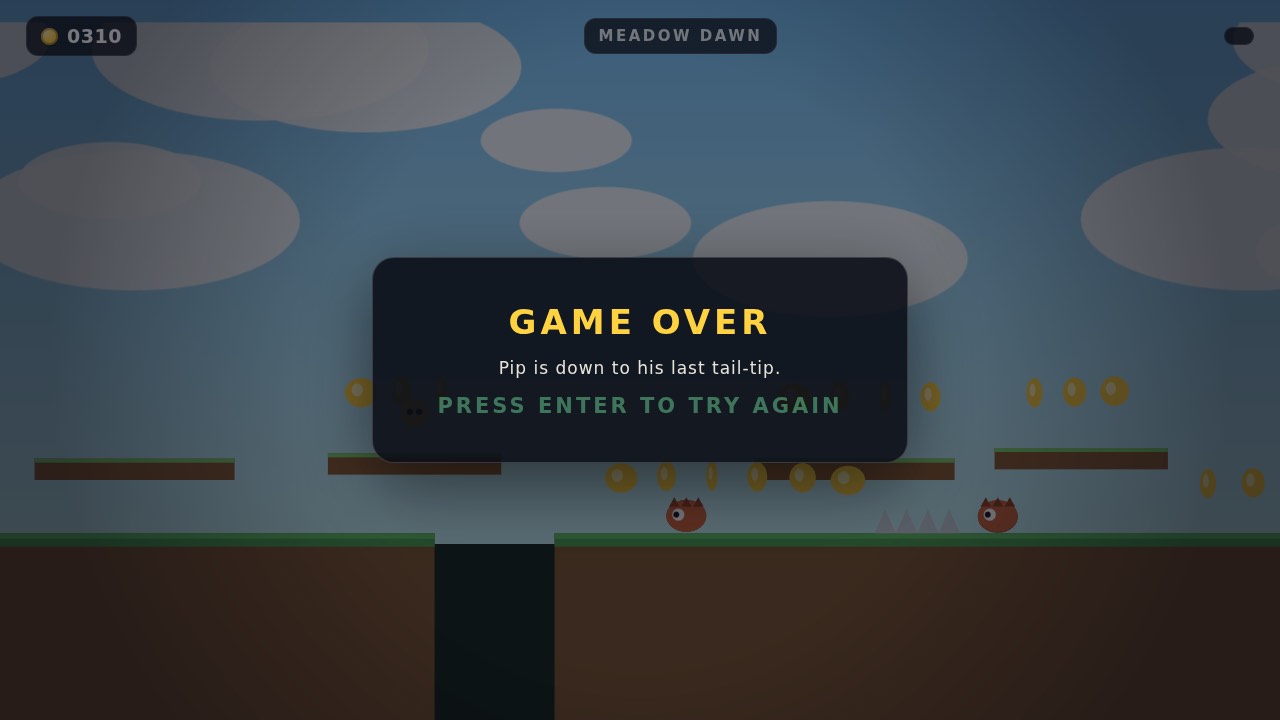
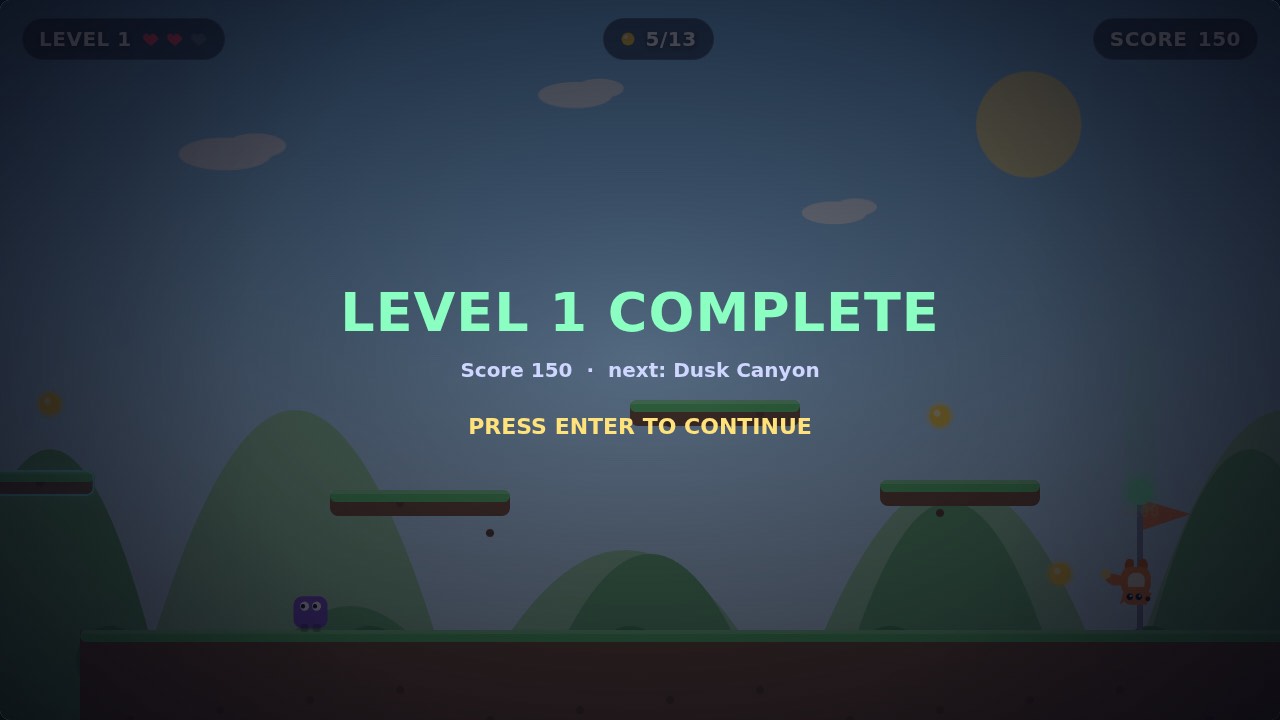
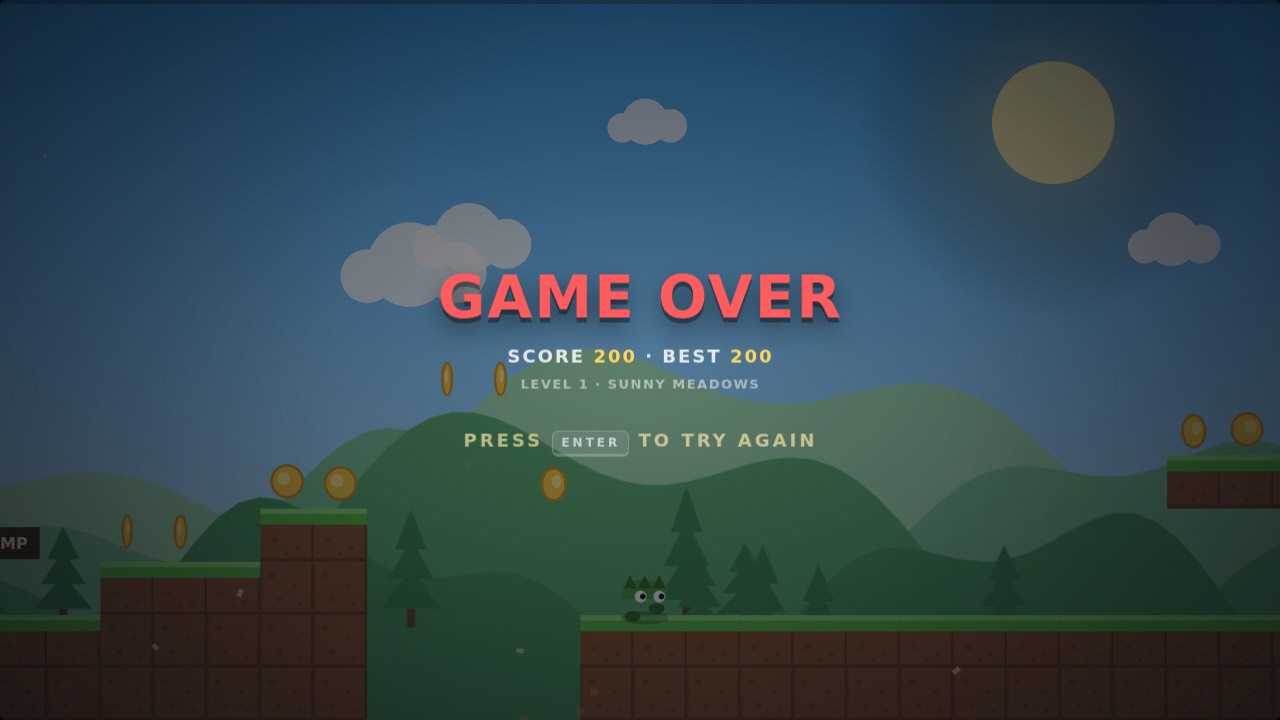
4 · Platformer game
39/9
39/9
39/9
39/9
39/9
39/9
–
39/9
39/9
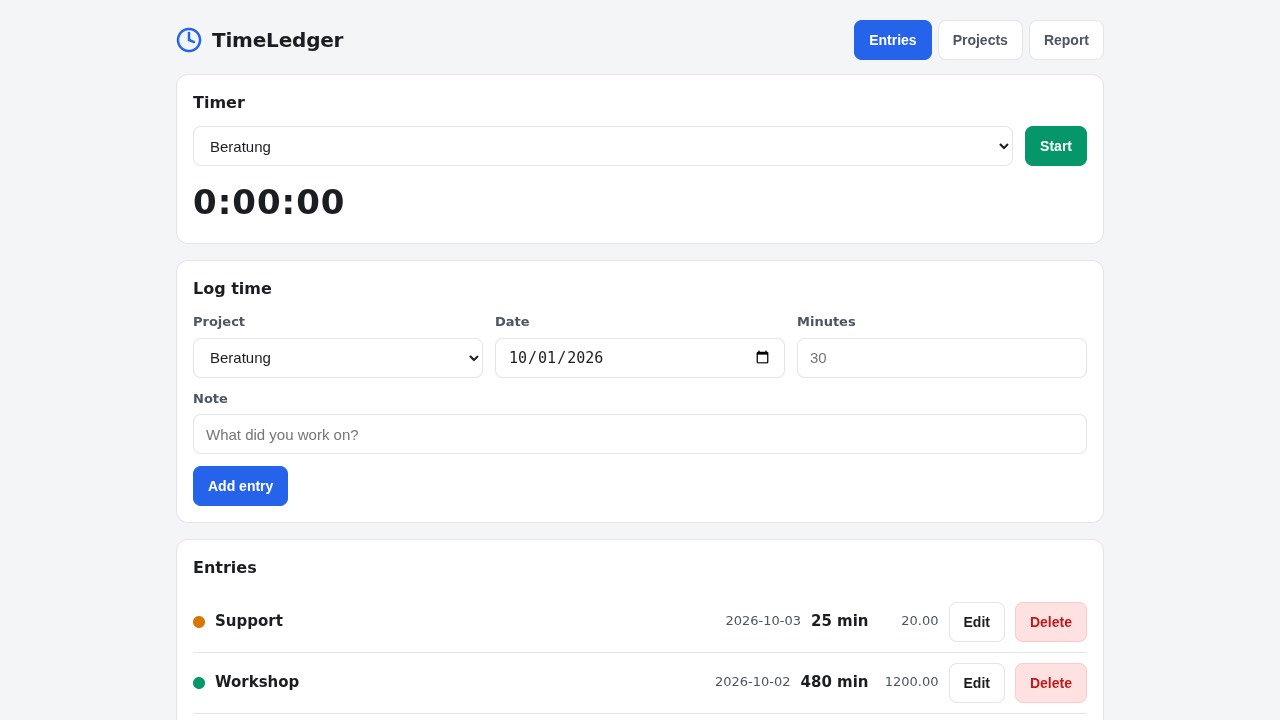
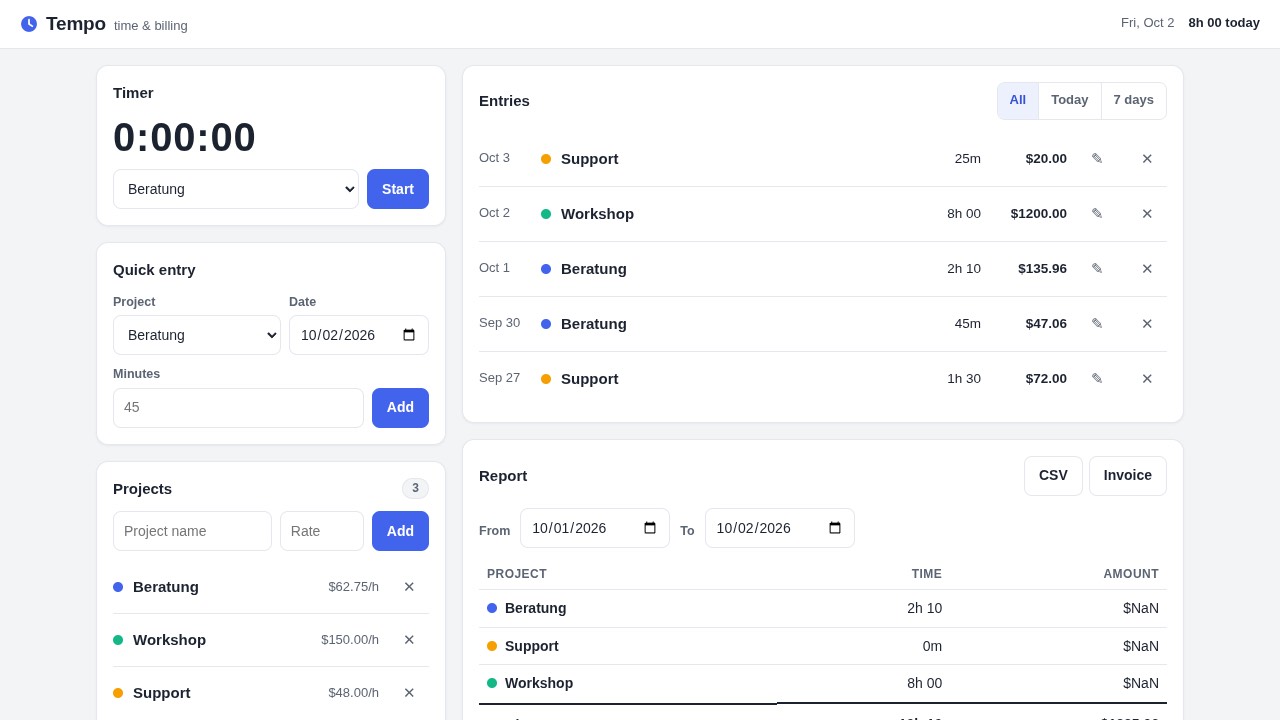
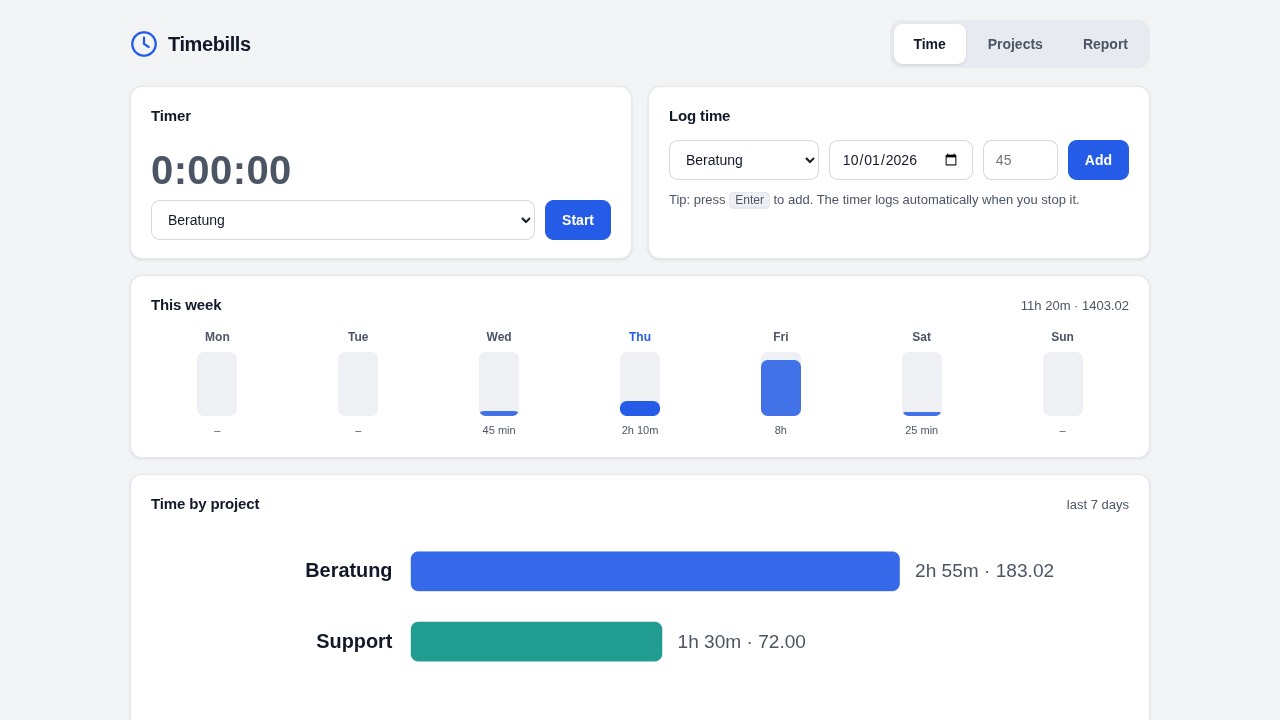
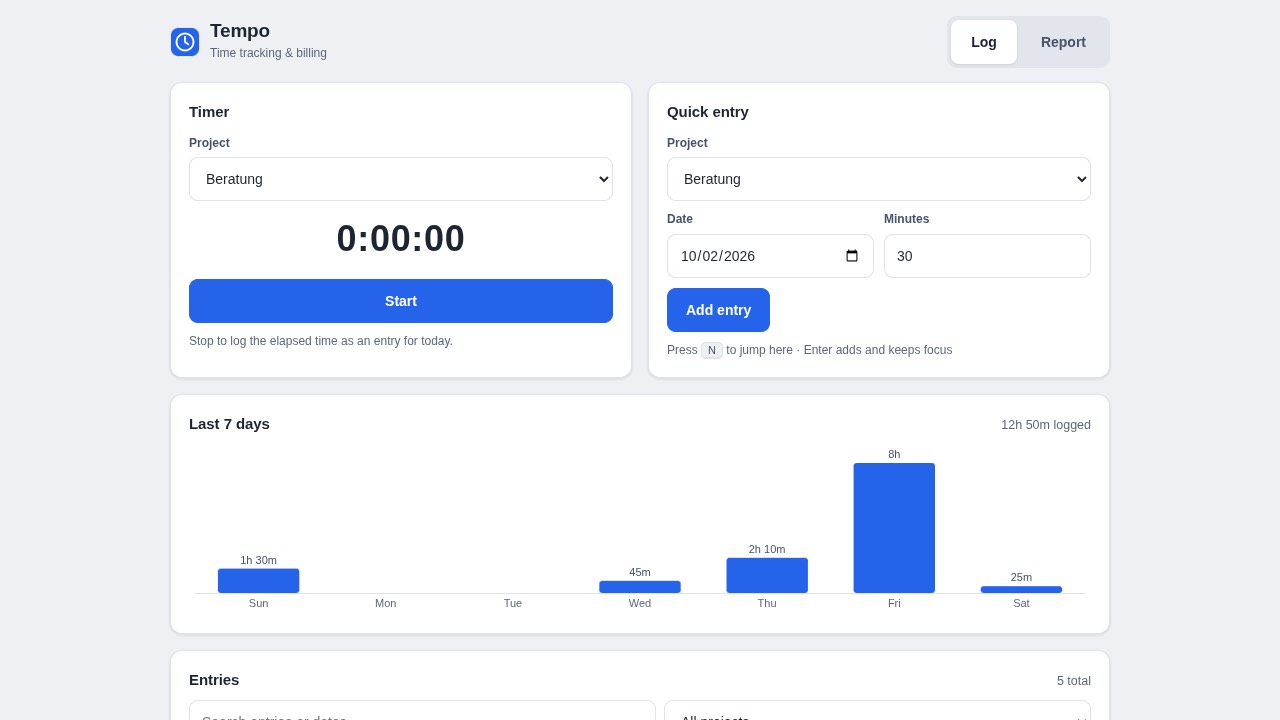
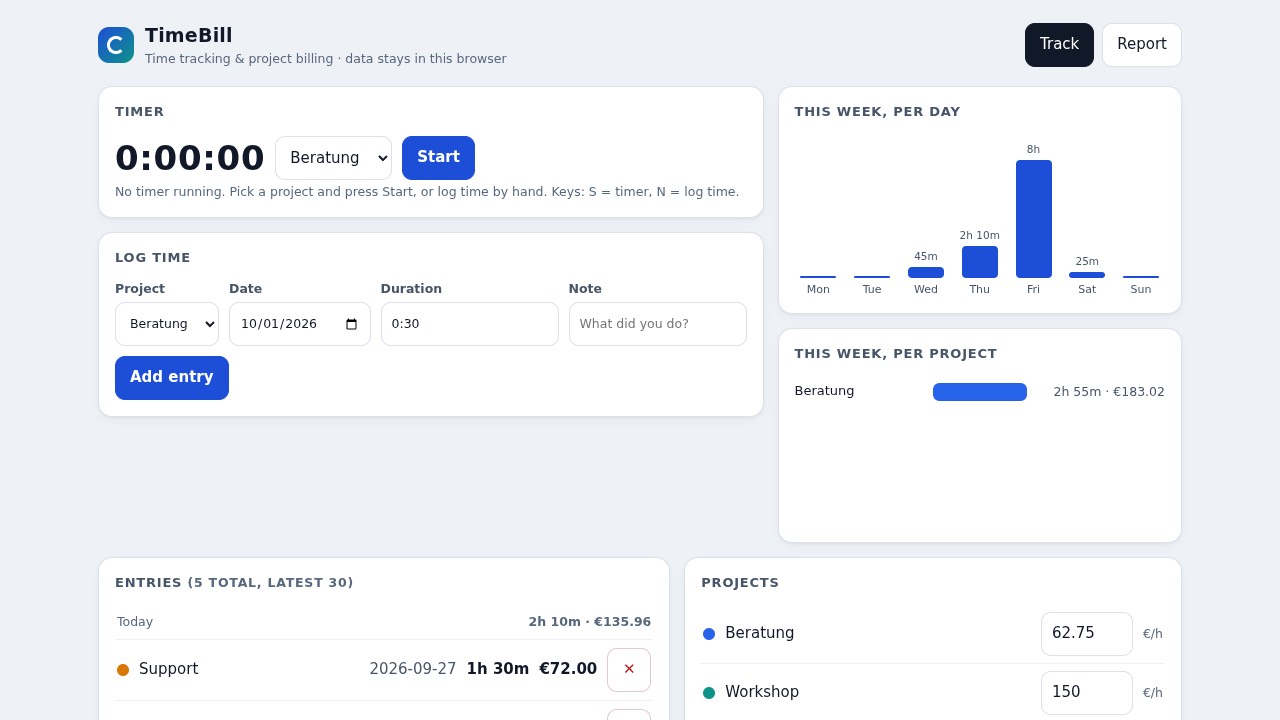
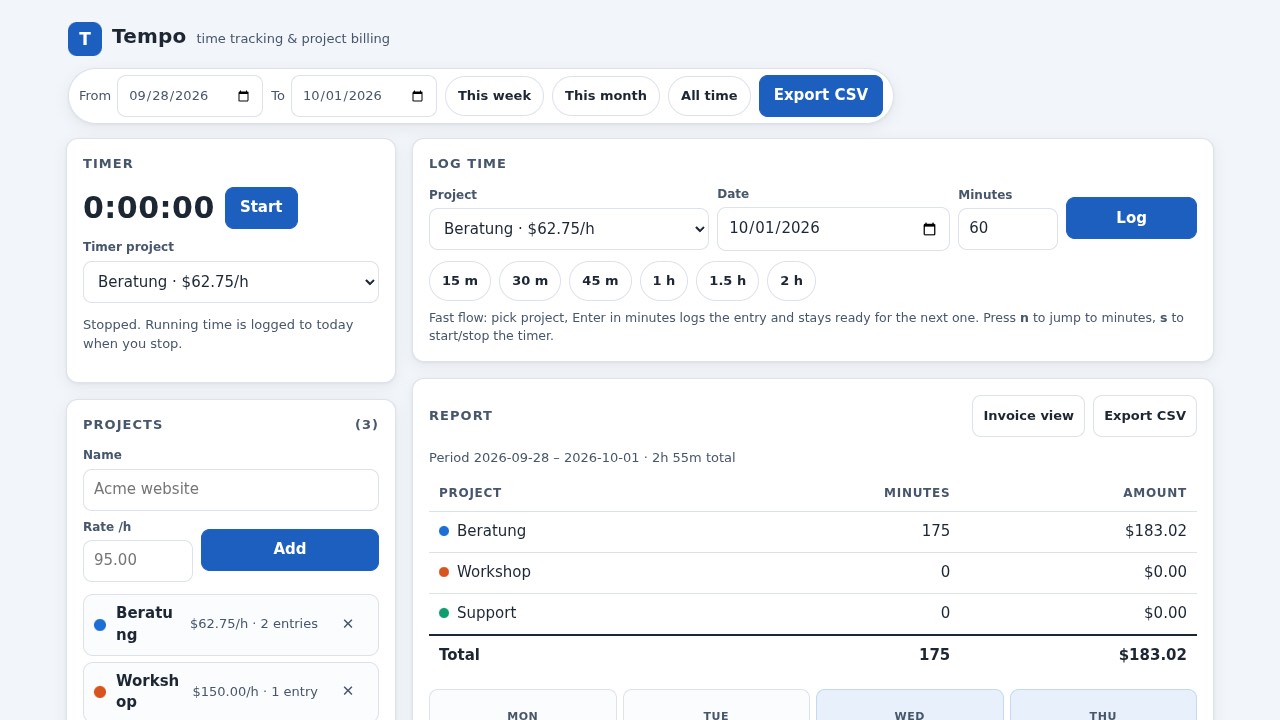
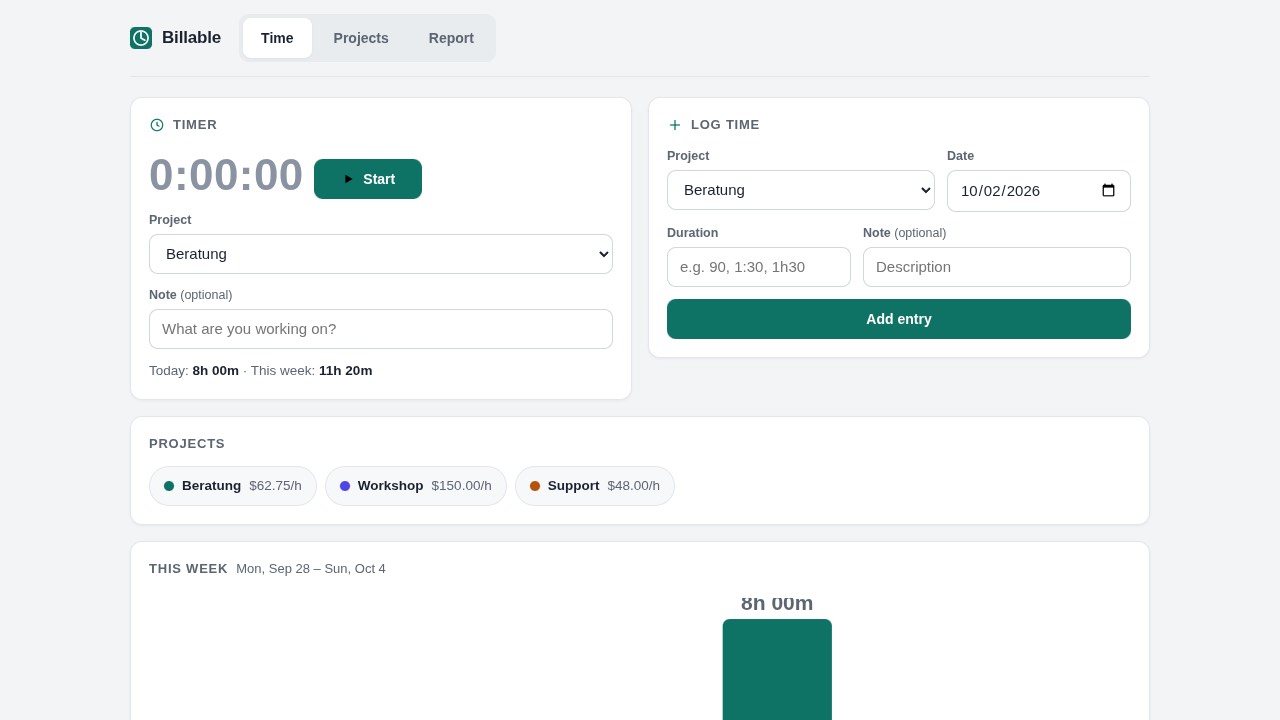
5 · Time tracker
310/10
310/10
310/10
310/10
310/10
310/10
310/10
310/10
310/10
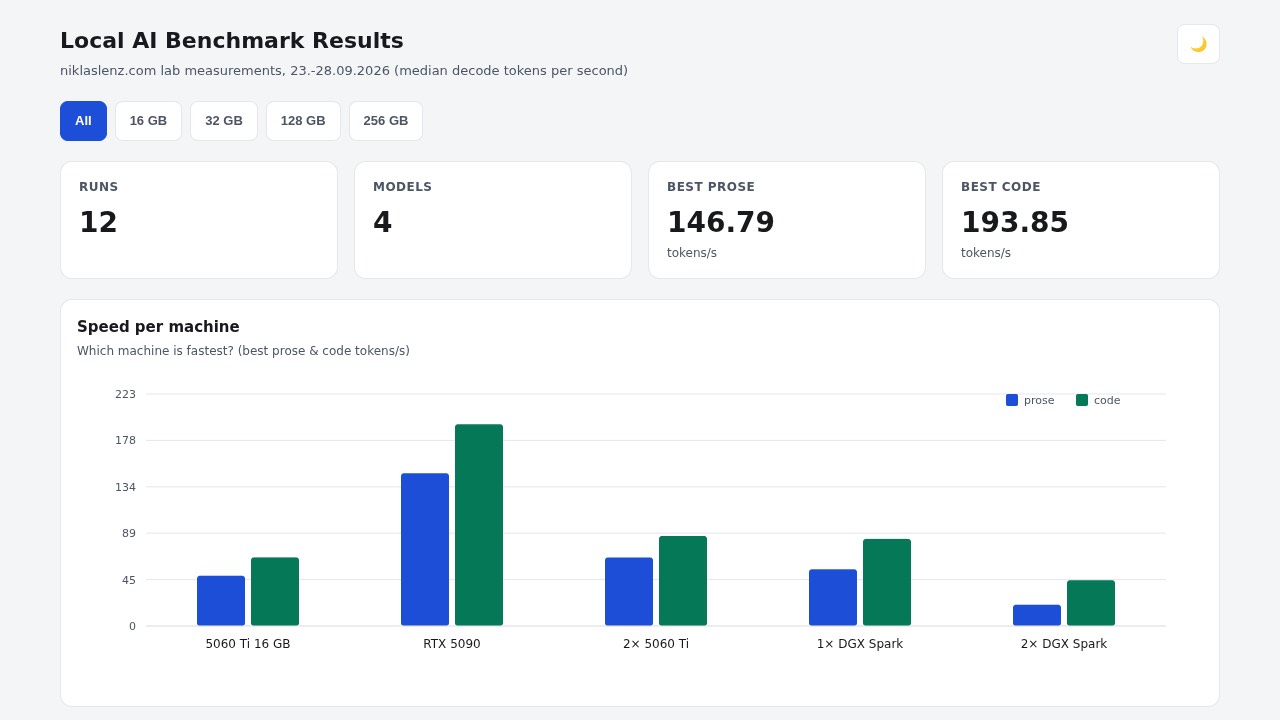
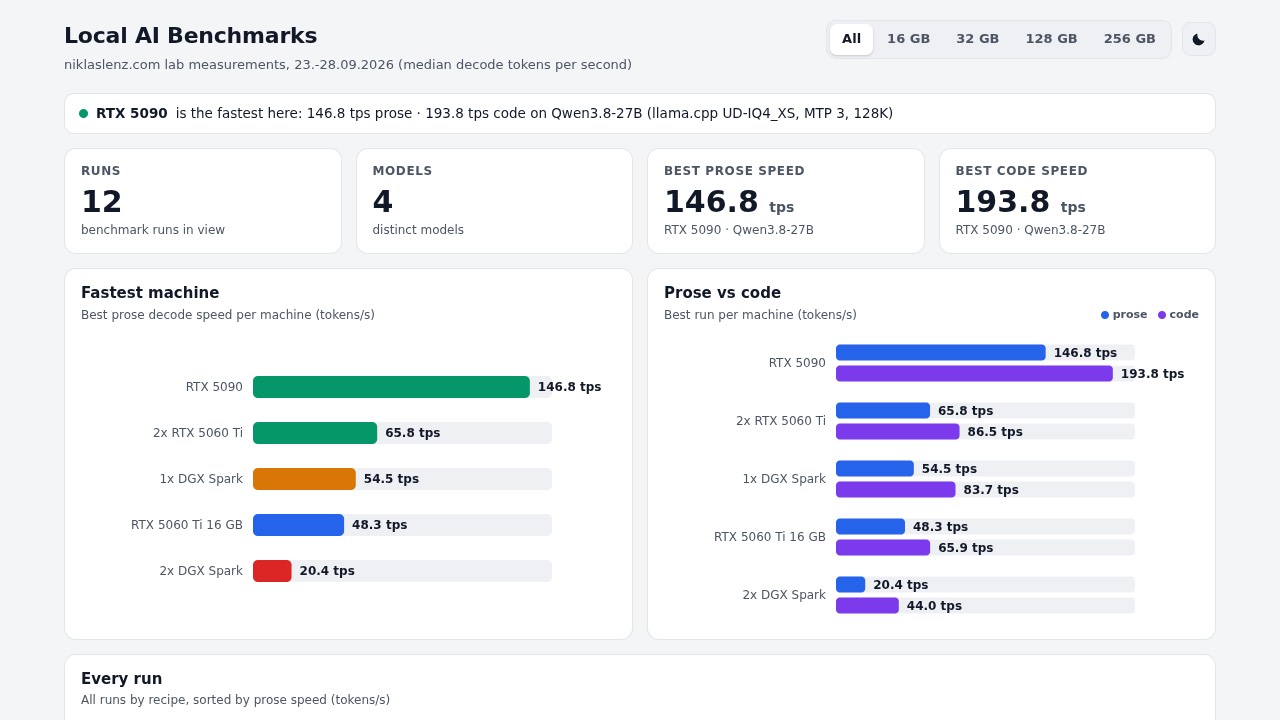
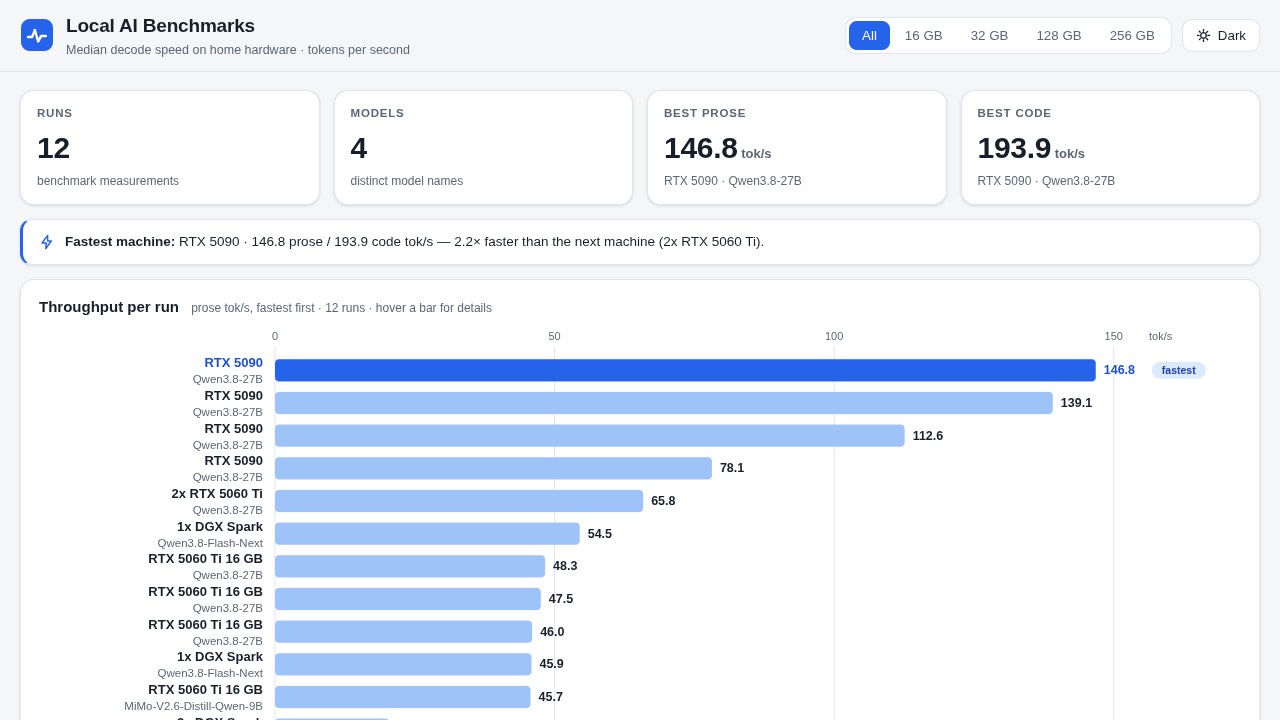
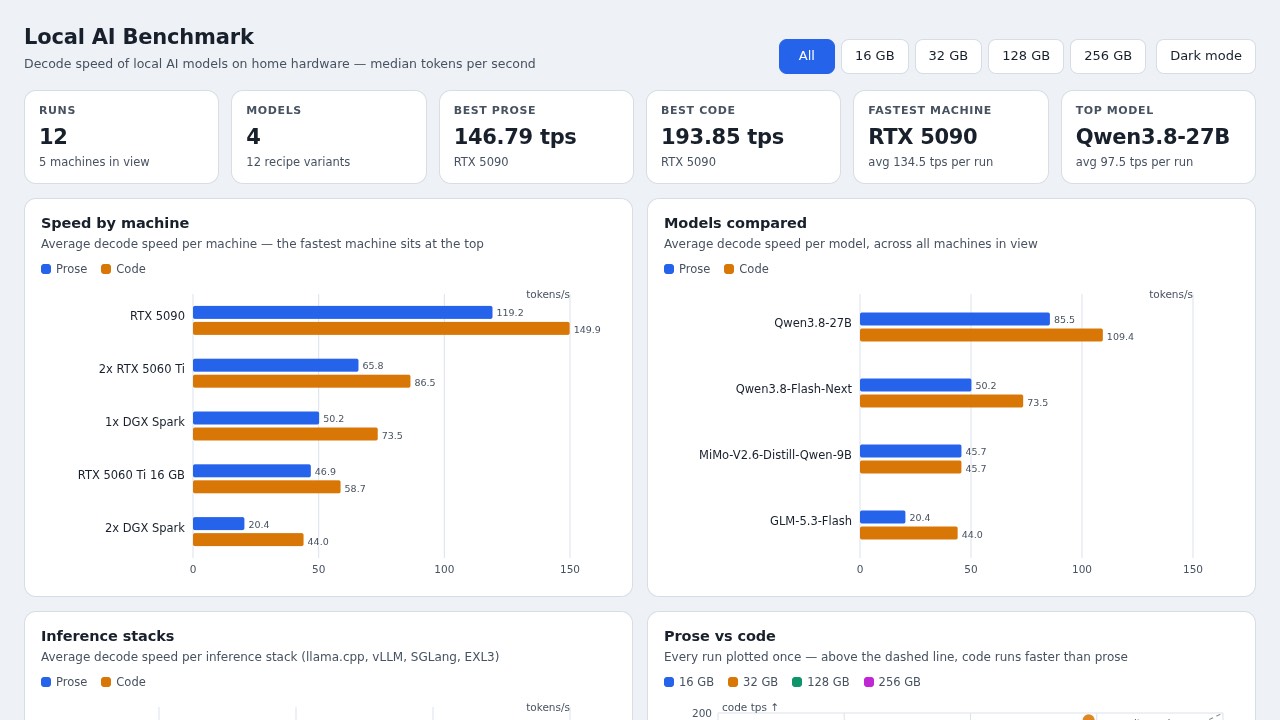
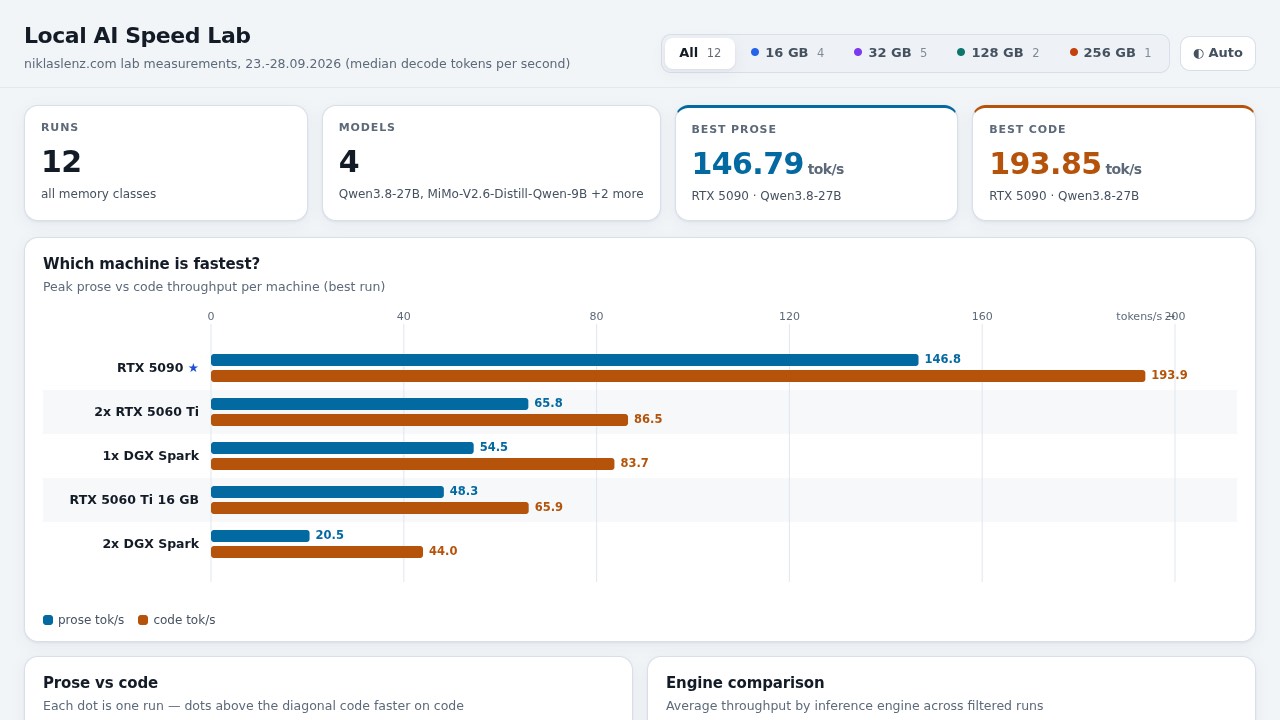
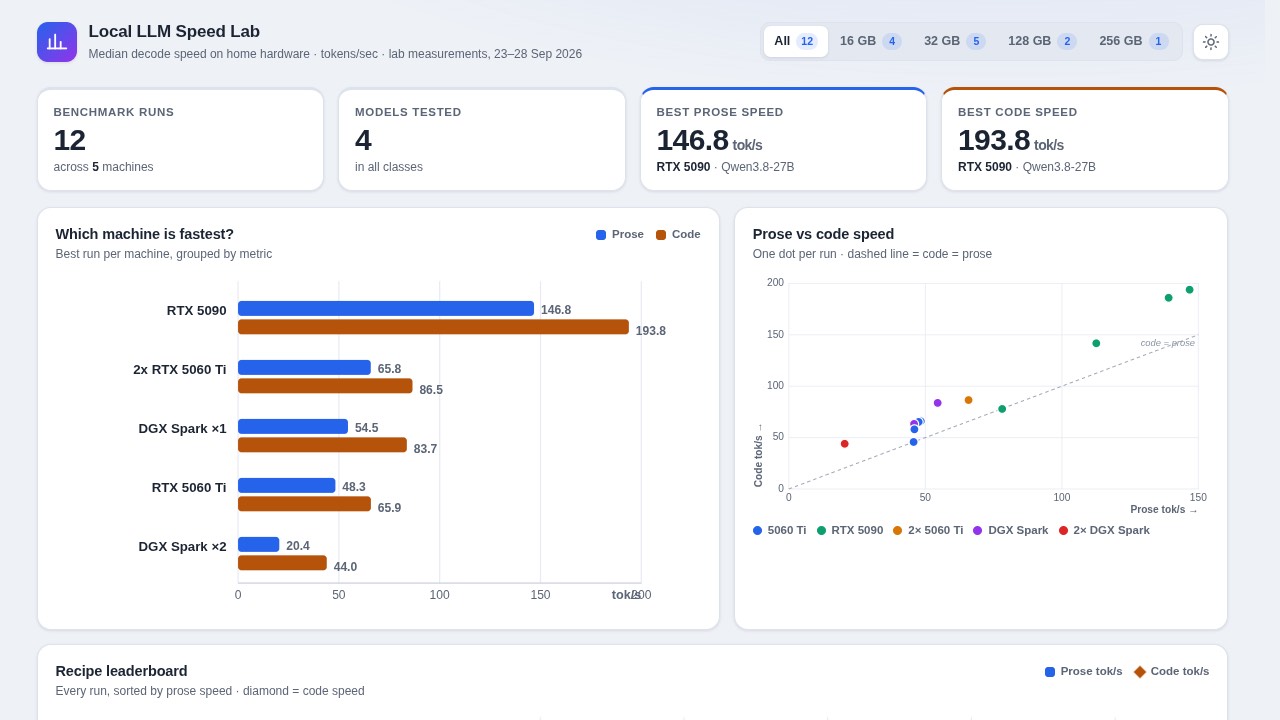
6 · Dashboard
39/9
39/9
39/9
39/9
39/9
39/9
28/9
39/9
39/9
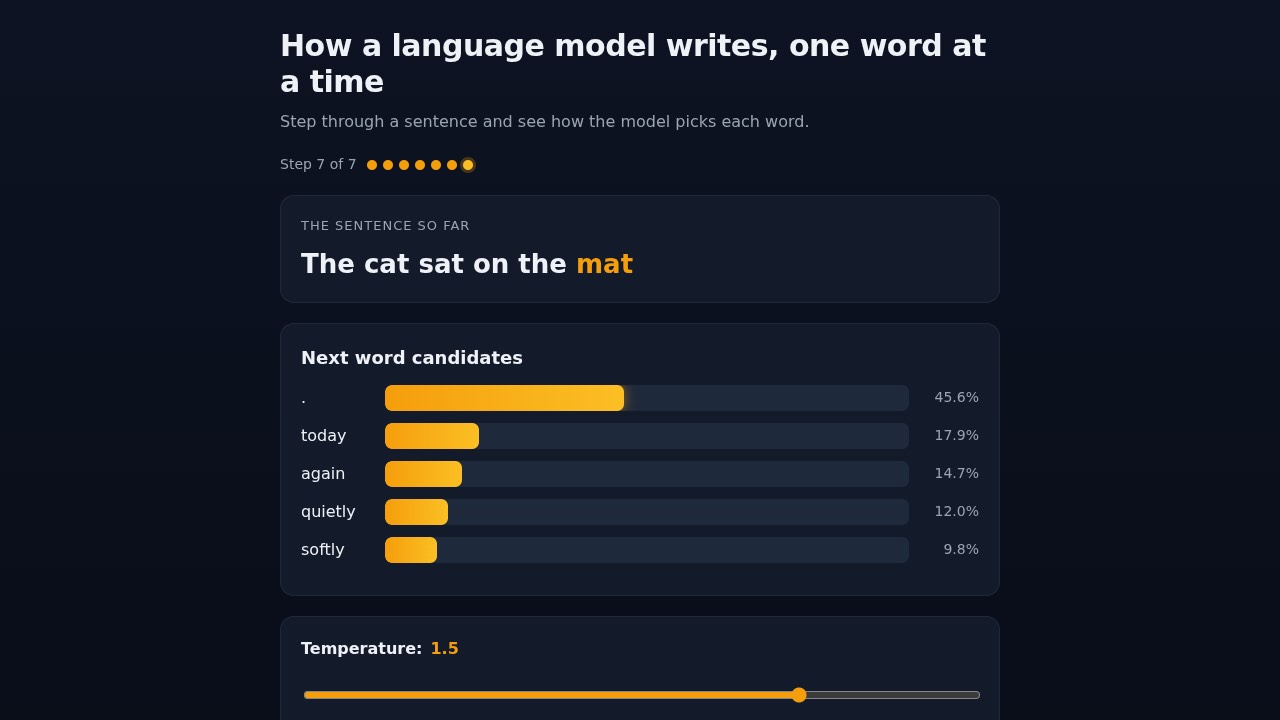
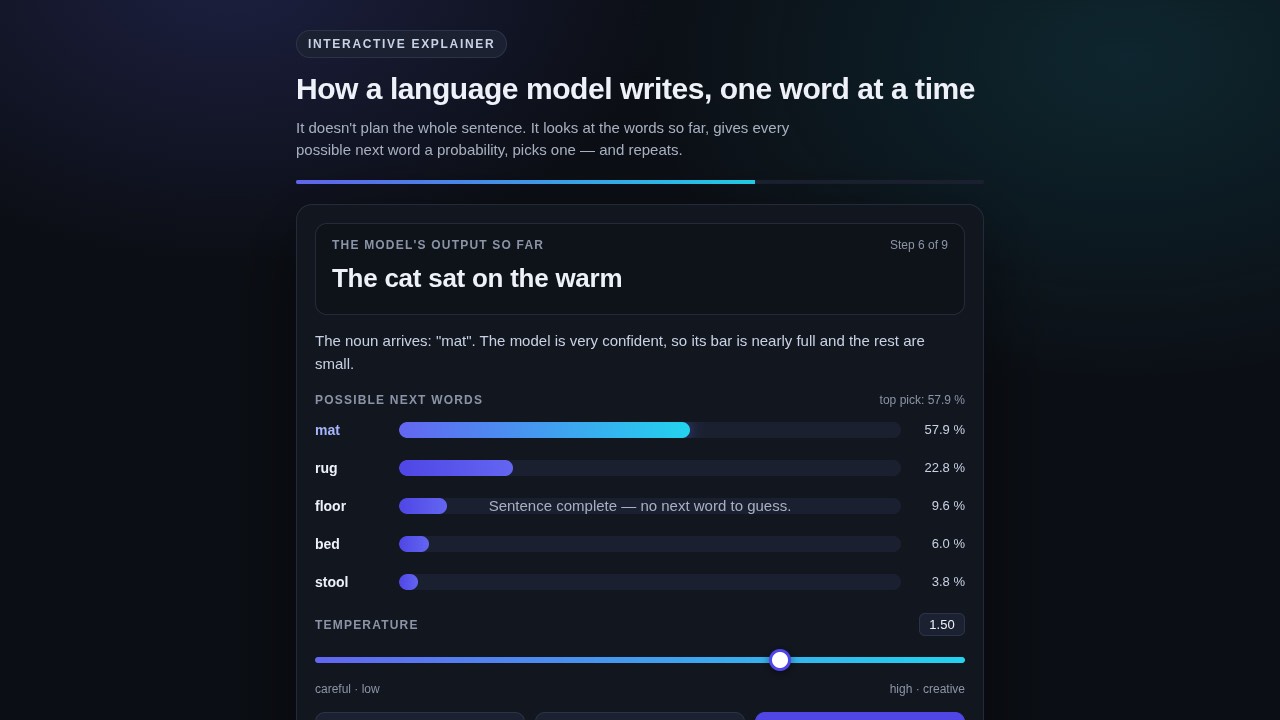
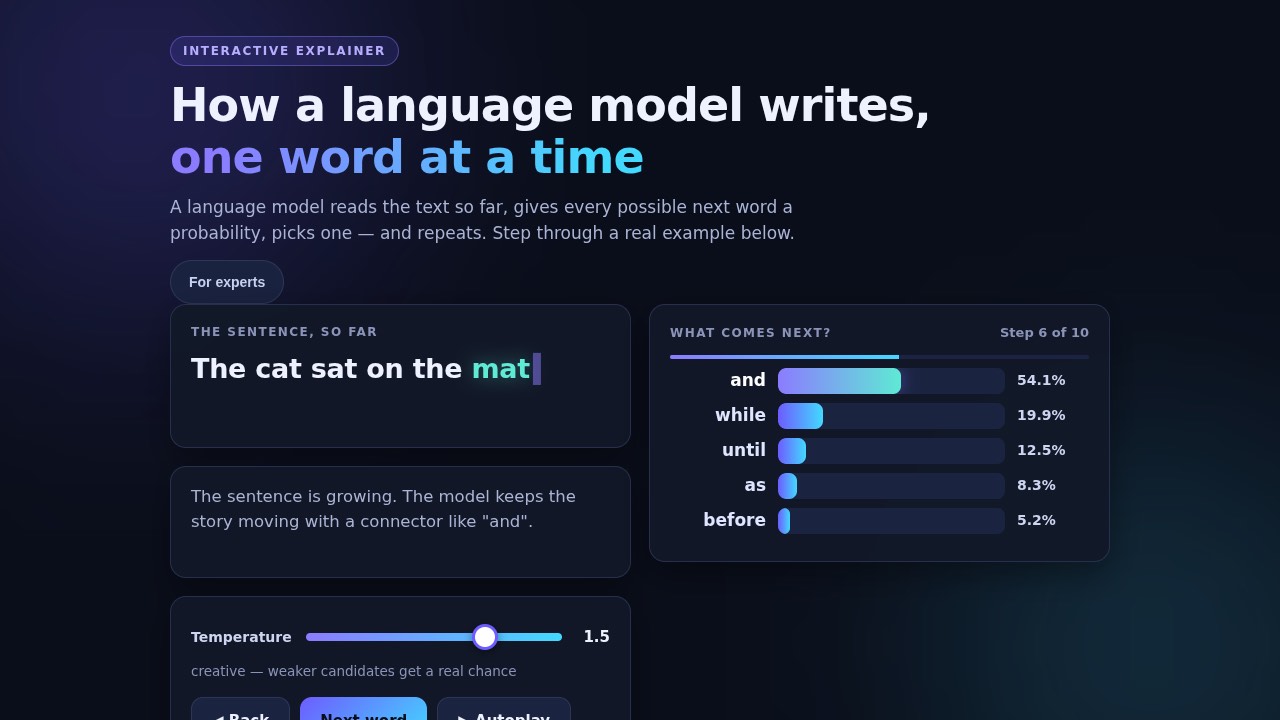
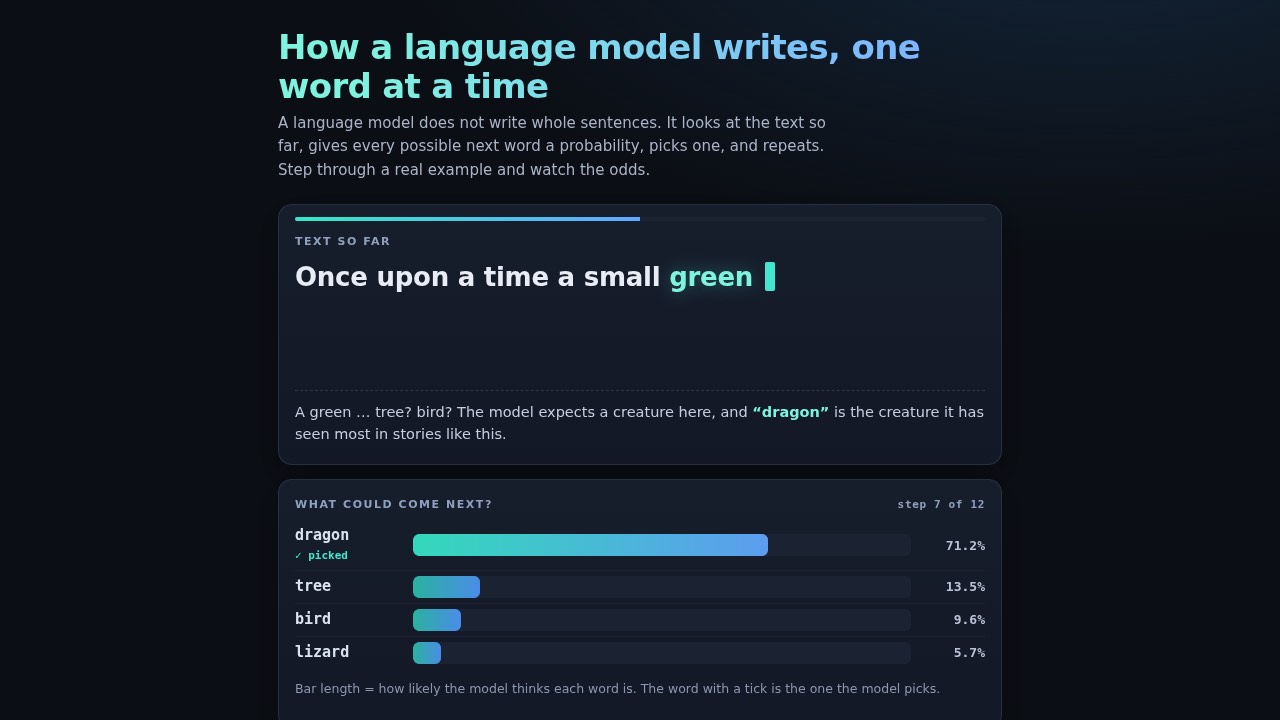
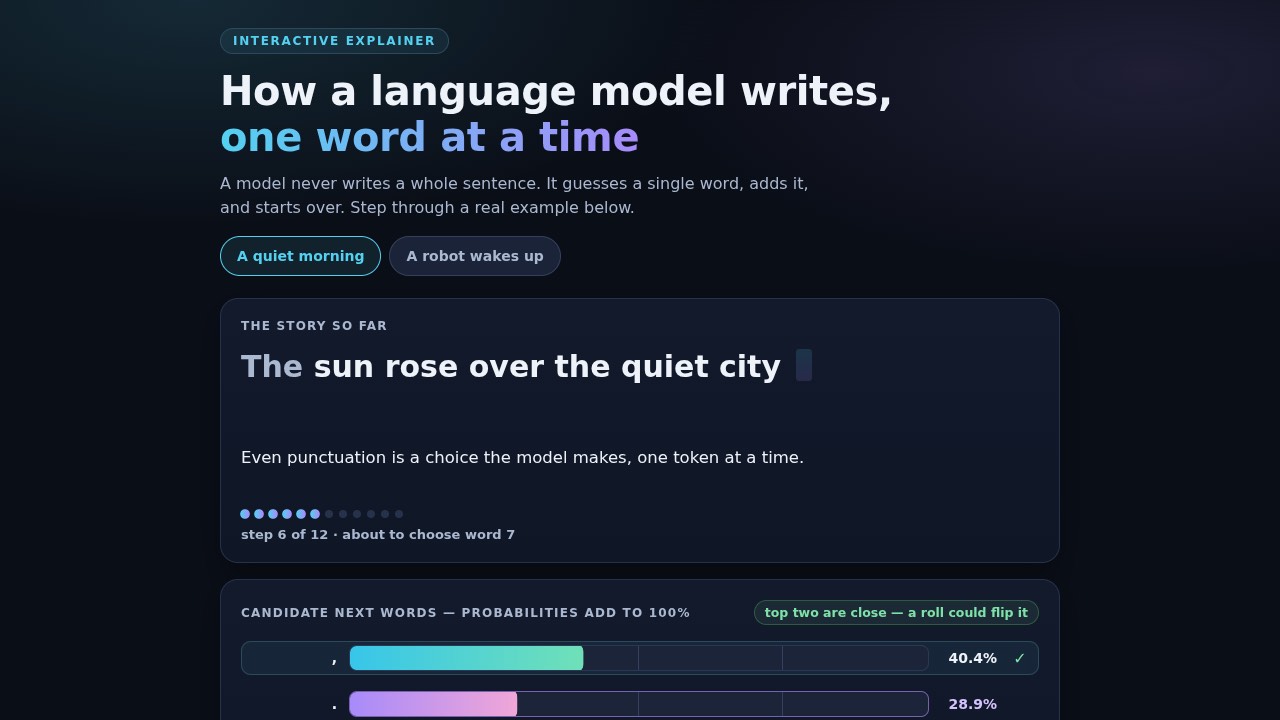
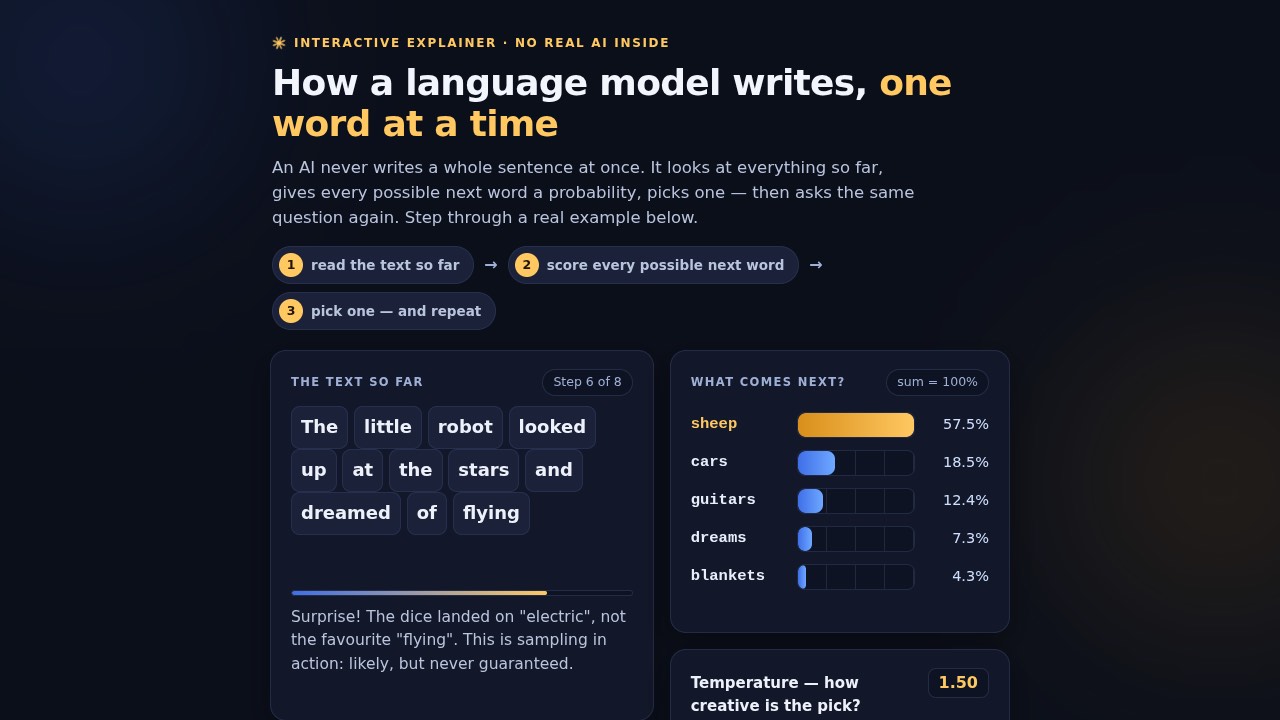
7 · Interactive explainer
39/9
39/9
39/9
39/9
39/9
39/9
39/9
39/9
39/9
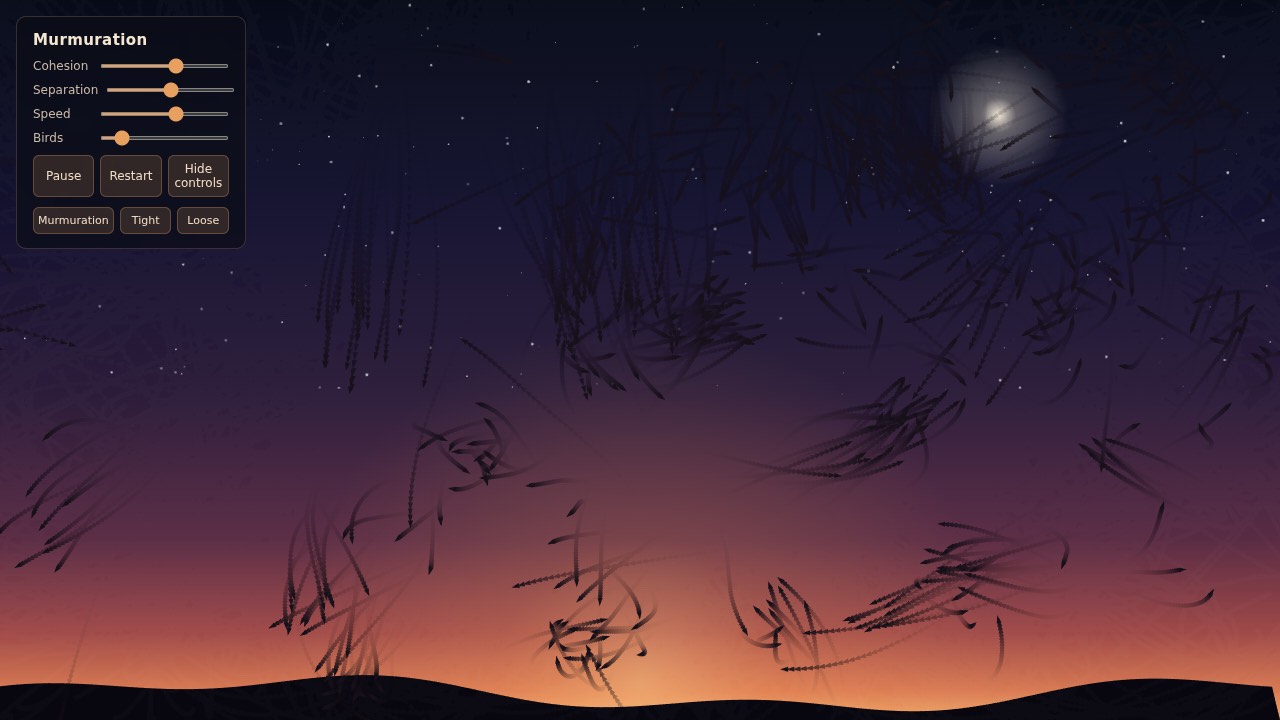
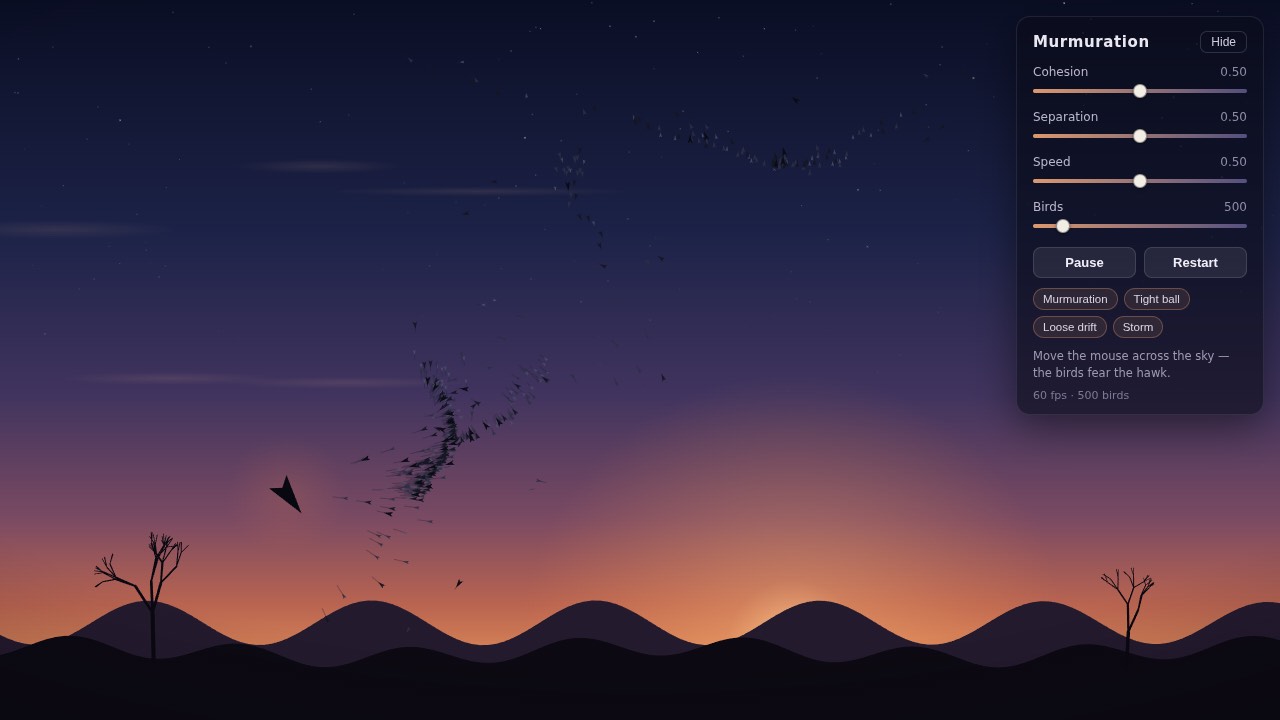
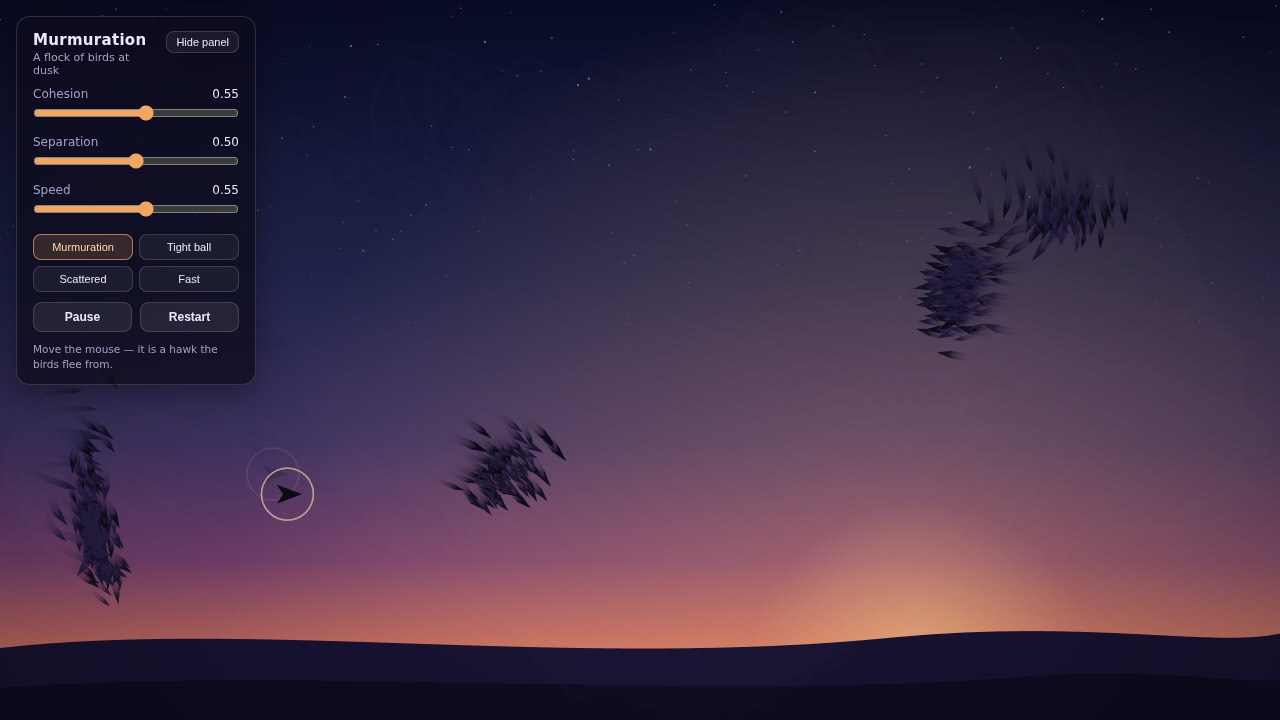
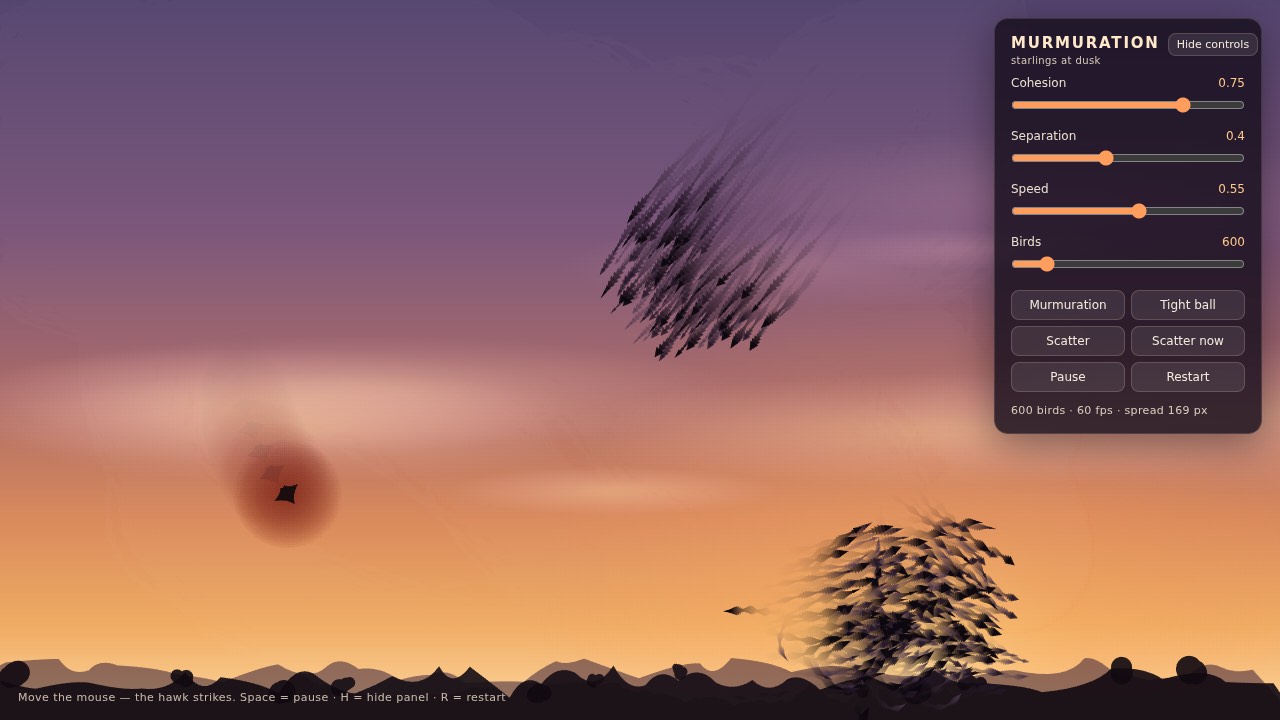
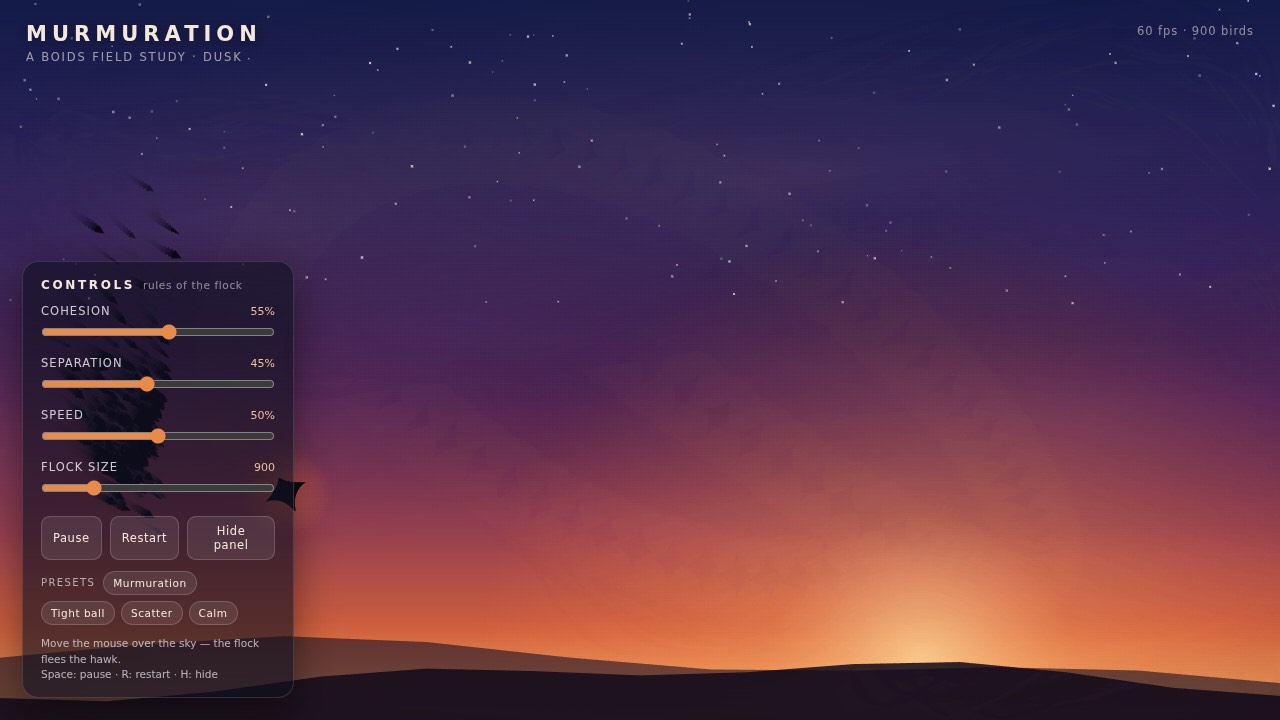
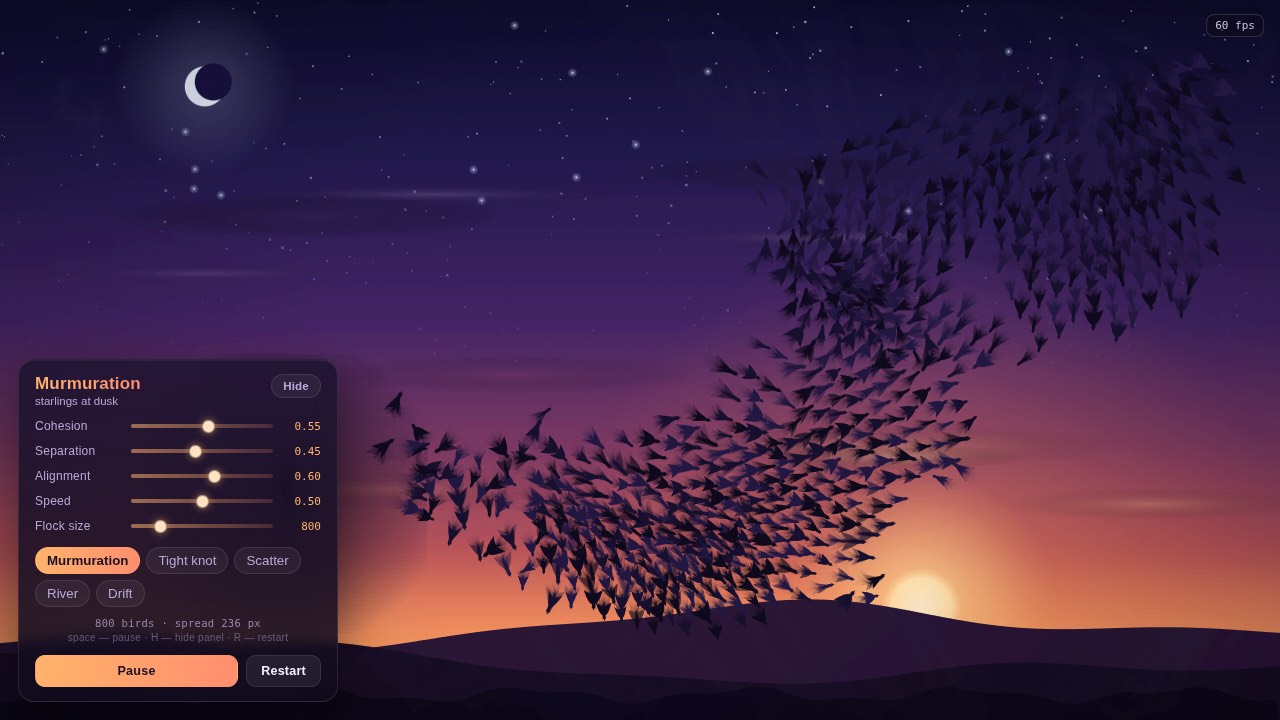
8 · Bird flock
38/8
38/8
16/8
17/8
38/8
17/8
38/8
38/8
38/8
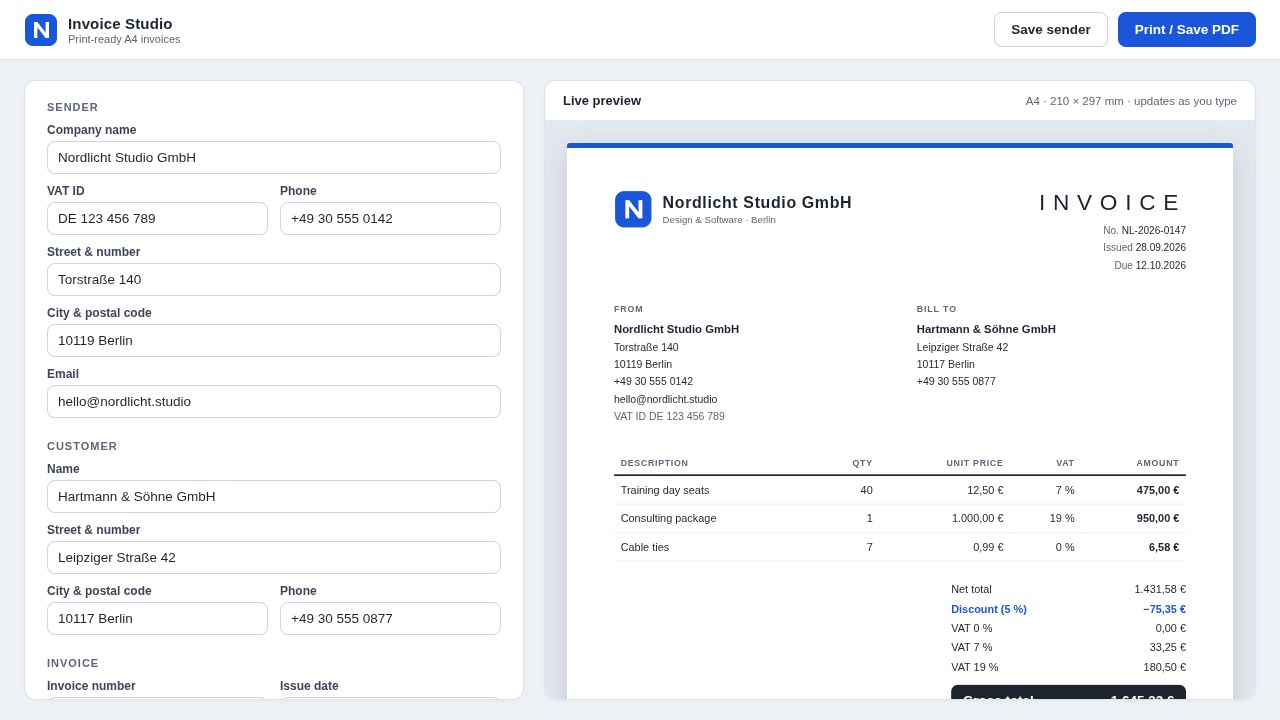
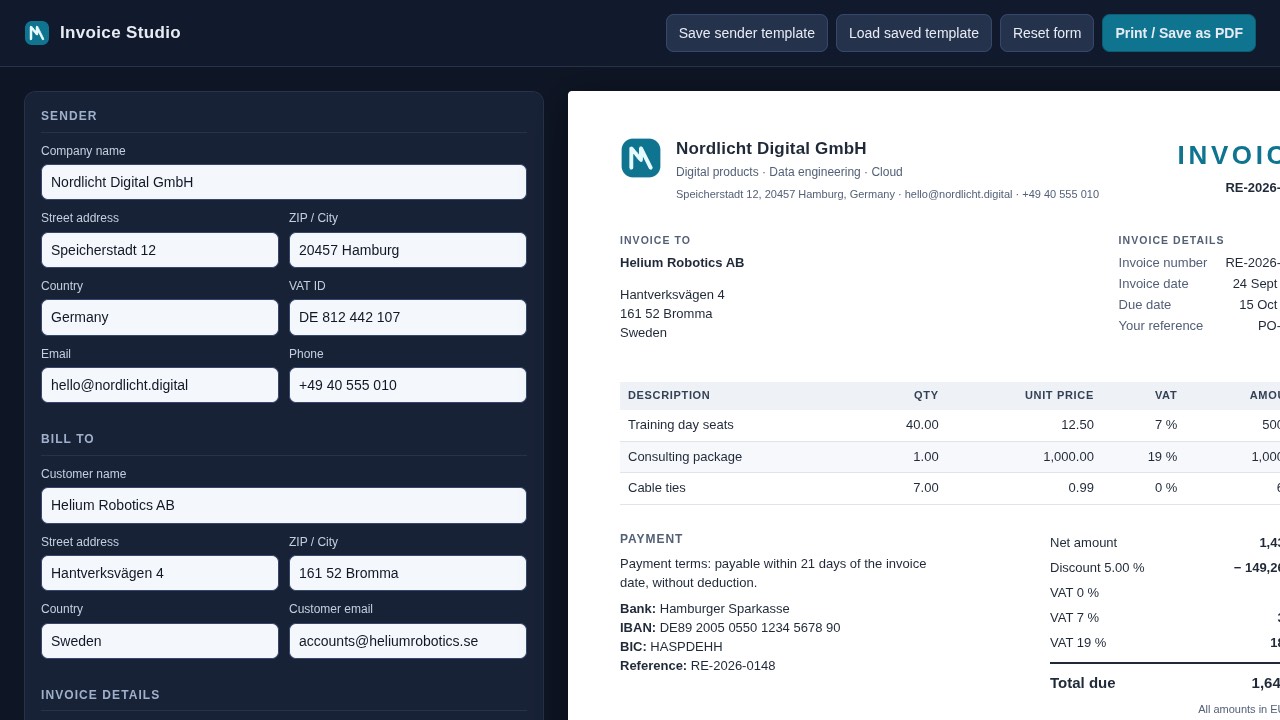
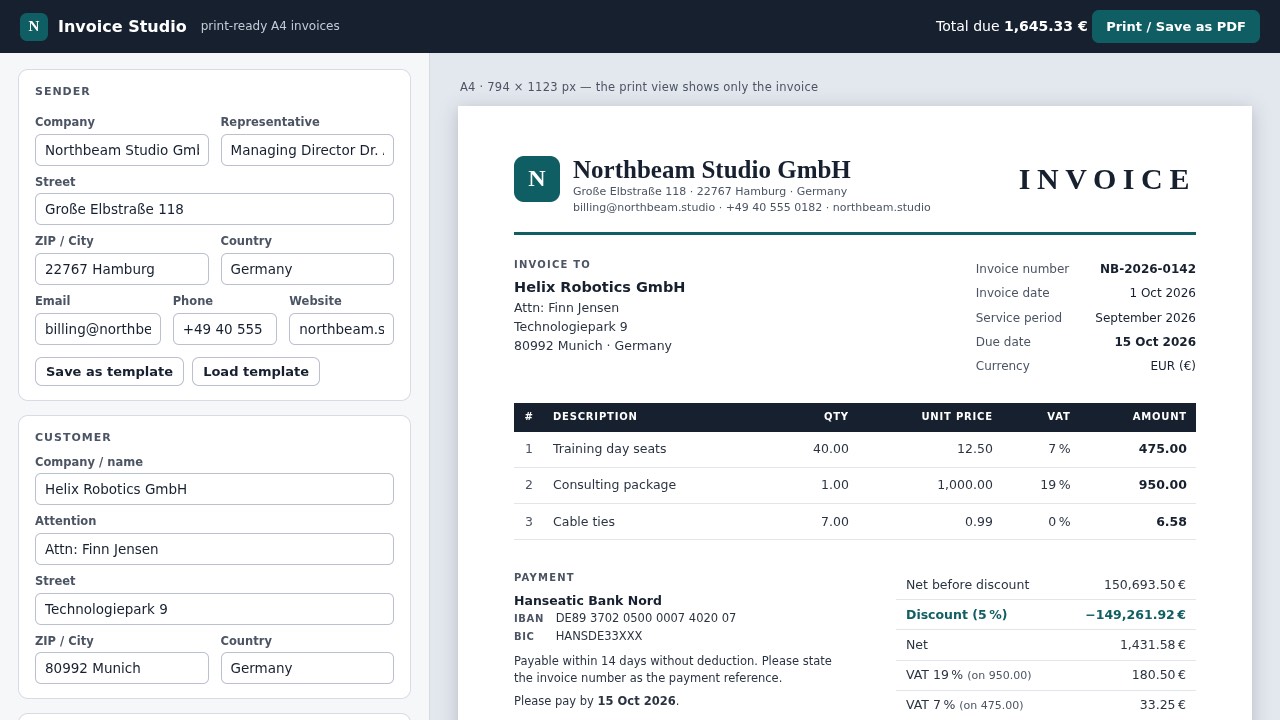
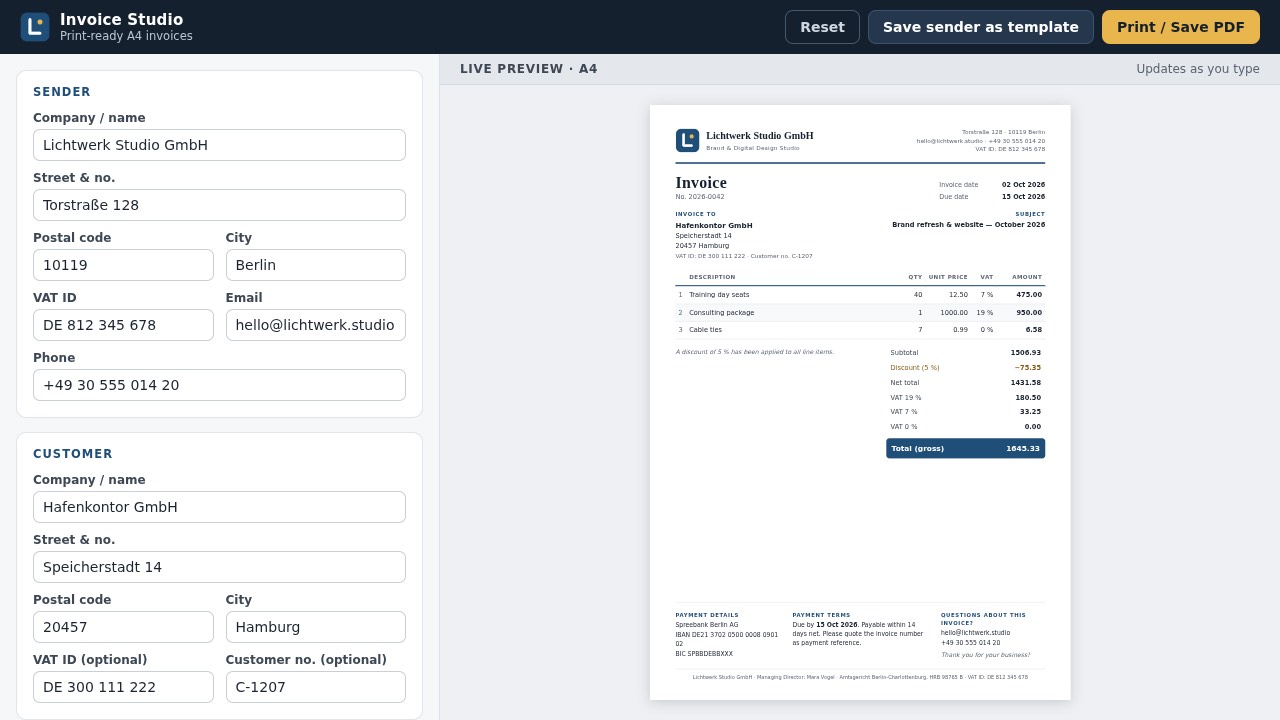
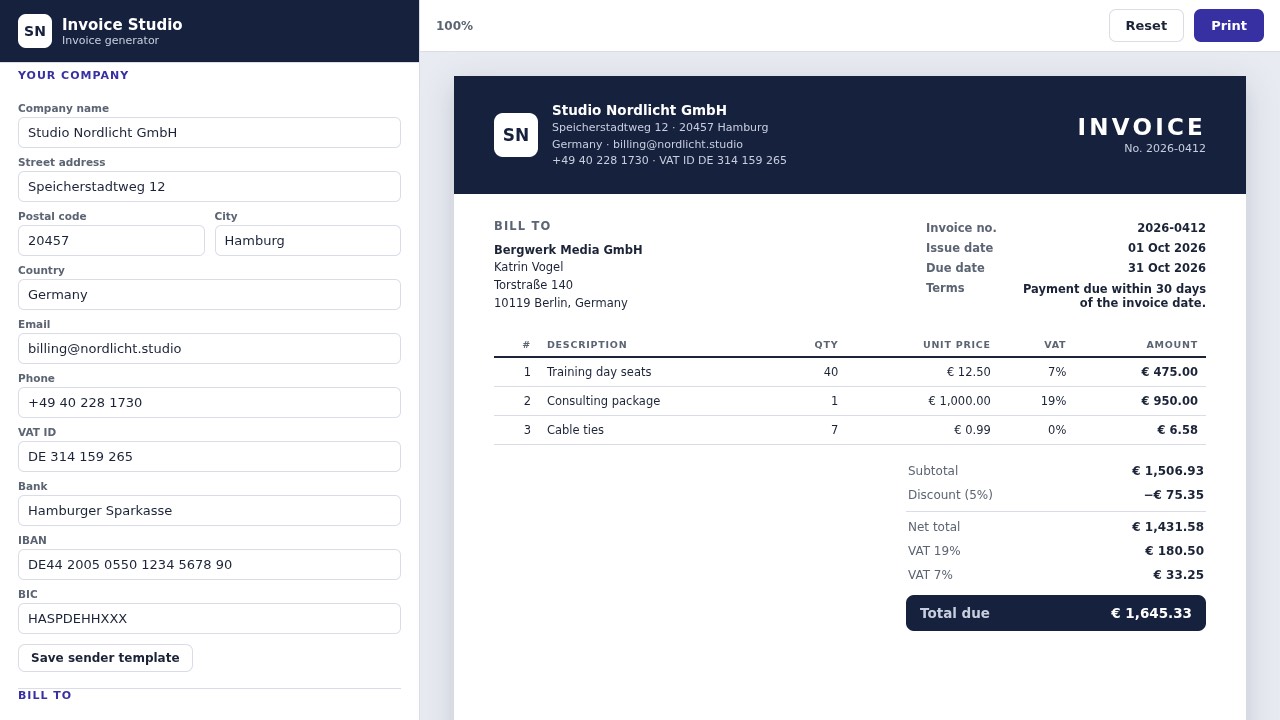
9 · Invoice generator
39/9
39/9
–
–
28/9
39/9
28/9
39/9
39/9
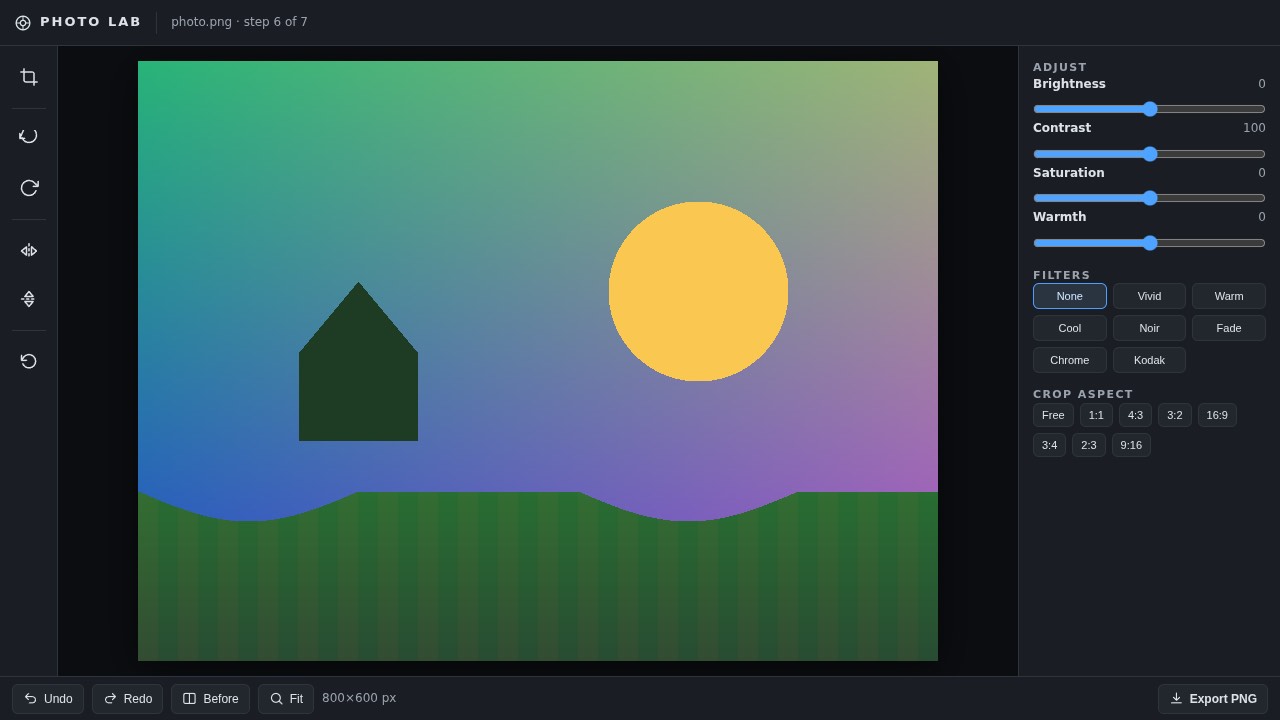
10 · Photo editor
39/9
39/9
18/9
39/9
39/9
39/9
–
–
39/9
Tier 3 = must-pass, quality and top checks all pass · Tier 2 = must-pass and quality, not all top · Tier 1 = must-pass only · – = no counted commit
Round 1 and Round 2 side by side
Same setup, two rounds
Only one setup ran identically in both rounds: llama.cpp b11151, Unsloth UD-Q3_K_XL (Qwen3.8-27B), 98,304-token window, KV q4_0, MTP draft, on the same RTX 5060 Ti 16 GB box. The time limits differ: Round 1 gave 45 minutes for every app; Round 2 gave 45 for seven tasks and 150 for tasks 2, 4 and 8. One run per task in each round — this is not a race, it shows what more time buys.
Round 1 · 45 min · checks passed
Round 2 · up to 150 min · tier
1 · Model fit calculator
16/16 · first 8 min
tier 3 q 9/9 · first 7.3 min
2 · 3D scene (150 min)
13/13 · first 12 min
tier 3 q 9/9 · first 38.9 min
3 · Product page
17/17 · first 10 min
tier 3 q 10/10 · first 10.2 min
4 · Platformer game (150 min)
18/18 · first 15 min
tier 3 q 9/9 · first 12.9 min
5 · Time tracker
15/15 · first 19 min
tier 3 q 10/10 · first 27.4 min
6 · Dashboard
12/12 · first 8 min
tier 3 q 9/9 · first 22 min
7 · Interactive explainer
15/15 · first 12 min
tier 3 q 9/9 · first 28.4 min
8 · Bird flock (150 min)
14/14 · first 25 min
tier 1 q 7/8 · first 88.5 min
9 · Invoice generator
13/13 · first 18 min
no counted commit
10 · Photo editor
14/14 · first 20 min
tier 3 q 9/9 · first 32 min
Documentation
Notes & checks
Late regressions, the cross-run interference audit (pkill), what was re-scored and re-run, and how tiers and the counted commit are defined.
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
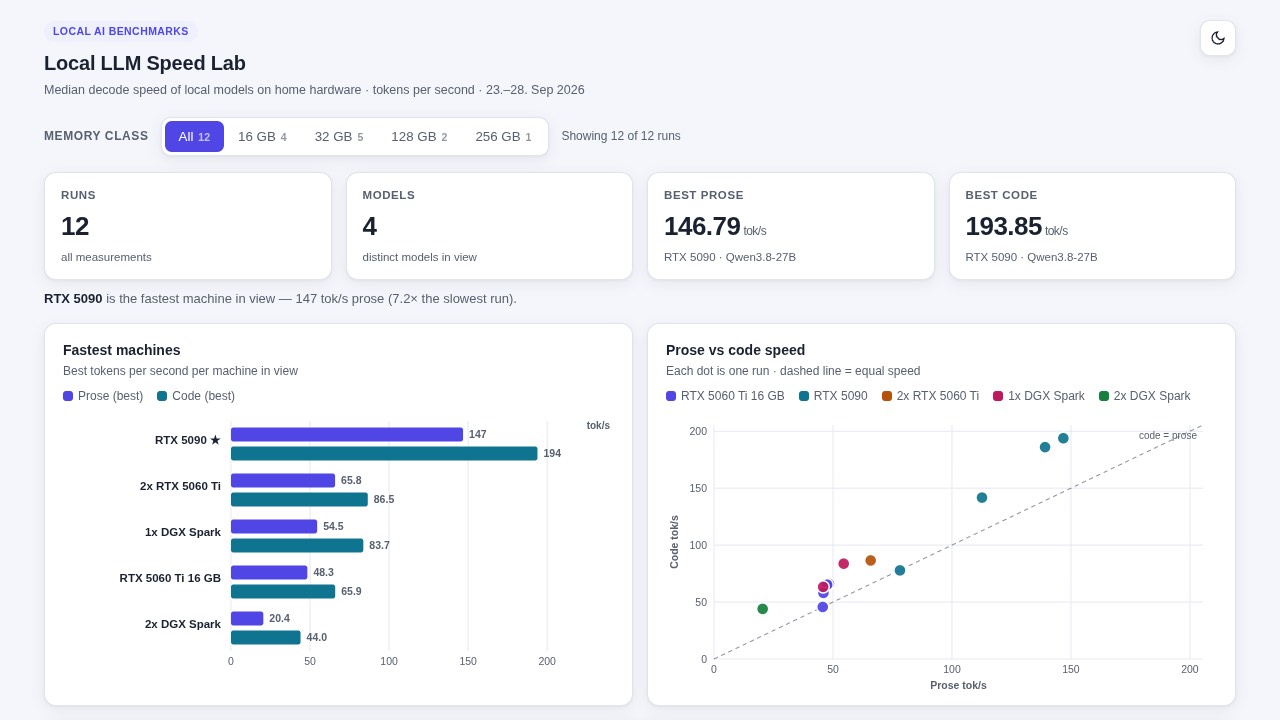 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
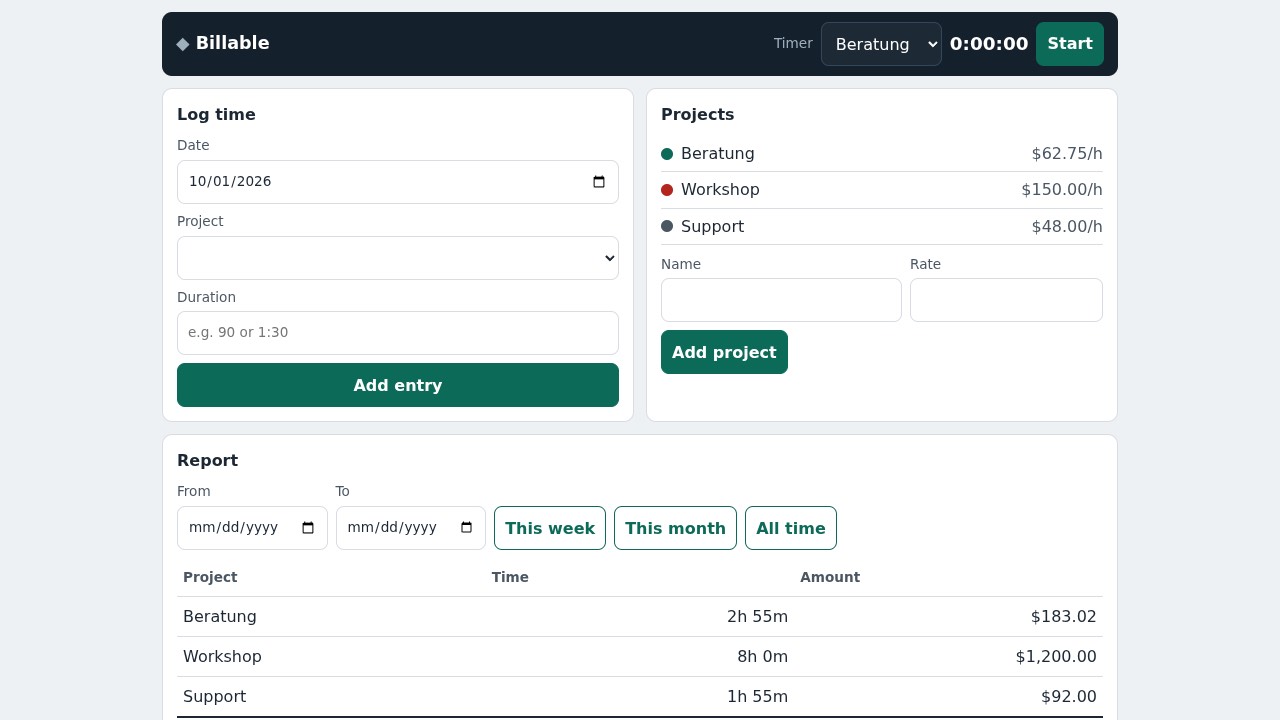 Open app ↗
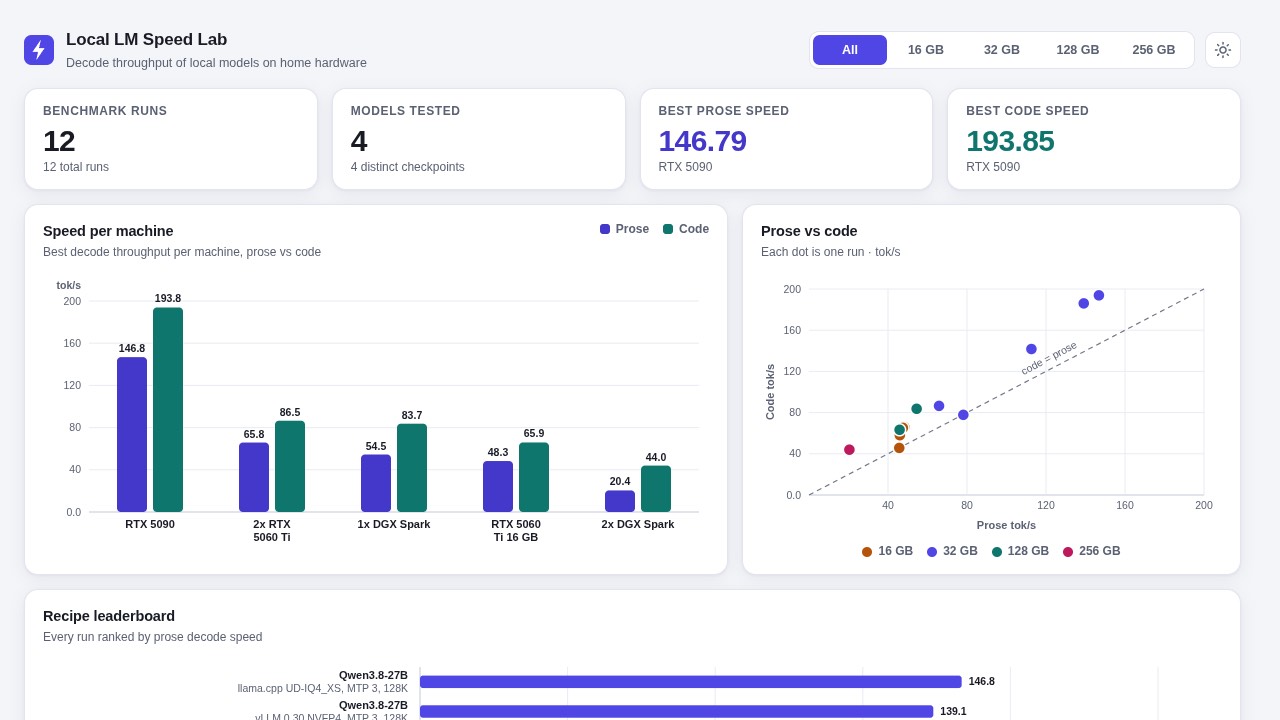 Open app ↗
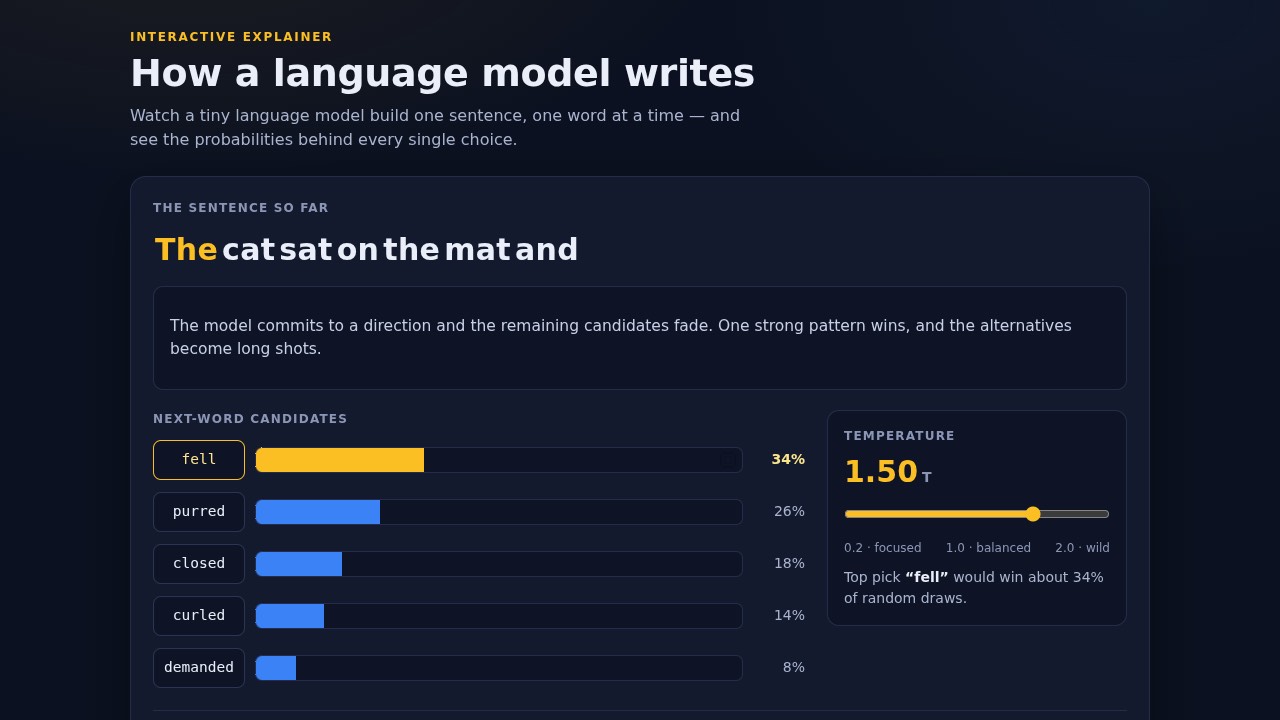 Open app ↗
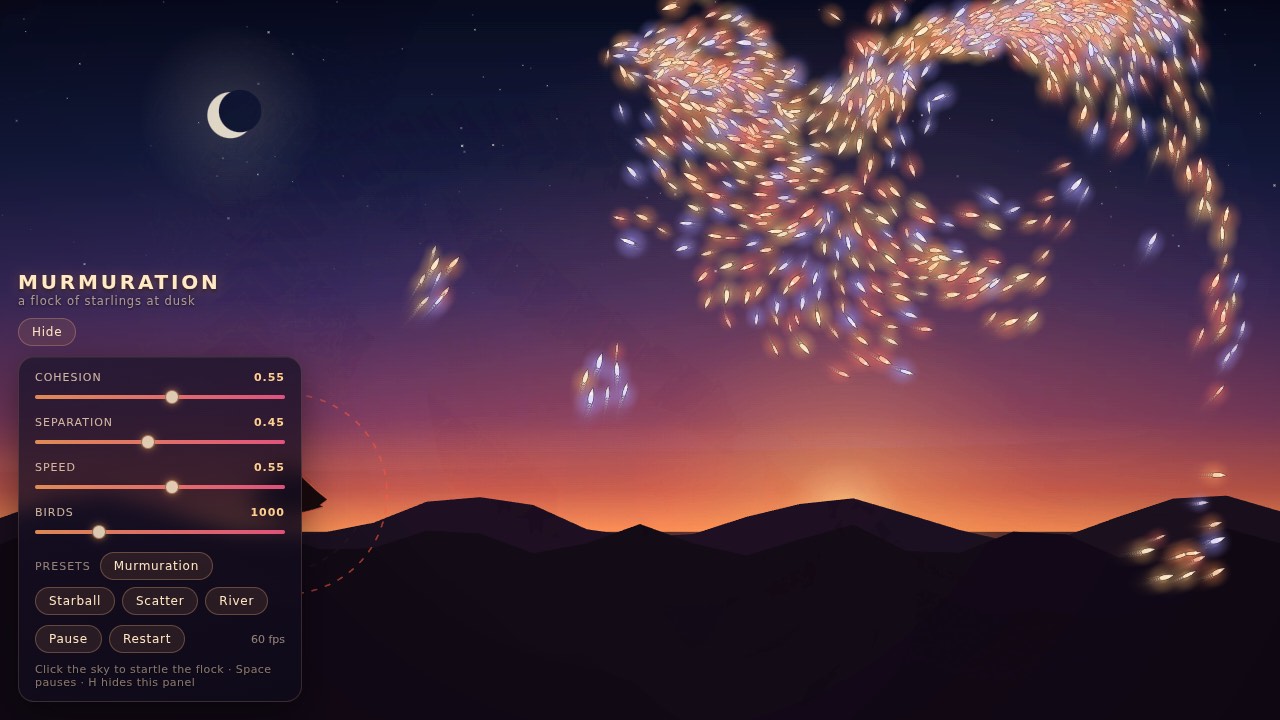 Open app ↗
 Open app ↗