 Open app ↗
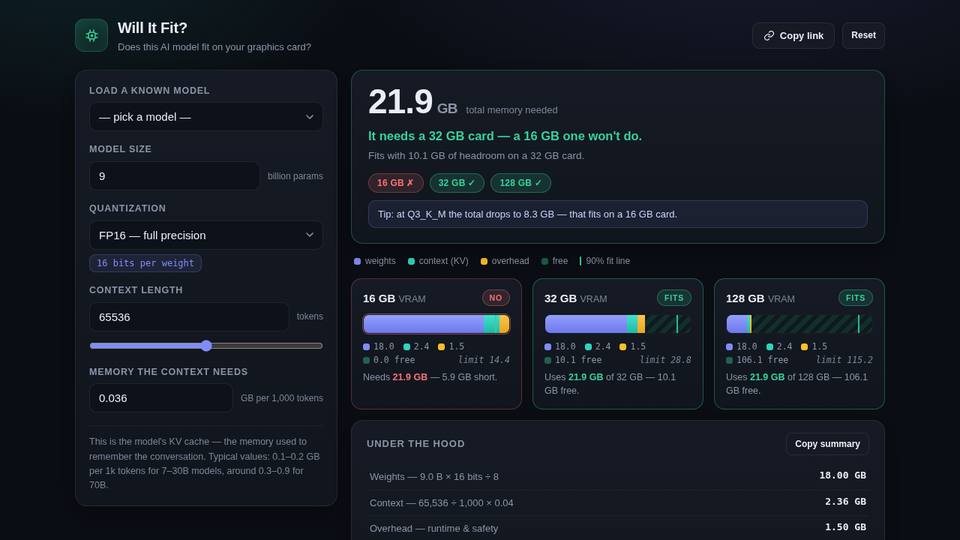
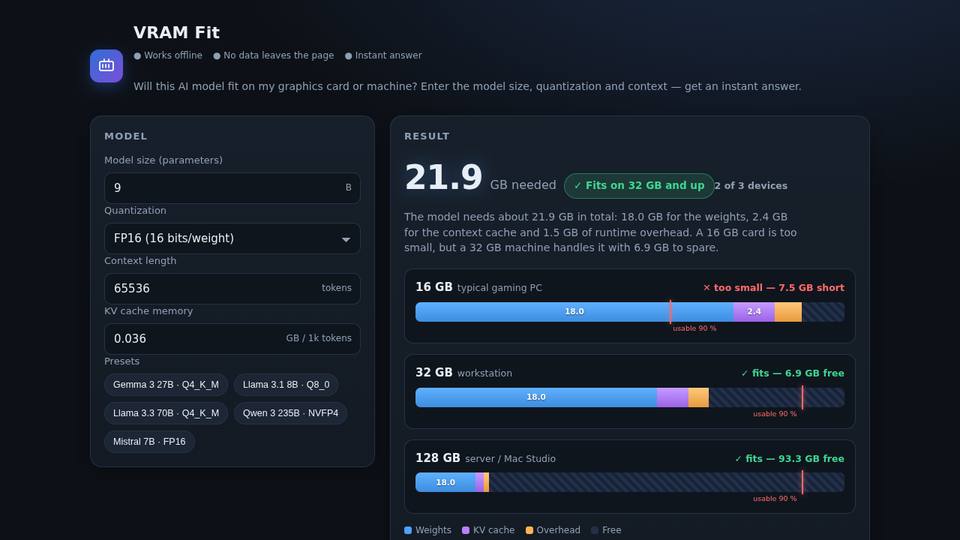
1 · Model fit calculator
Will this AI model fit on my graphics card?
All 16 checks passedFirst working version after 8 min
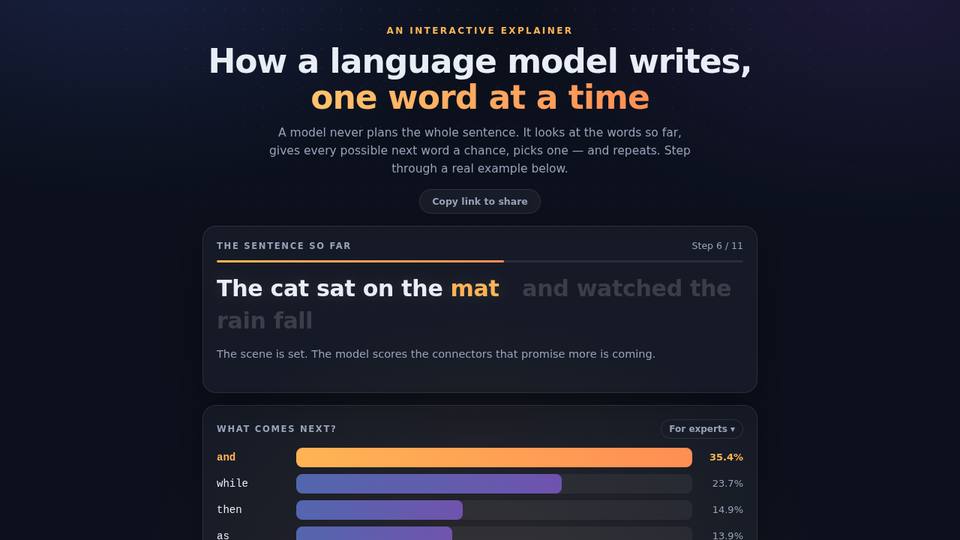
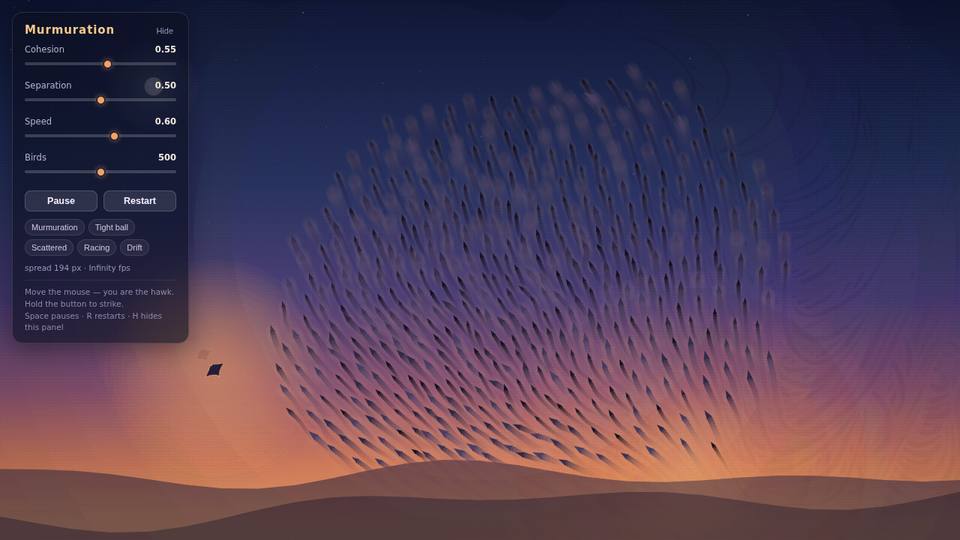
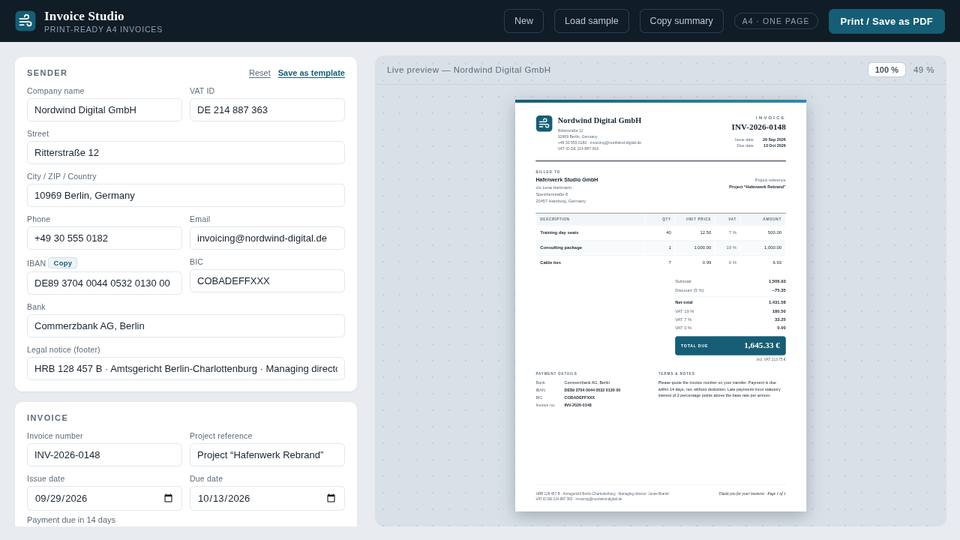
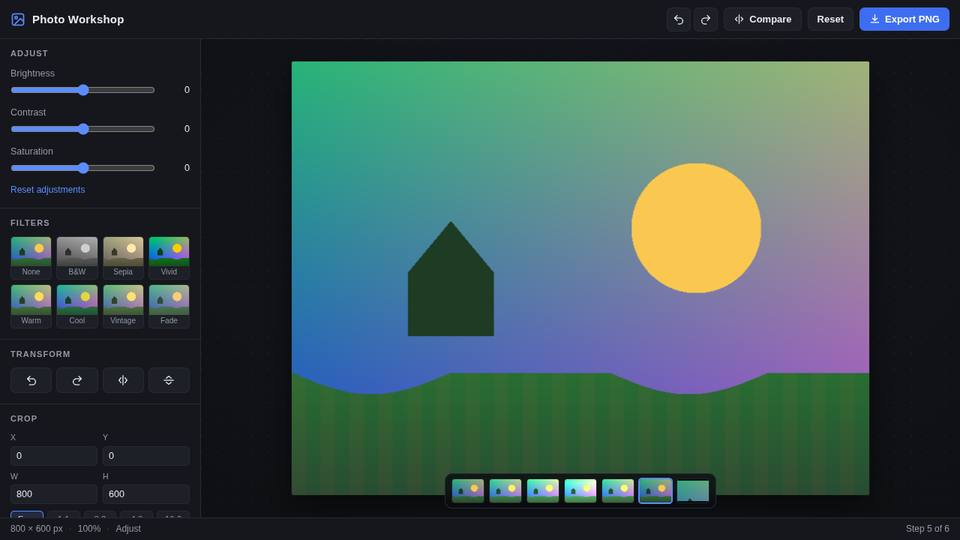
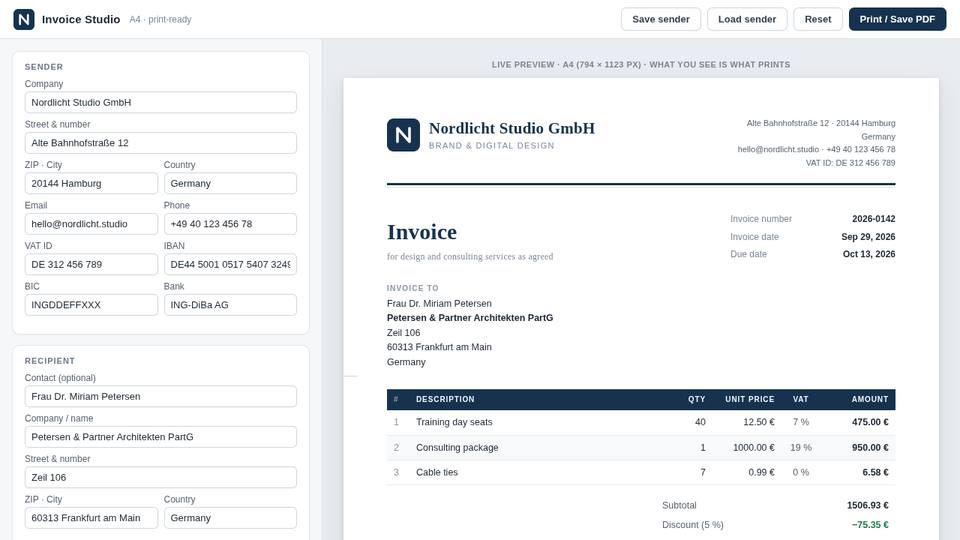
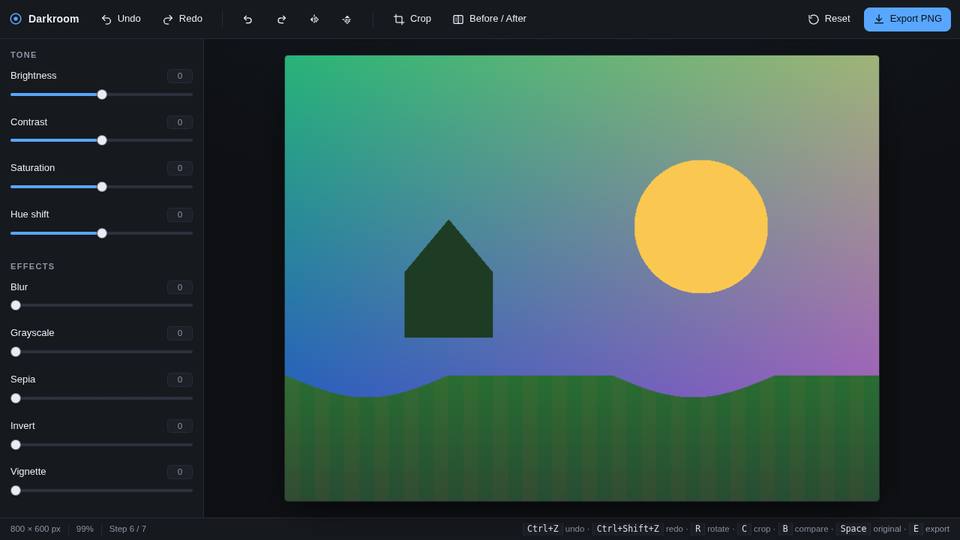
Every contender got the exact same 10 prompts and worked alone in a coding agent: wrote the code, ran it in a real browser, fixed its own bugs. Then an automatic checker clicked through every app. Round 1 gave 45 minutes per app; Round 2 gives up to 150 and tests recipes by @MiaAI_lab and @ashxhart.
llama.cpp · Unsloth UD-Q3_K_XL · 96K context · KV cache q4_0 · MTP 2
Open app ↗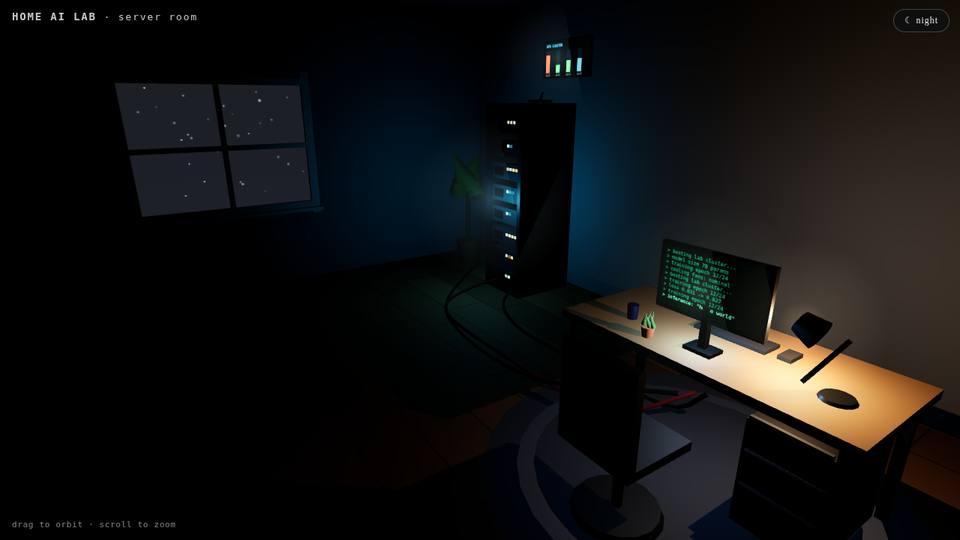 Open app ↗
 Open app ↗
 Open app ↗
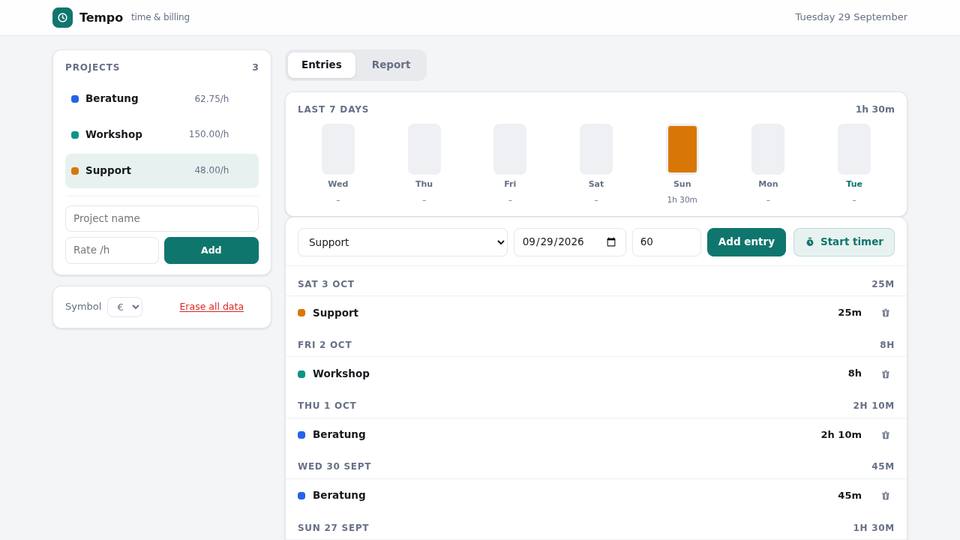 Open app ↗
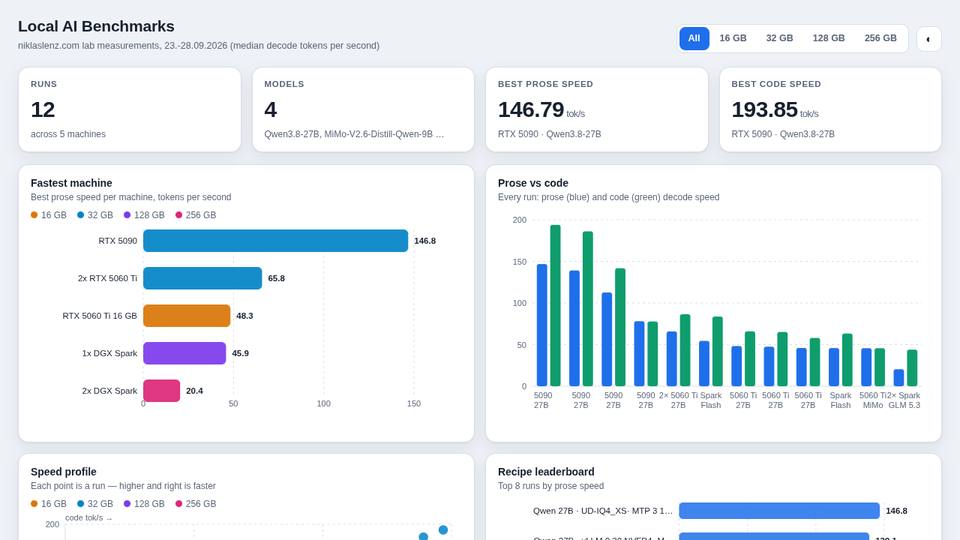 Open app ↗
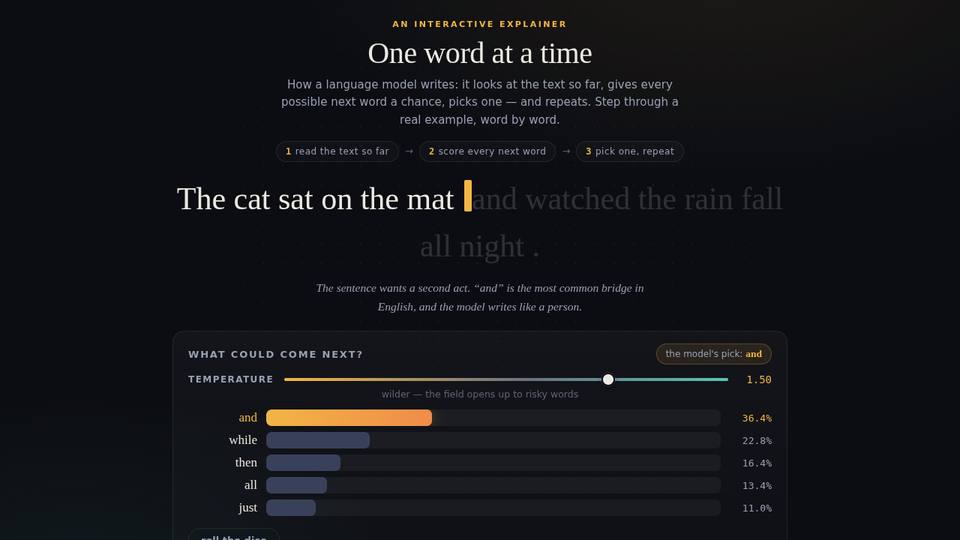 Open app ↗
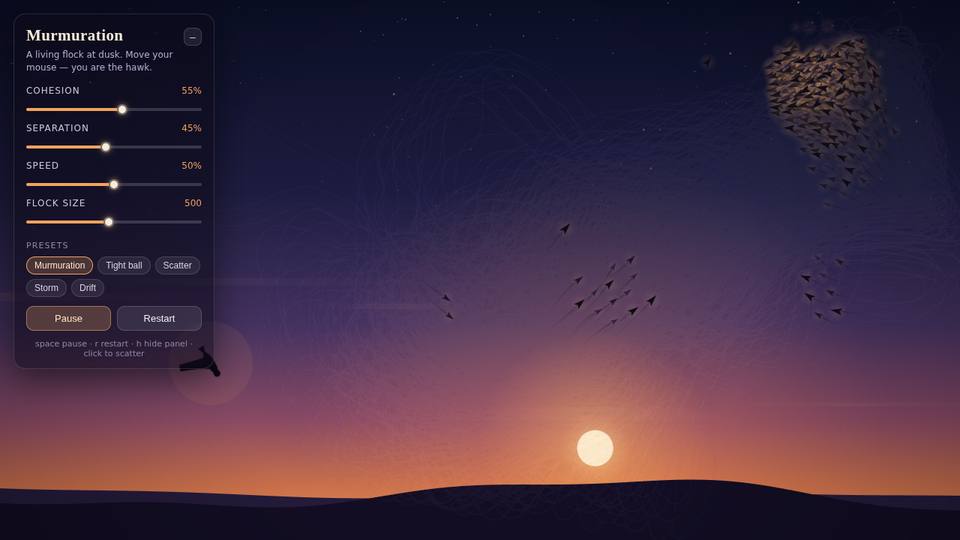 Open app ↗
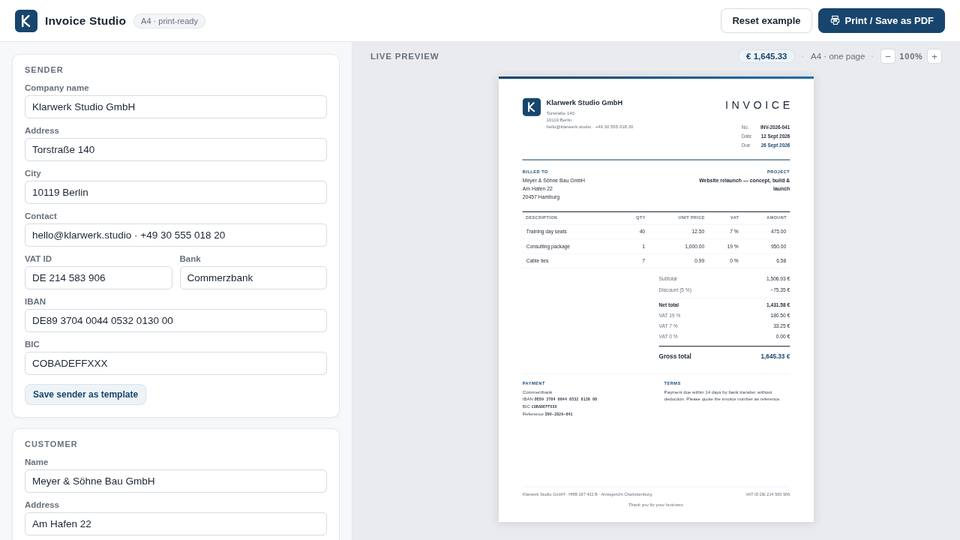 Open app ↗
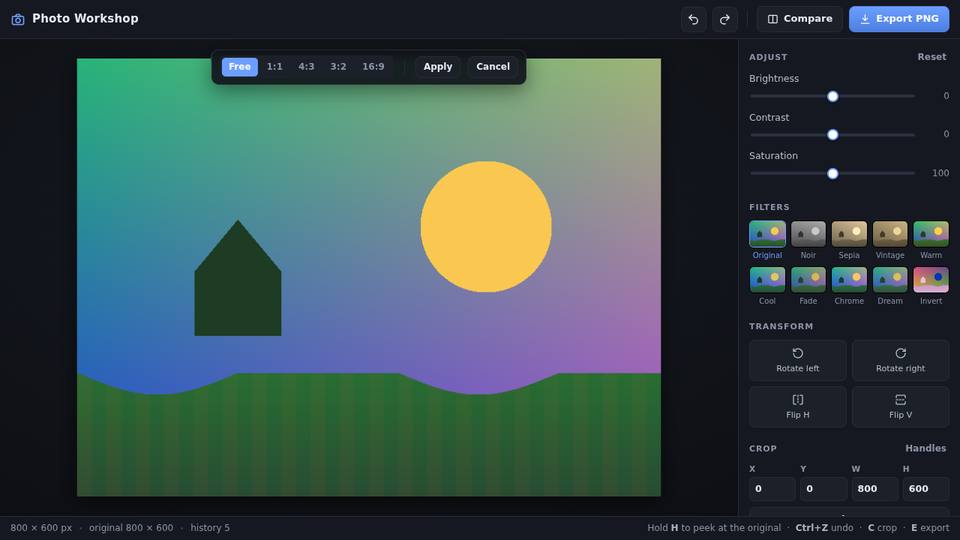 Open app ↗
llama.cpp · Unsloth UD-IQ4_XS · 128K context · KV cache q4_0 · MTP 3
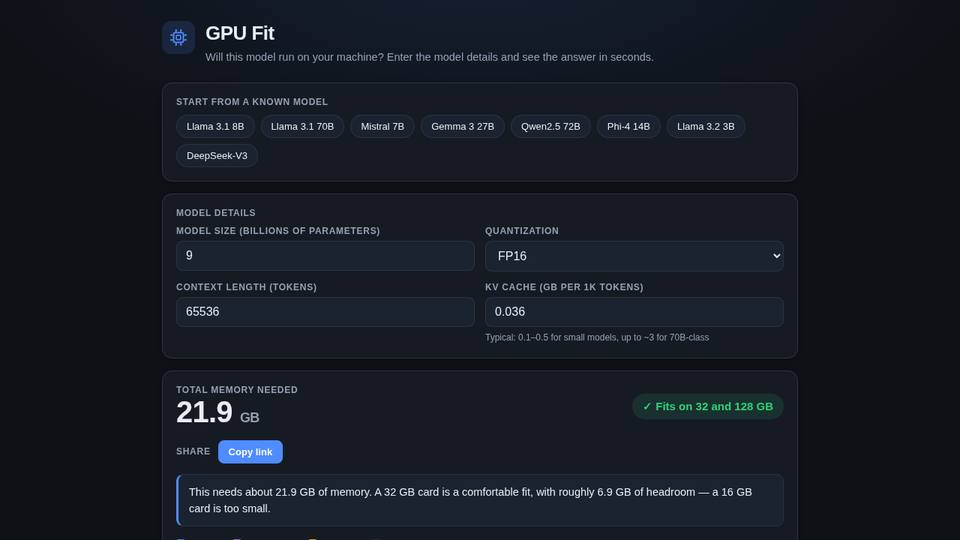 Open app ↗
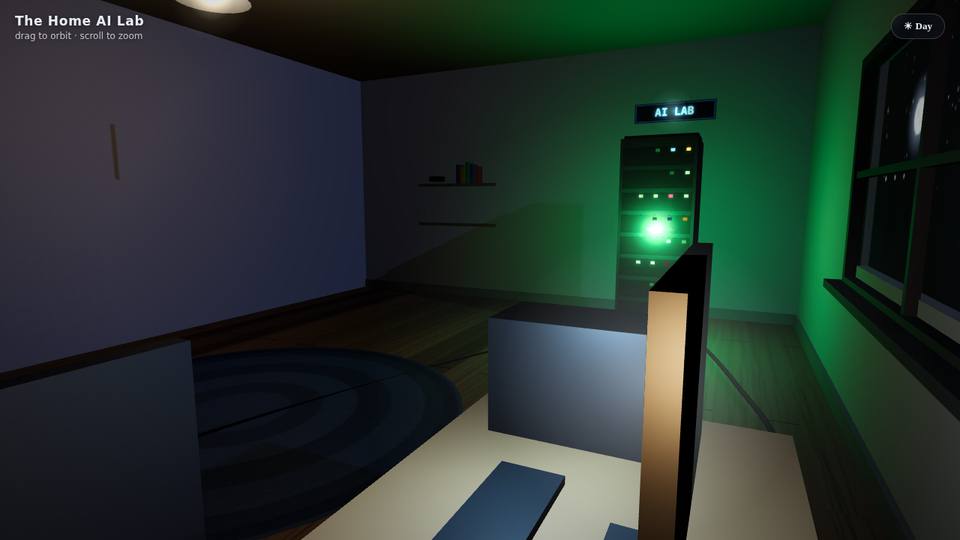 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
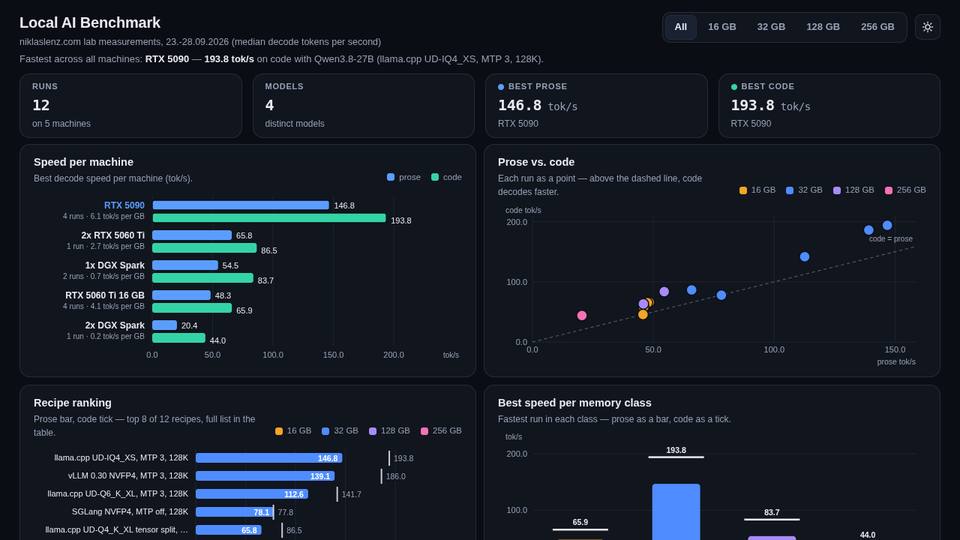 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
vLLM · NVFP4 · 262K context · MTP 3
Runs on an older version of @MiaAI_lab's single-box kit (commit 6b50864, 19 Sep), 13 commits behind her main at run time. I changed two things: KV cache BF16 instead of her default FP8, and CHAT_TEMPLATE pointed to the template file in her repo (her default leaves it empty). So this is not her stock recipe, and her current version may be faster.
 Open app ↗
 Open app ↗
 Open app ↗
 Open app ↗
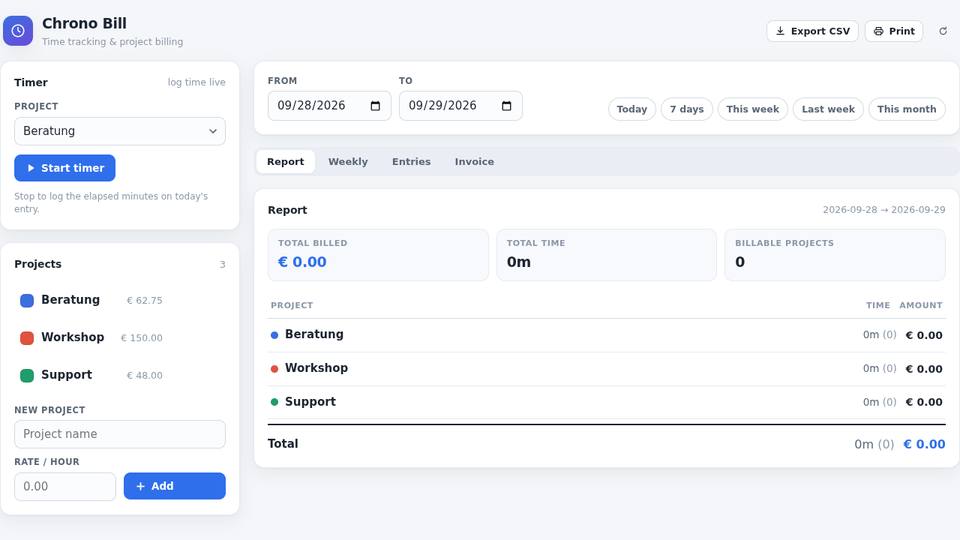 Open app ↗
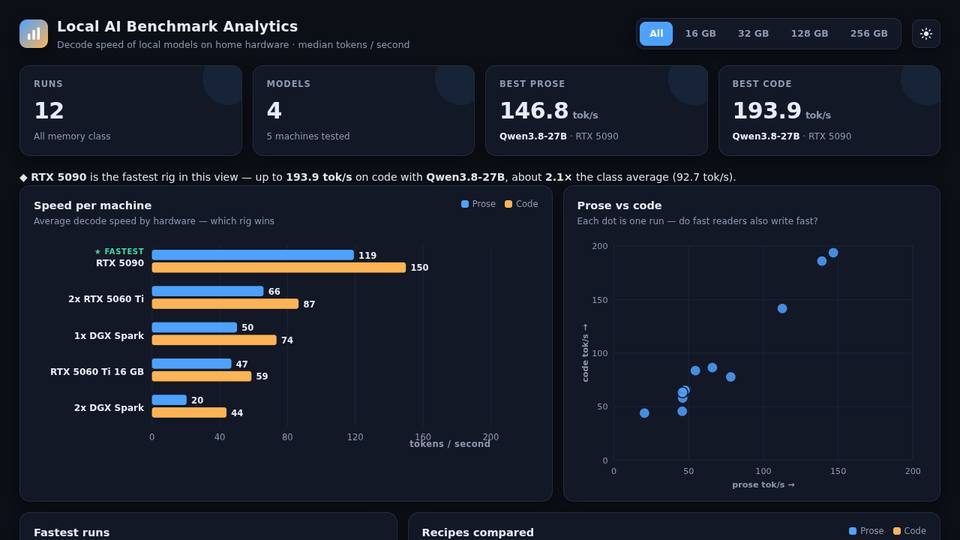 Open app ↗
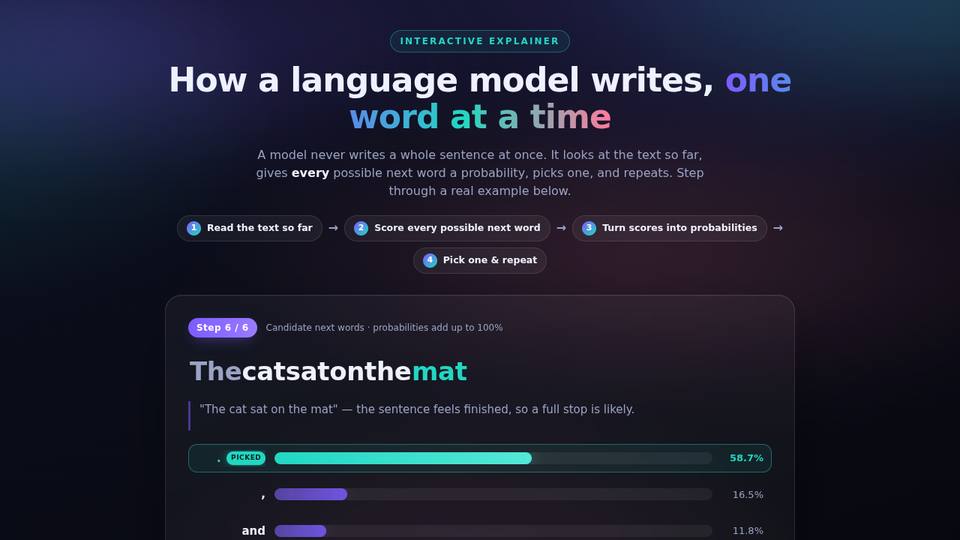 Open app ↗
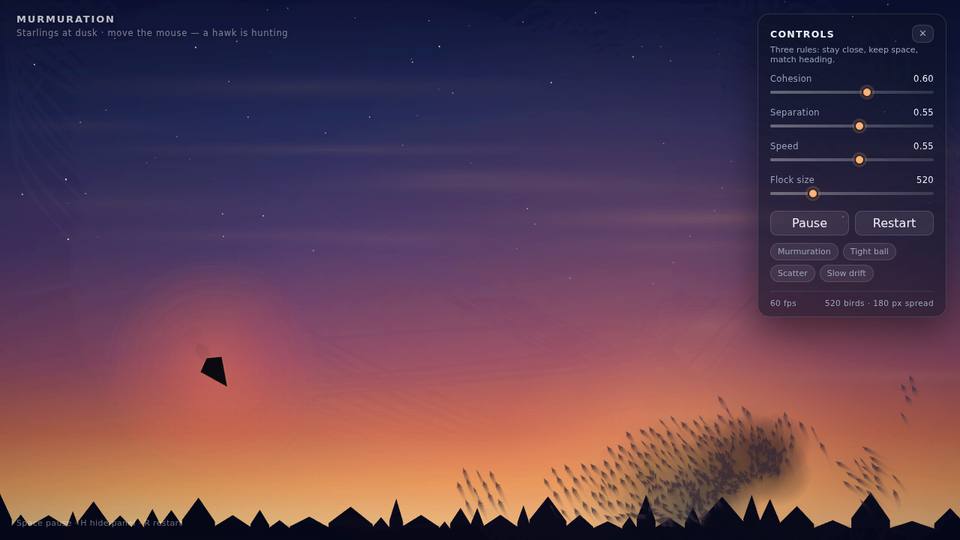 Open app ↗
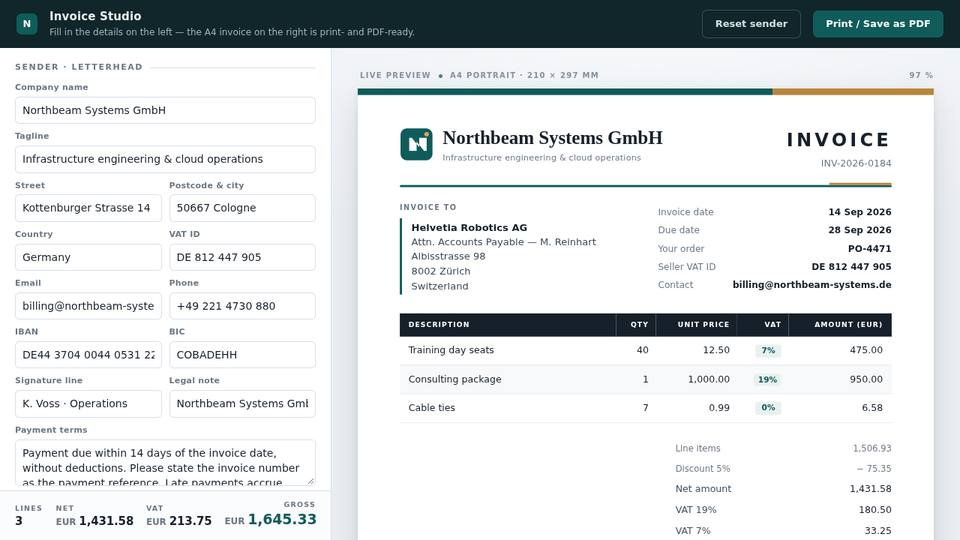 Open app ↗
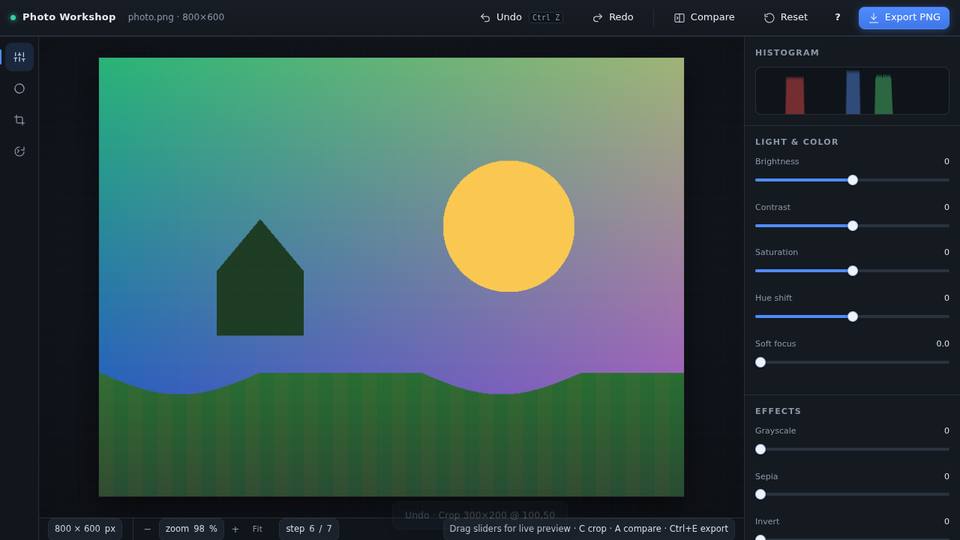 Open app ↗
vLLM · Unsloth NVFP4 · 128K context · no speculative decoding
The box froze several times during the night. I moved apps 8 and 10 to two other boxes of the same type with the same setup, so times are not shown.
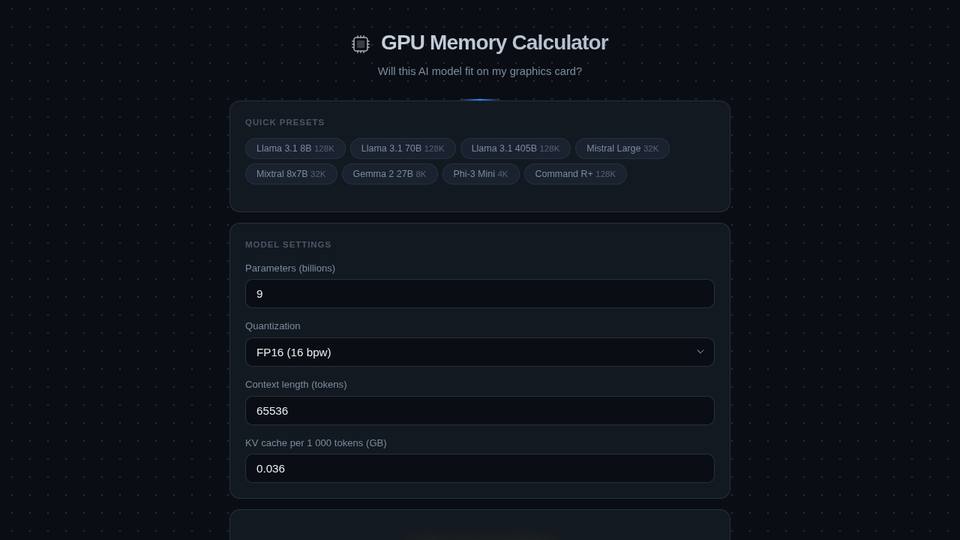 Open app ↗
 Open app ↗
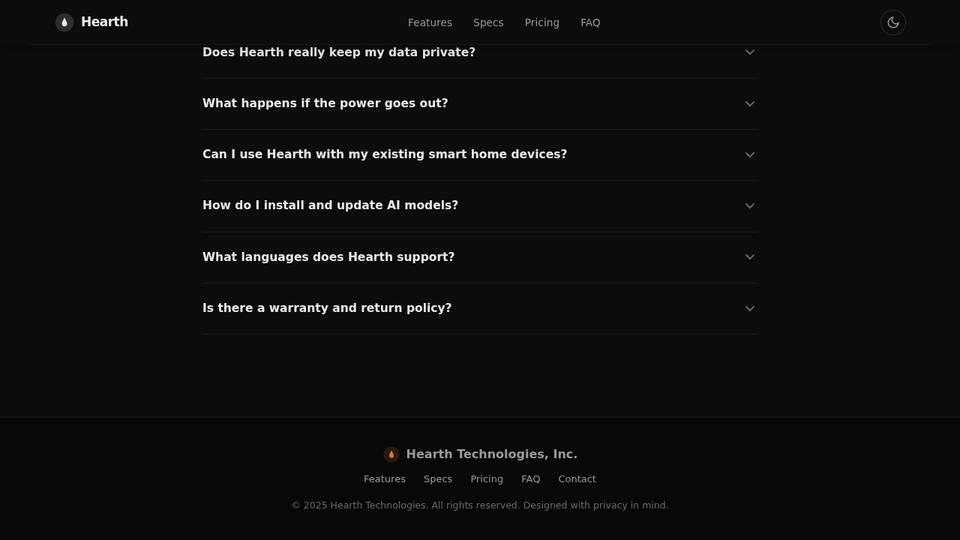 Open app ↗
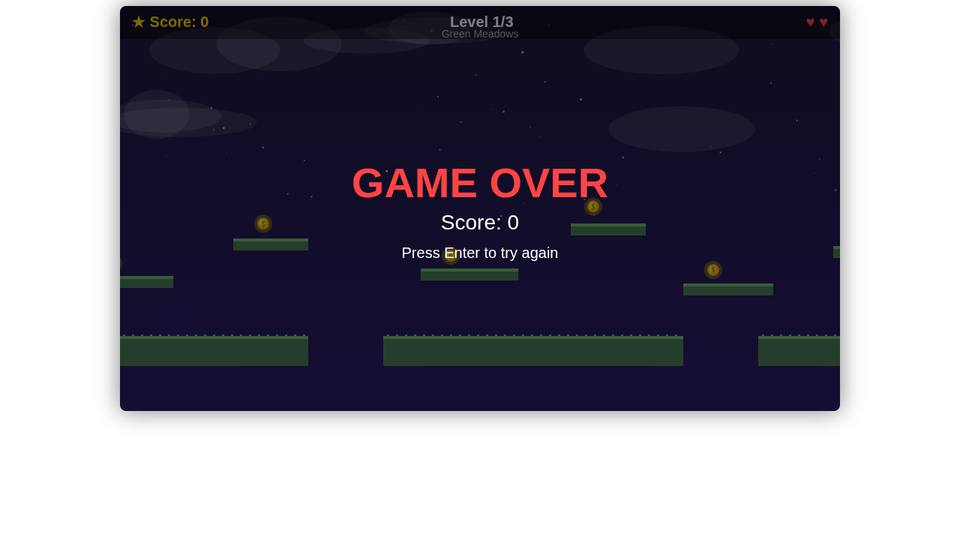 Open app ↗
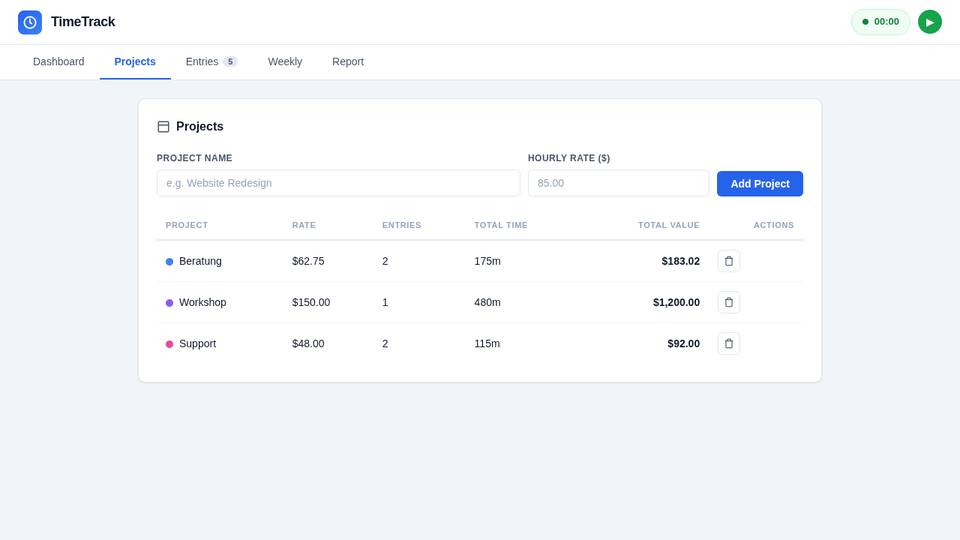 Open app ↗
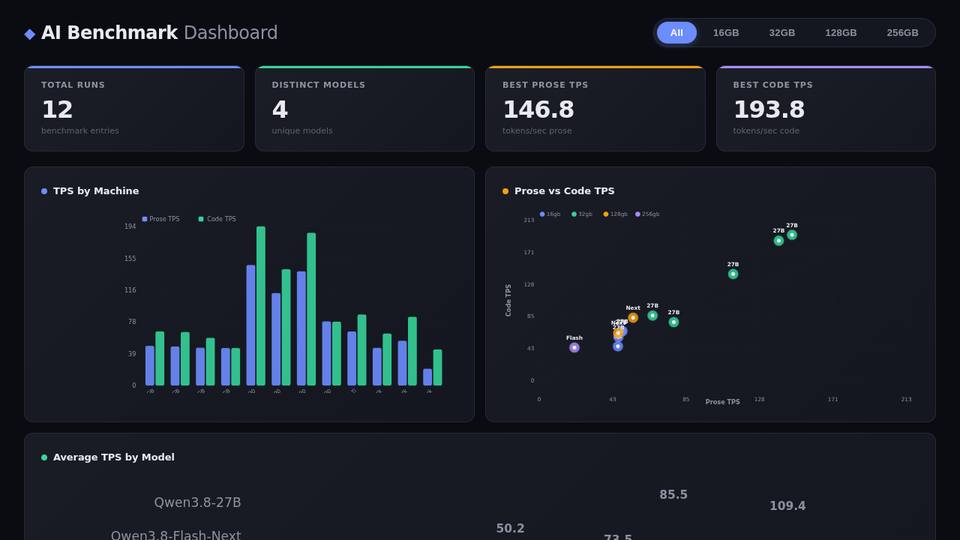 Open app ↗
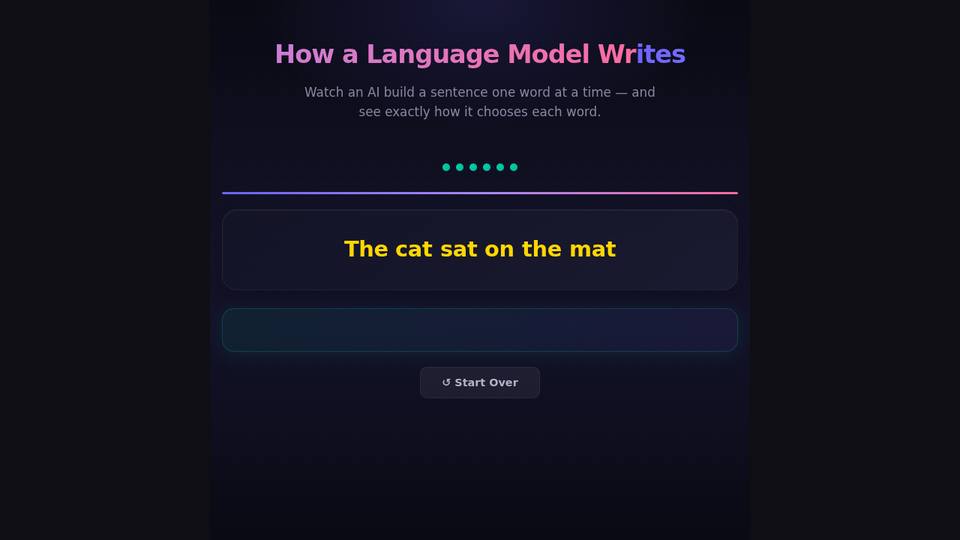 Open app ↗
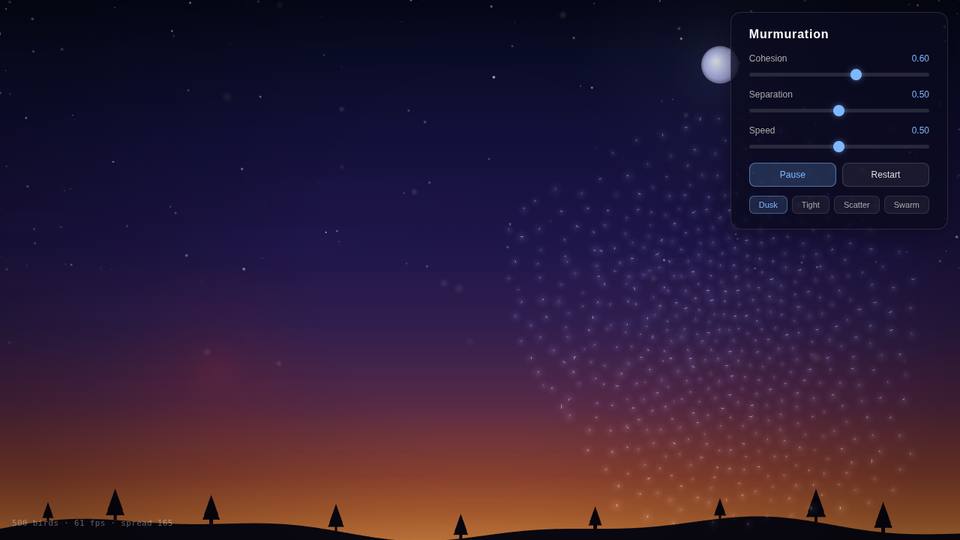 Open app ↗
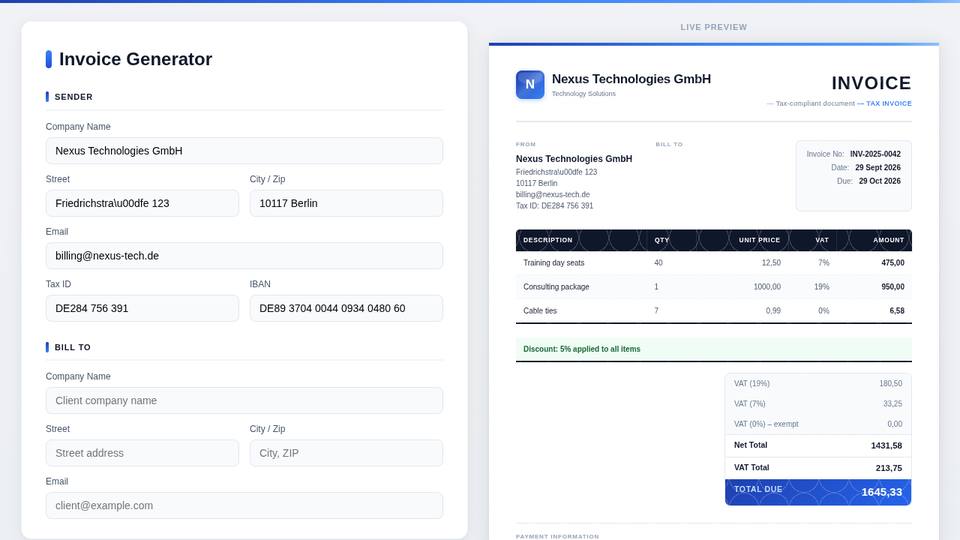 Open app ↗
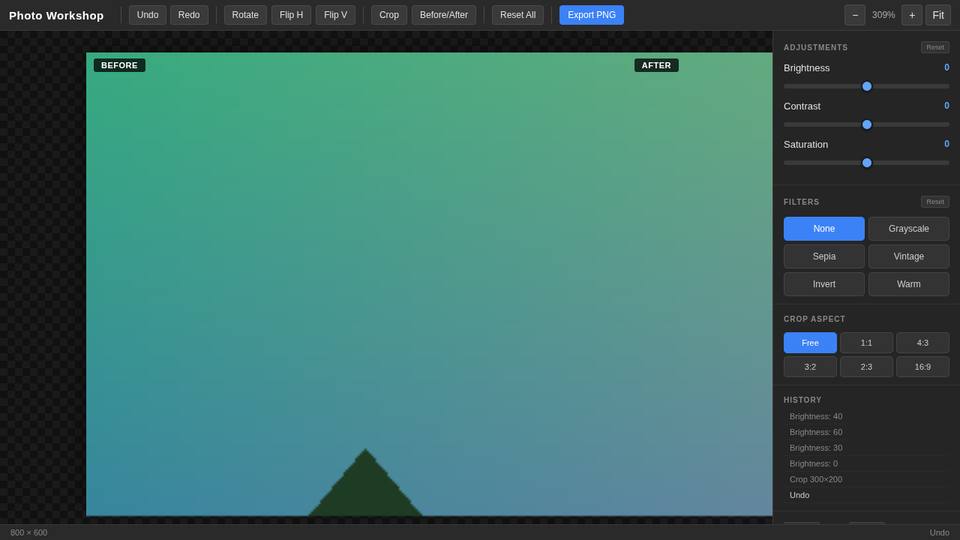 Open app ↗
vLLM · EXL3 4bpw · tensor parallel 2 · MTP 2 · 128K context
Runs on an older version of @MiaAI_lab's 2-box kit (c1b7d4c, 22 Sep) with my own changes: MTP 2 instead of DFlash2, KV cache fixed at 3 GiB, max 2 sequences. Not her current default.
Apps 3 and 4 were never built. The engine connection dropped on every request and the model returned no tokens. That is my setup failing, not GLM or Mia's kit. I will rerun both. 8 of 8 completed apps passed every check.
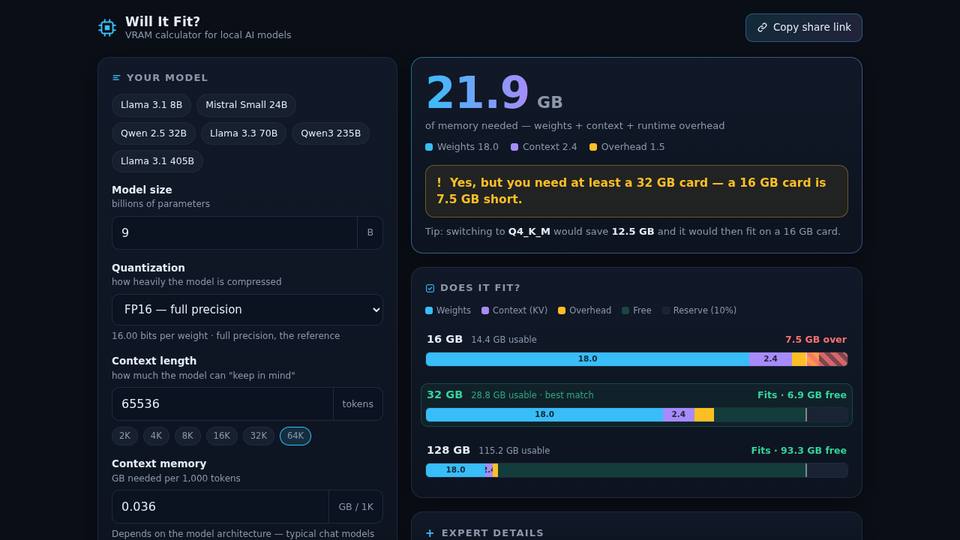 Open app ↗
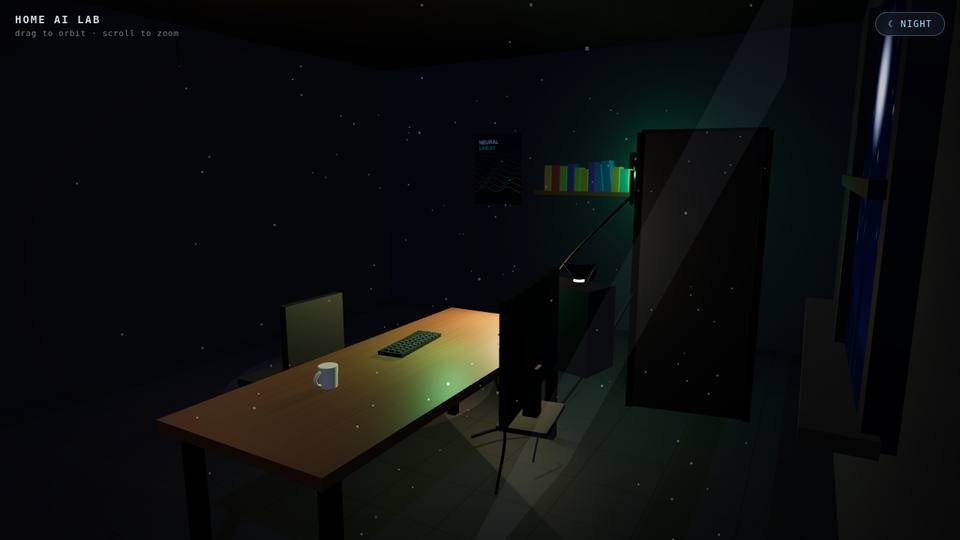 Open app ↗
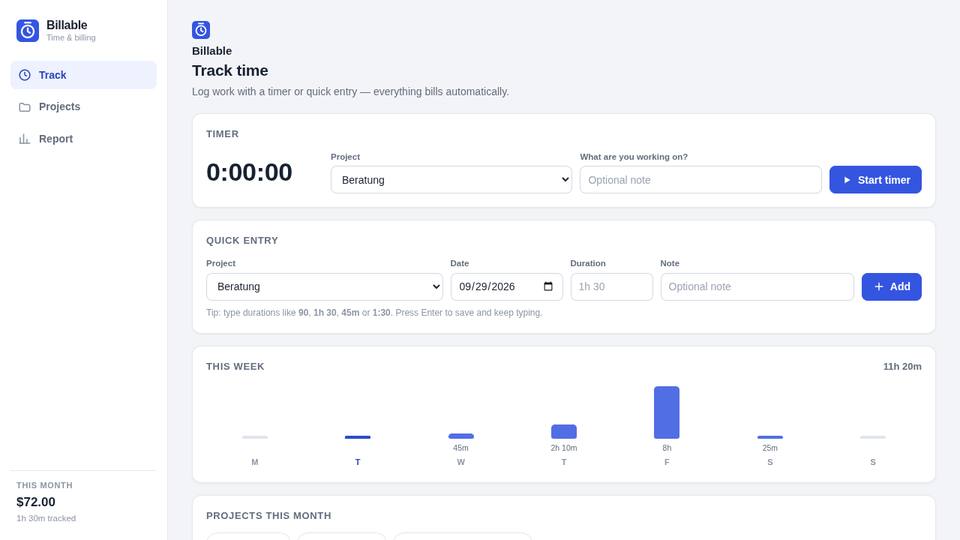 Open app ↗
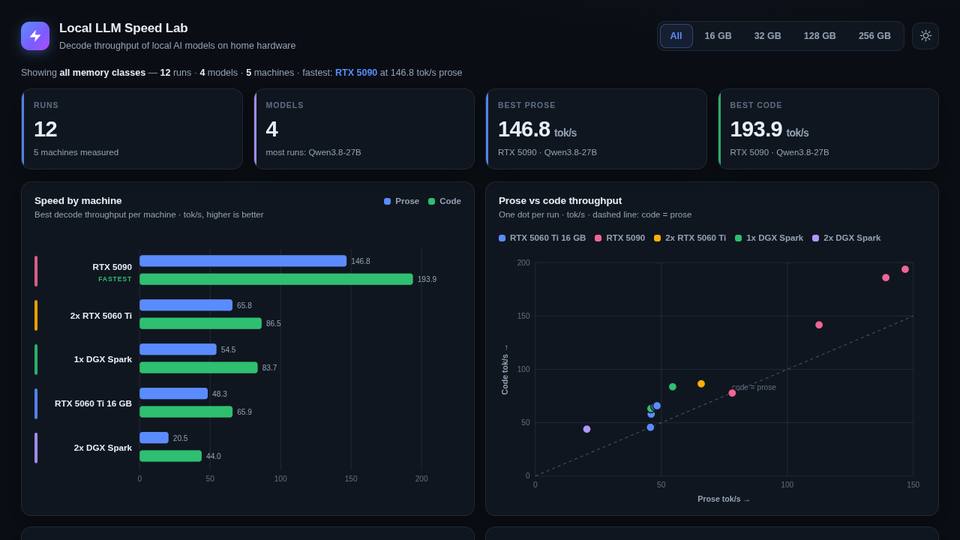 Open app ↗
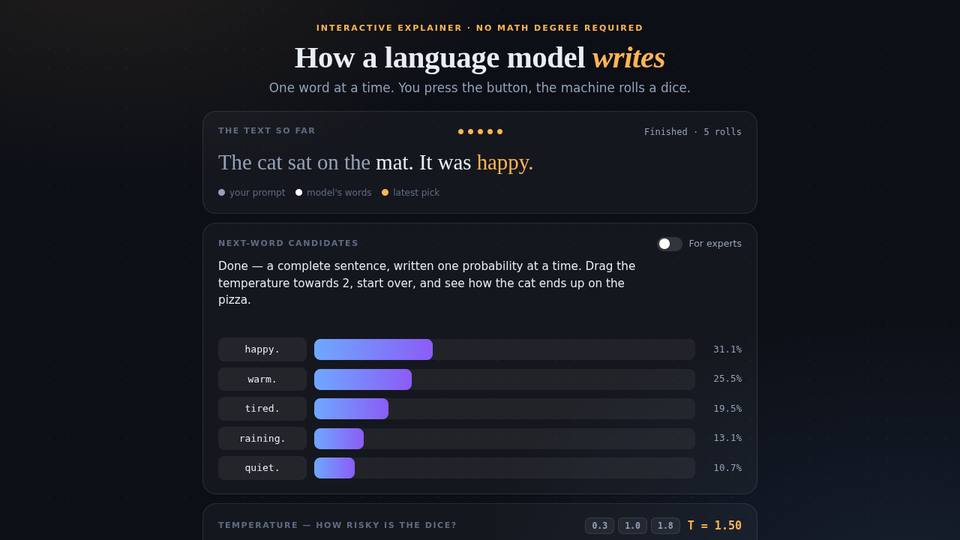 Open app ↗
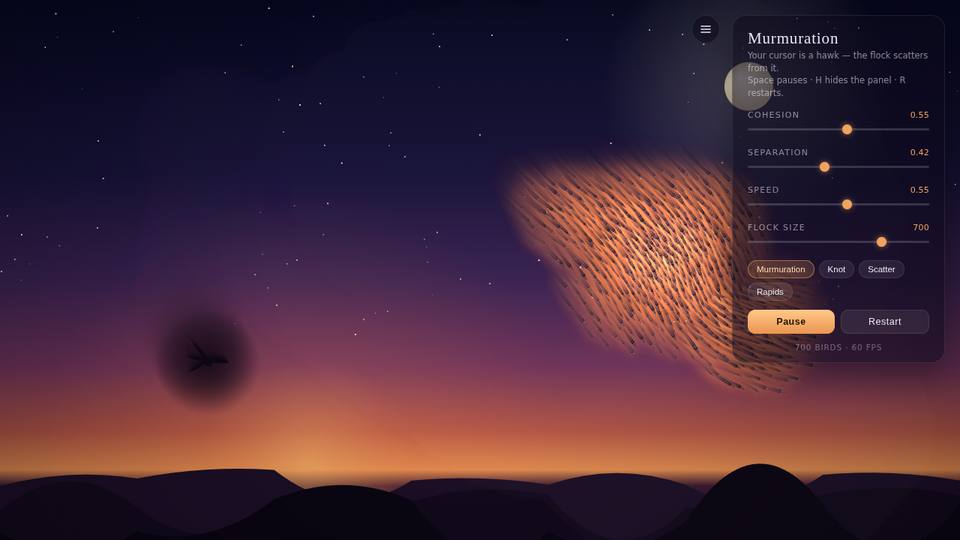 Open app ↗
 Open app ↗
 Open app ↗
Pick a task and see what each machine made of the same brief (Round 1).
Cell: automatic checks passed (45 min per app, one run per task).
| Qwen3.8 27B RTX 5060 Ti | Qwen3.8 27B RTX 5090 | Qwen3.8 Flash-Next 1× GB10 box (Lenovo ThinkStation PGX) | Qwen3.6 35B-A3B 1× GB10 box (Gigabyte AI TOP ATOM) | GLM-5.3-Flash 2× GB10 boxes (ASUS Ascent GX10) | |
|---|---|---|---|---|---|
| 1 · Model fit calculator | 16/16 | 16/16 | 16/16 | 16/16 | 16/16 |
| 2 · 3D scene | 13/13 | 13/13 | 13/13 | 13/13 | 13/13 |
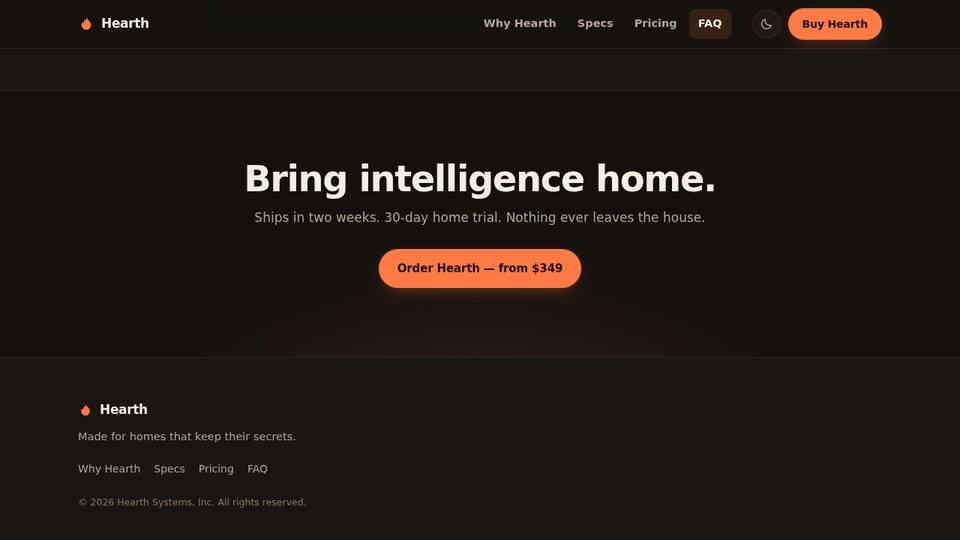
| 3 · Product page | 17/17 | 17/17 | 17/17 | 17/17 | – |
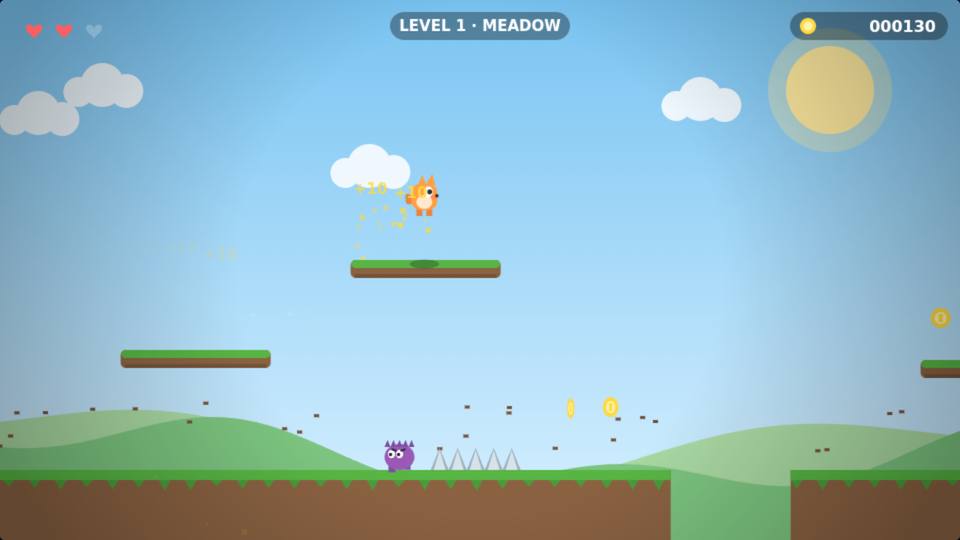
| 4 · Platformer game | 18/18 | 18/18 | 18/18 | 17/18 | – |
| 5 · Time tracker | 15/15 | 15/15 | 15/15 | 15/15 | 15/15 |
| 6 · Dashboard | 12/12 | 12/12 | 12/12 | 12/12 | 12/12 |
| 7 · Interactive explainer | 15/15 | 15/15 | 15/15 | 15/15 | 15/15 |
| 8 · Bird flock | 14/14 | 14/14 | 14/14 | 14/14 | 14/14 |
| 9 · Invoice generator | 13/13 | 13/13 | 13/13 | 13/13 | 13/13 |
| 10 · Photo editor | 14/14 | 14/14 | 14/14 | 14/14 | 14/14 |
The benchmark runs, the checks and this page were set up by AI agents working for me. The apps on this page were written entirely by the local models named above.